Computer Vision — Lecture 4
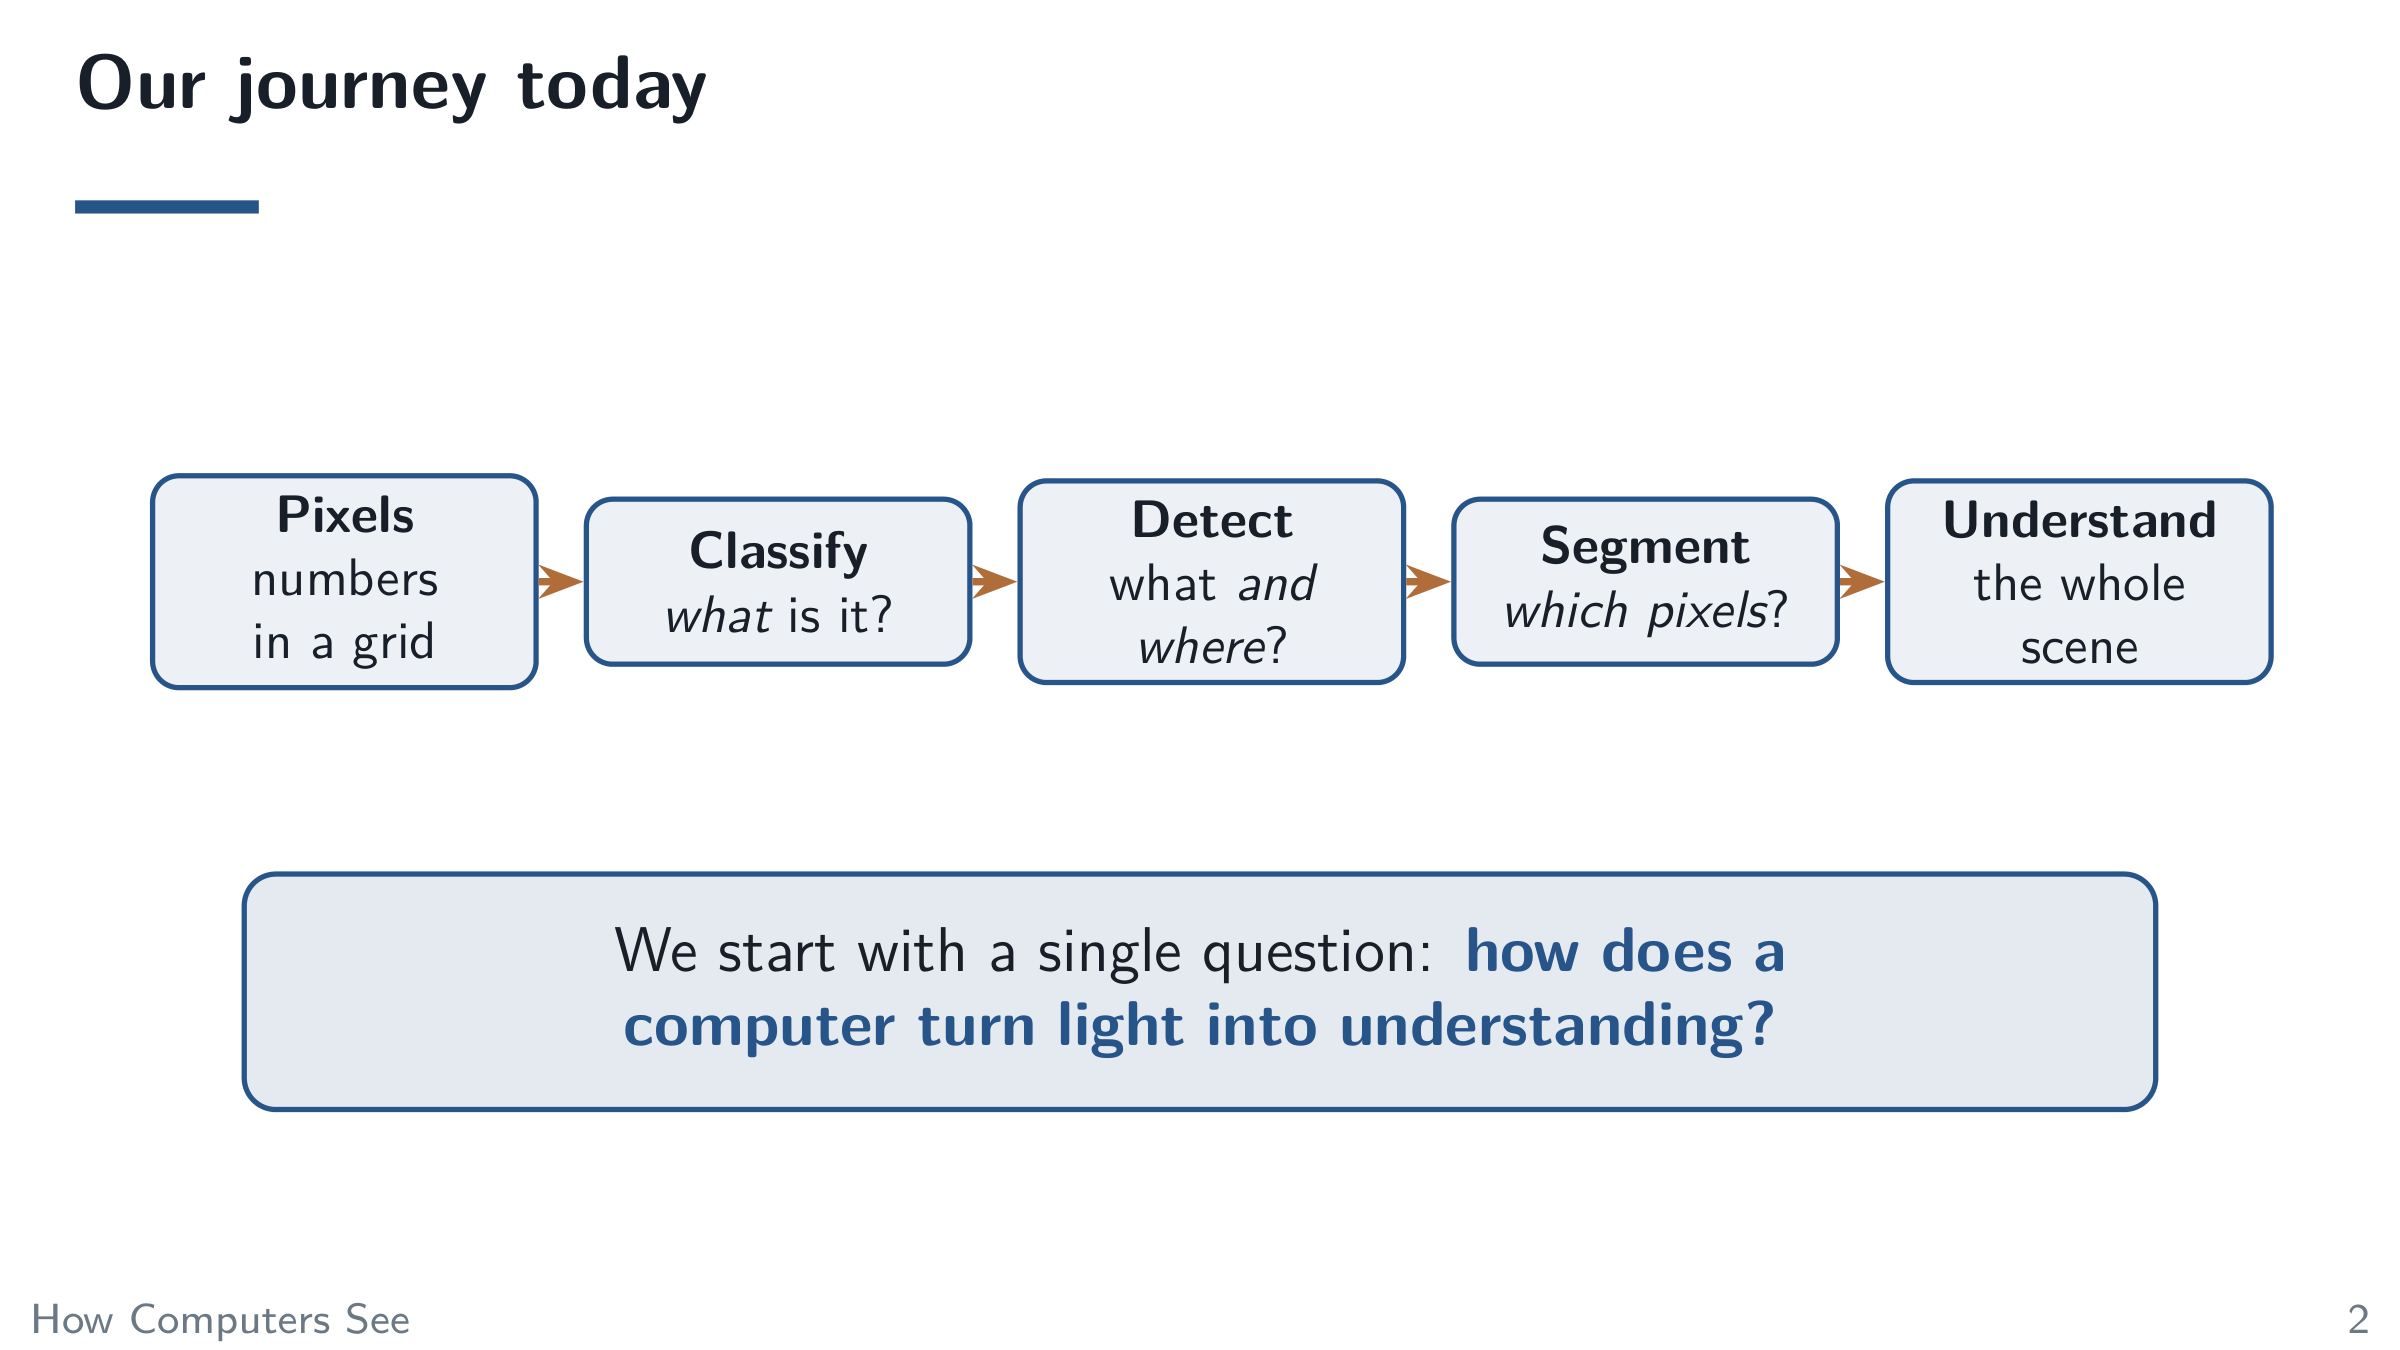
Our journey today
What is Computer Vision?
Computer vision is teaching
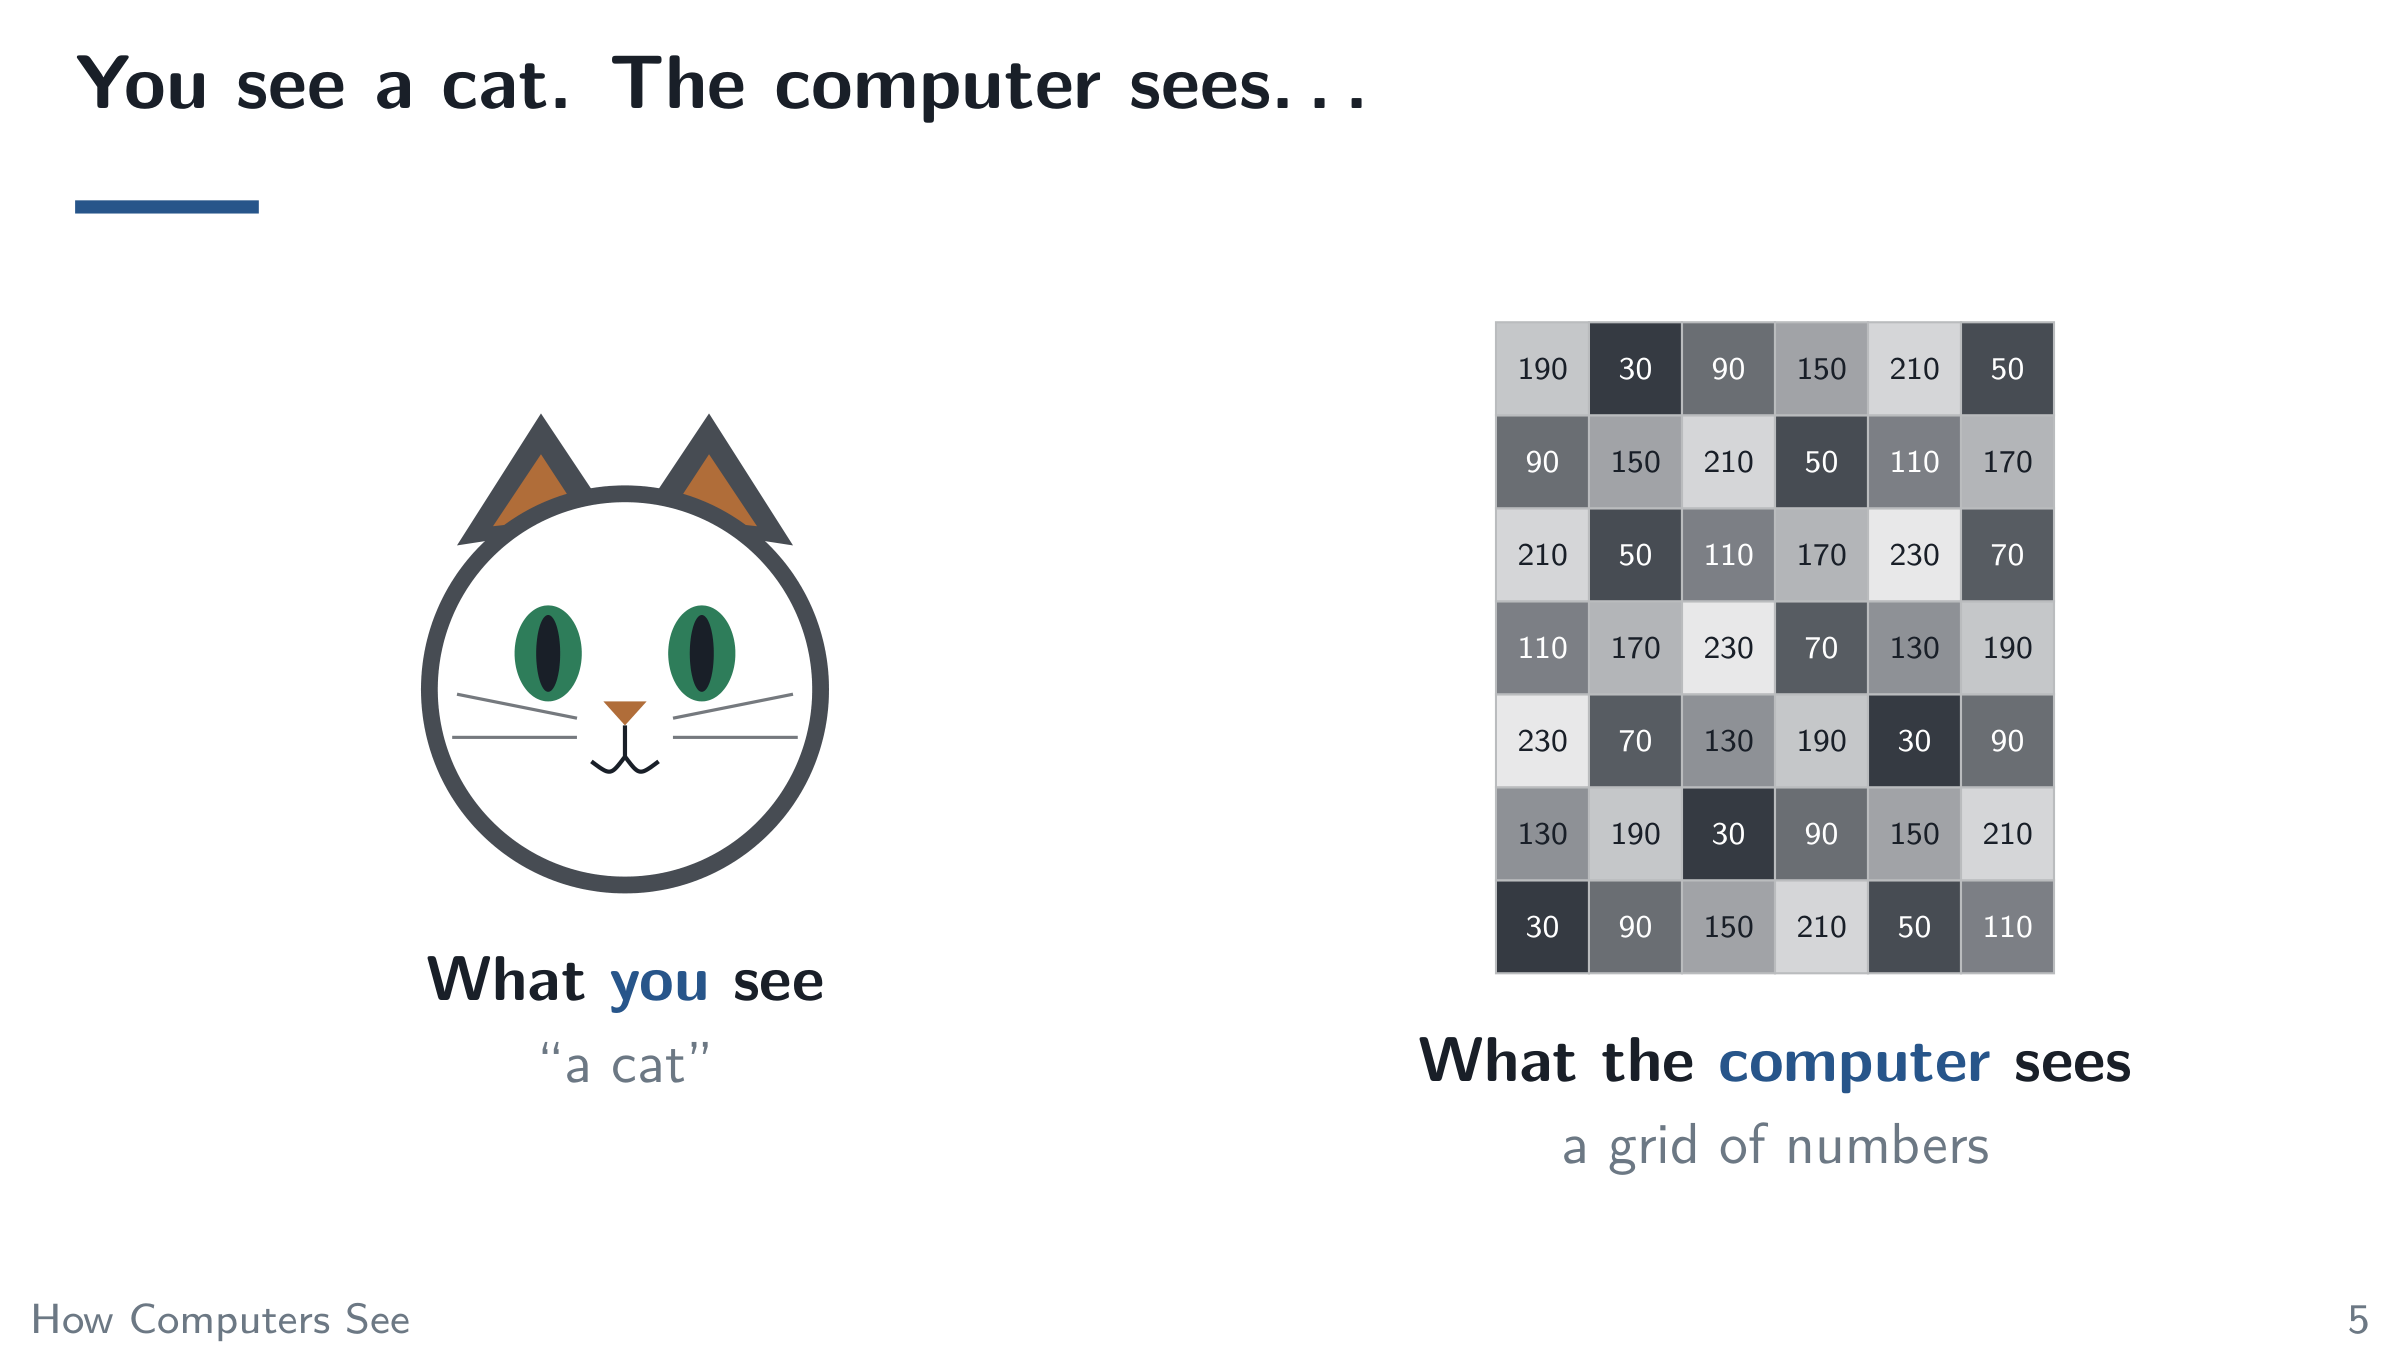
You see a cat. The computer sees…
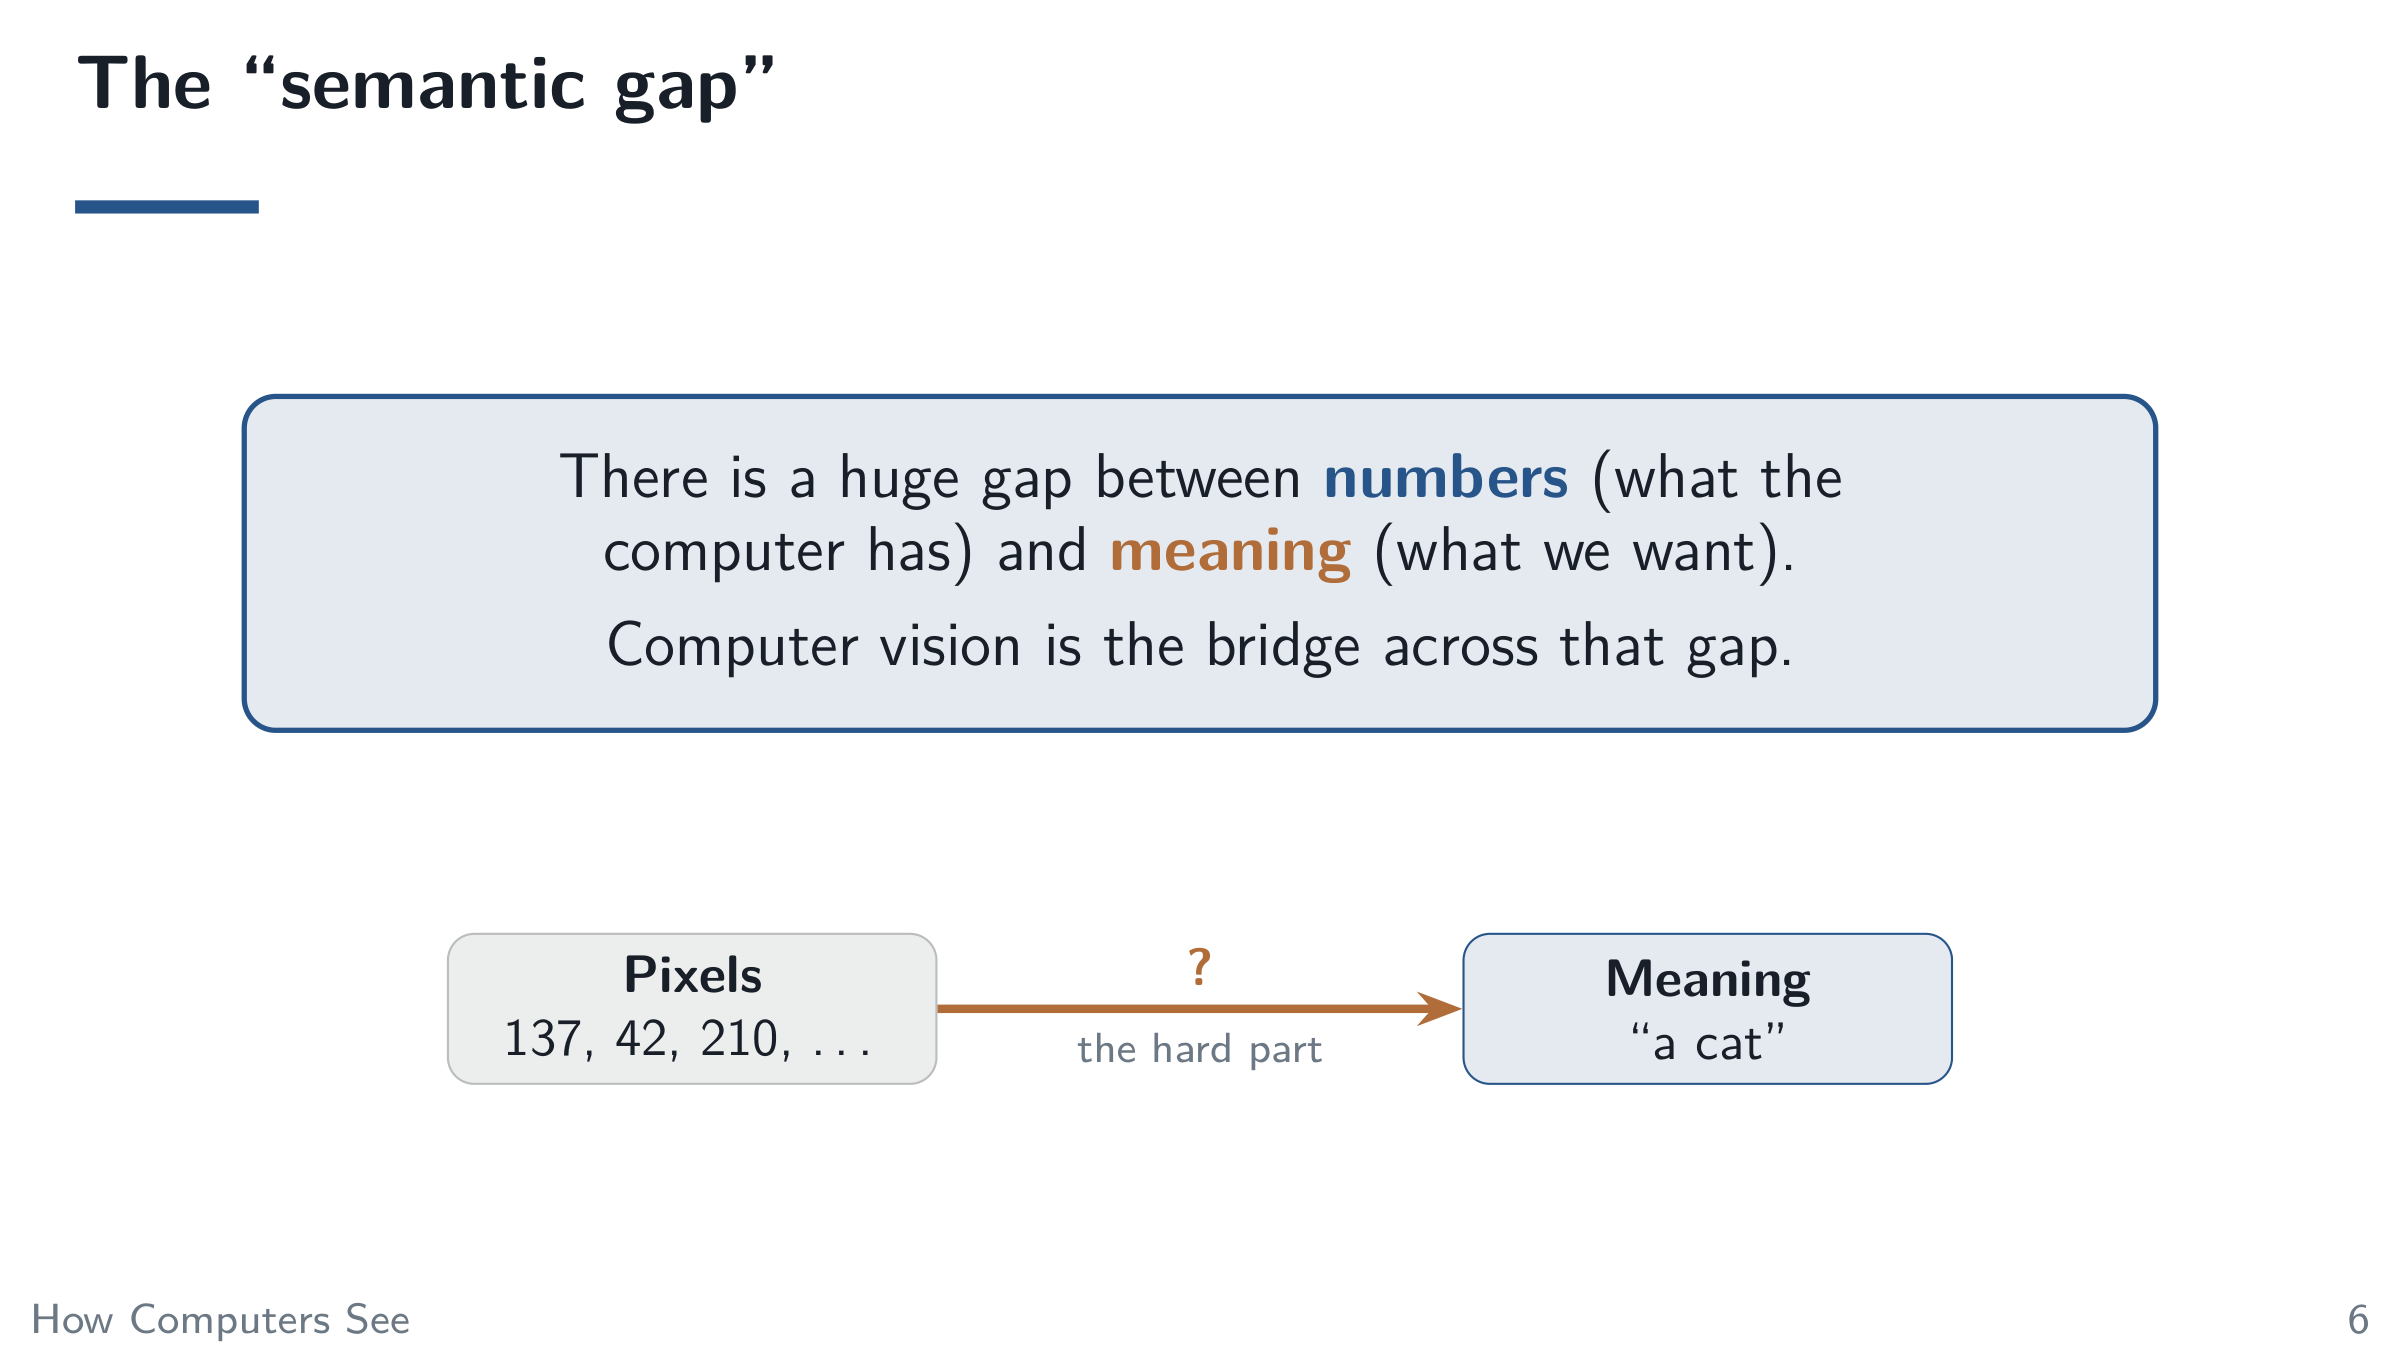
The “semantic gap”
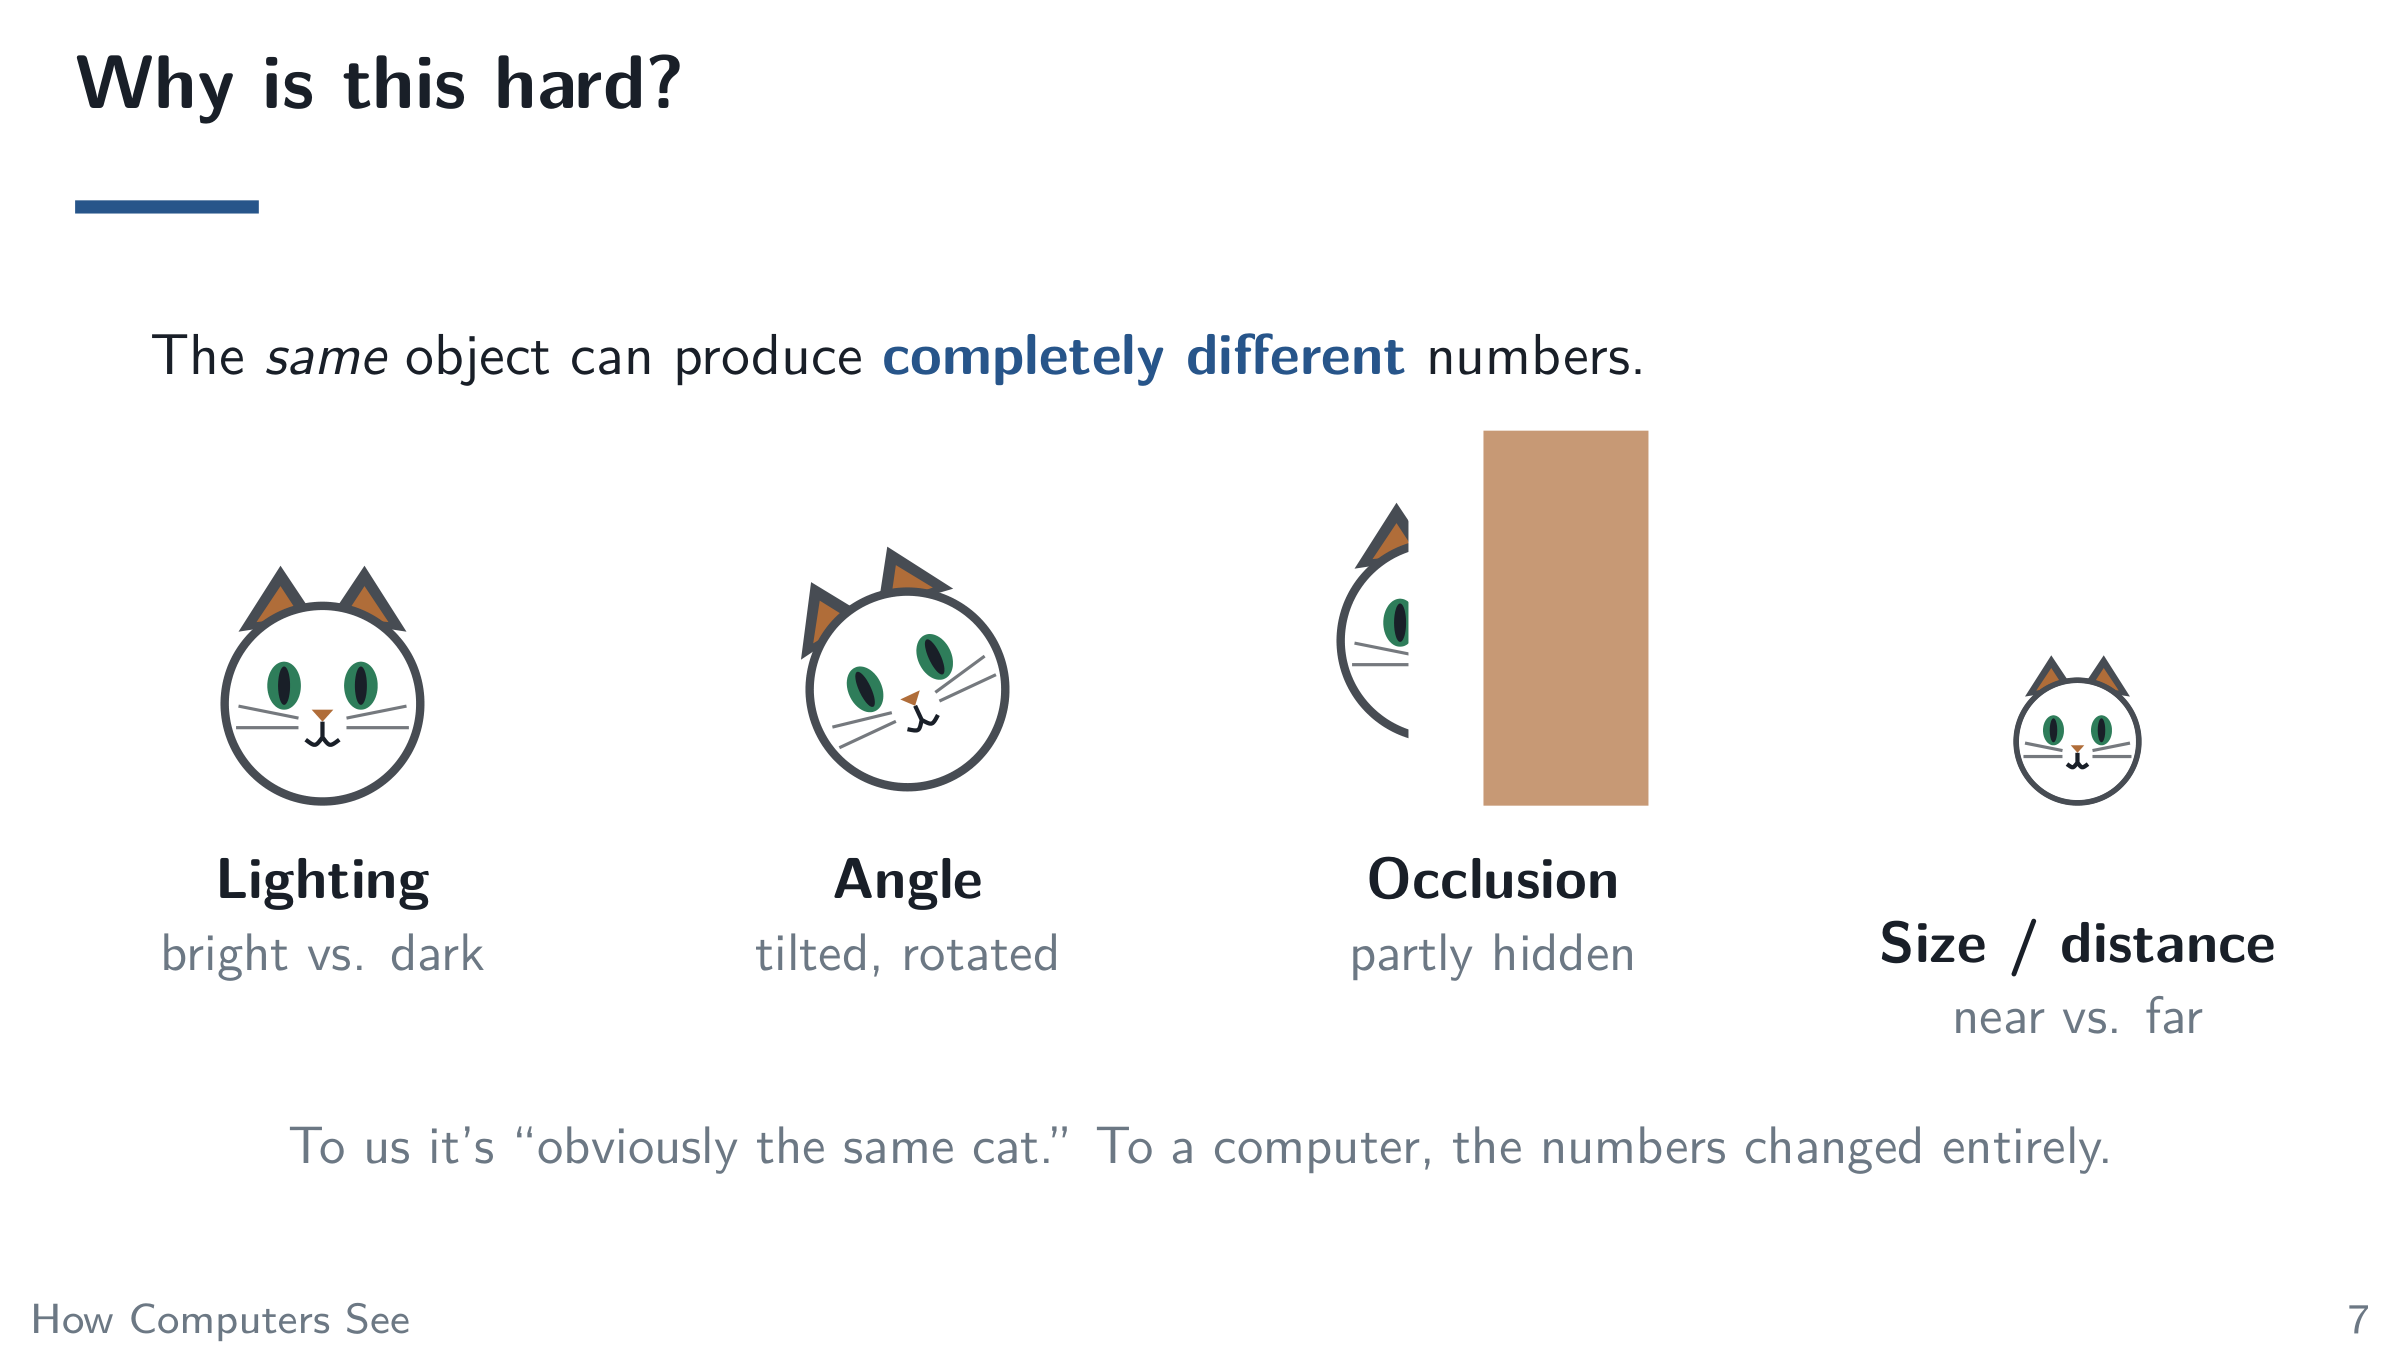
Why is this hard?
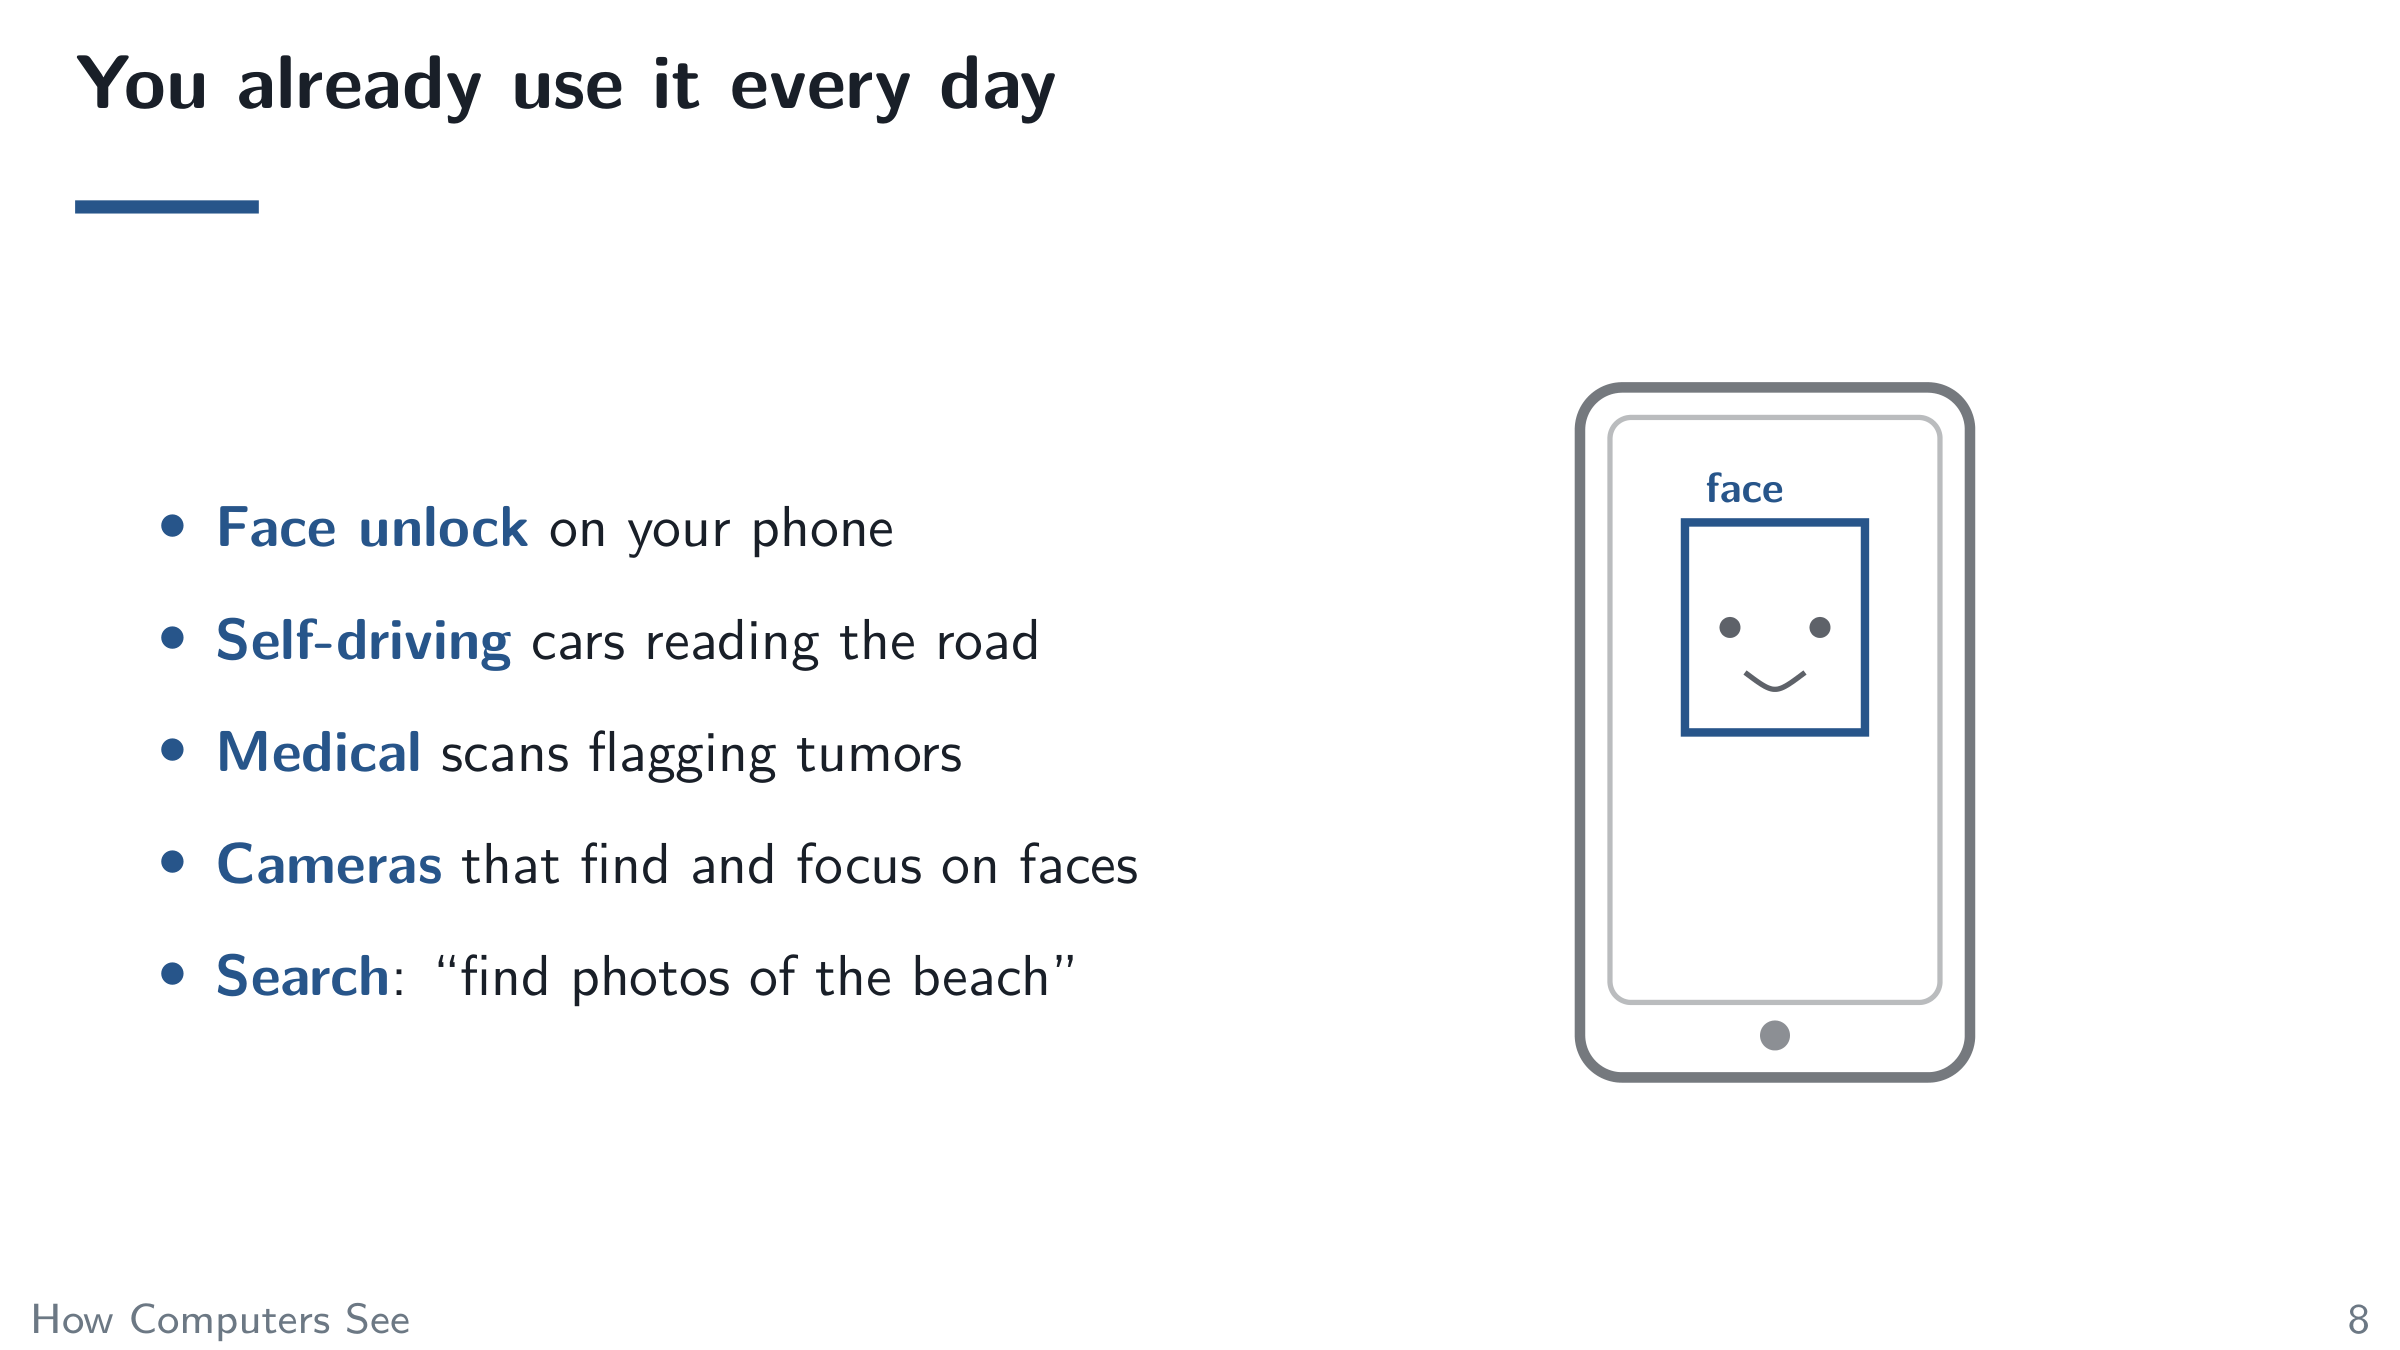
You already use it every day
How Images Are Represented
To a computer, an image is
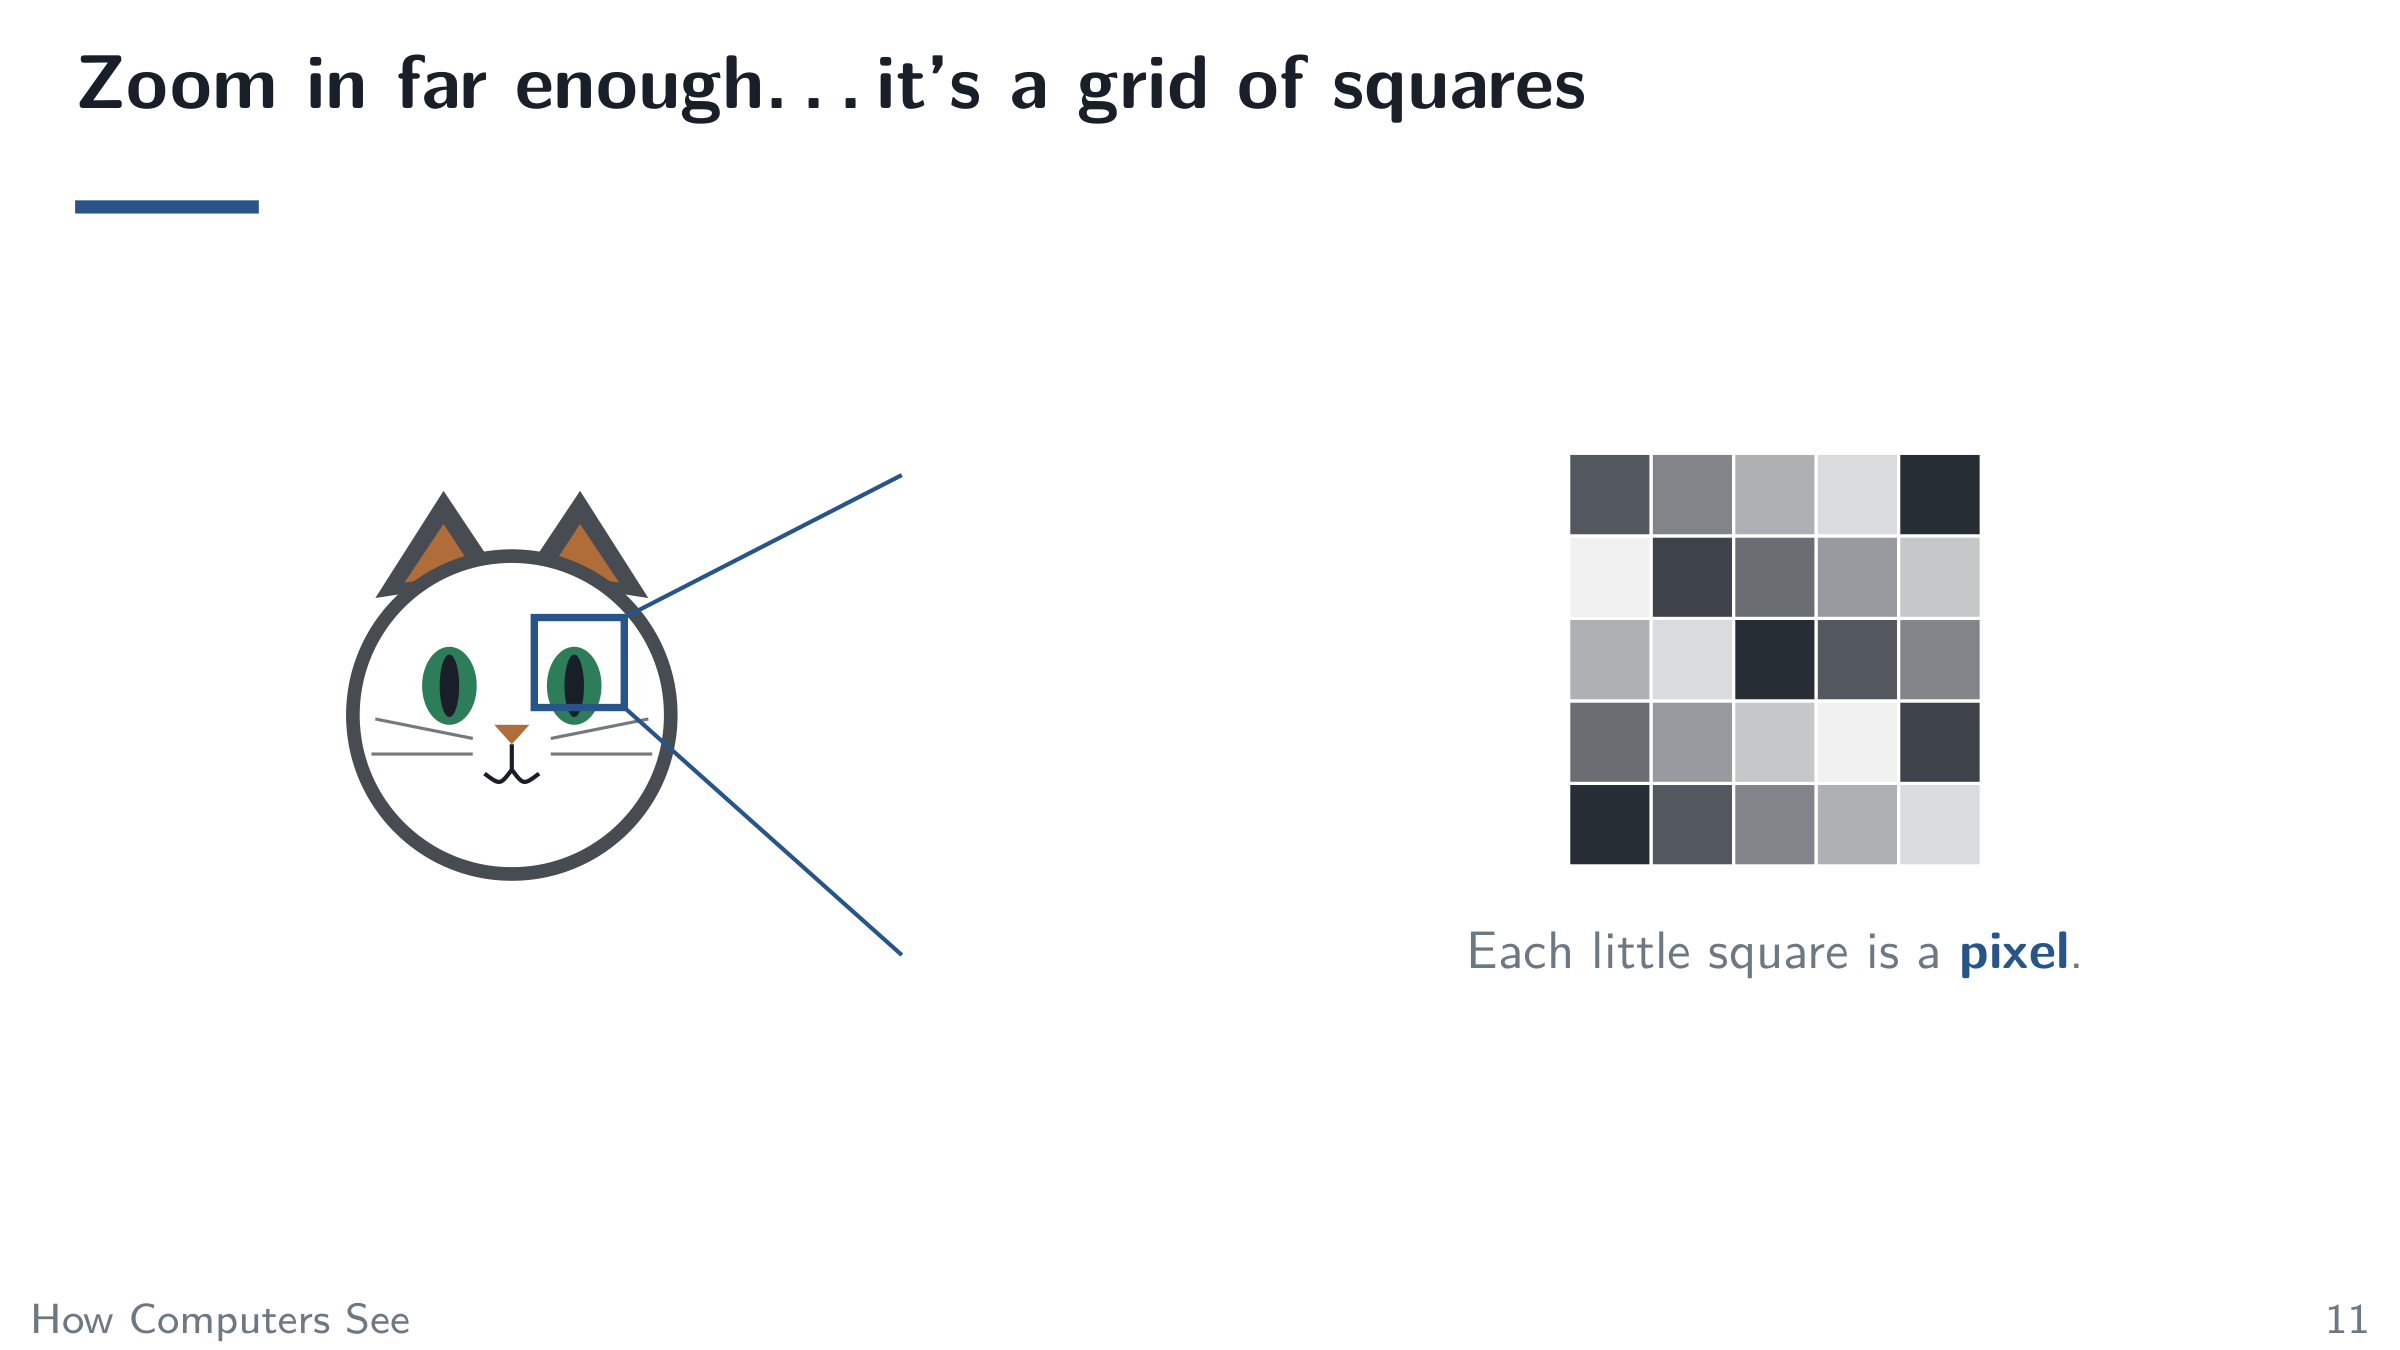
Zoom in far enough… it’s a grid of squares
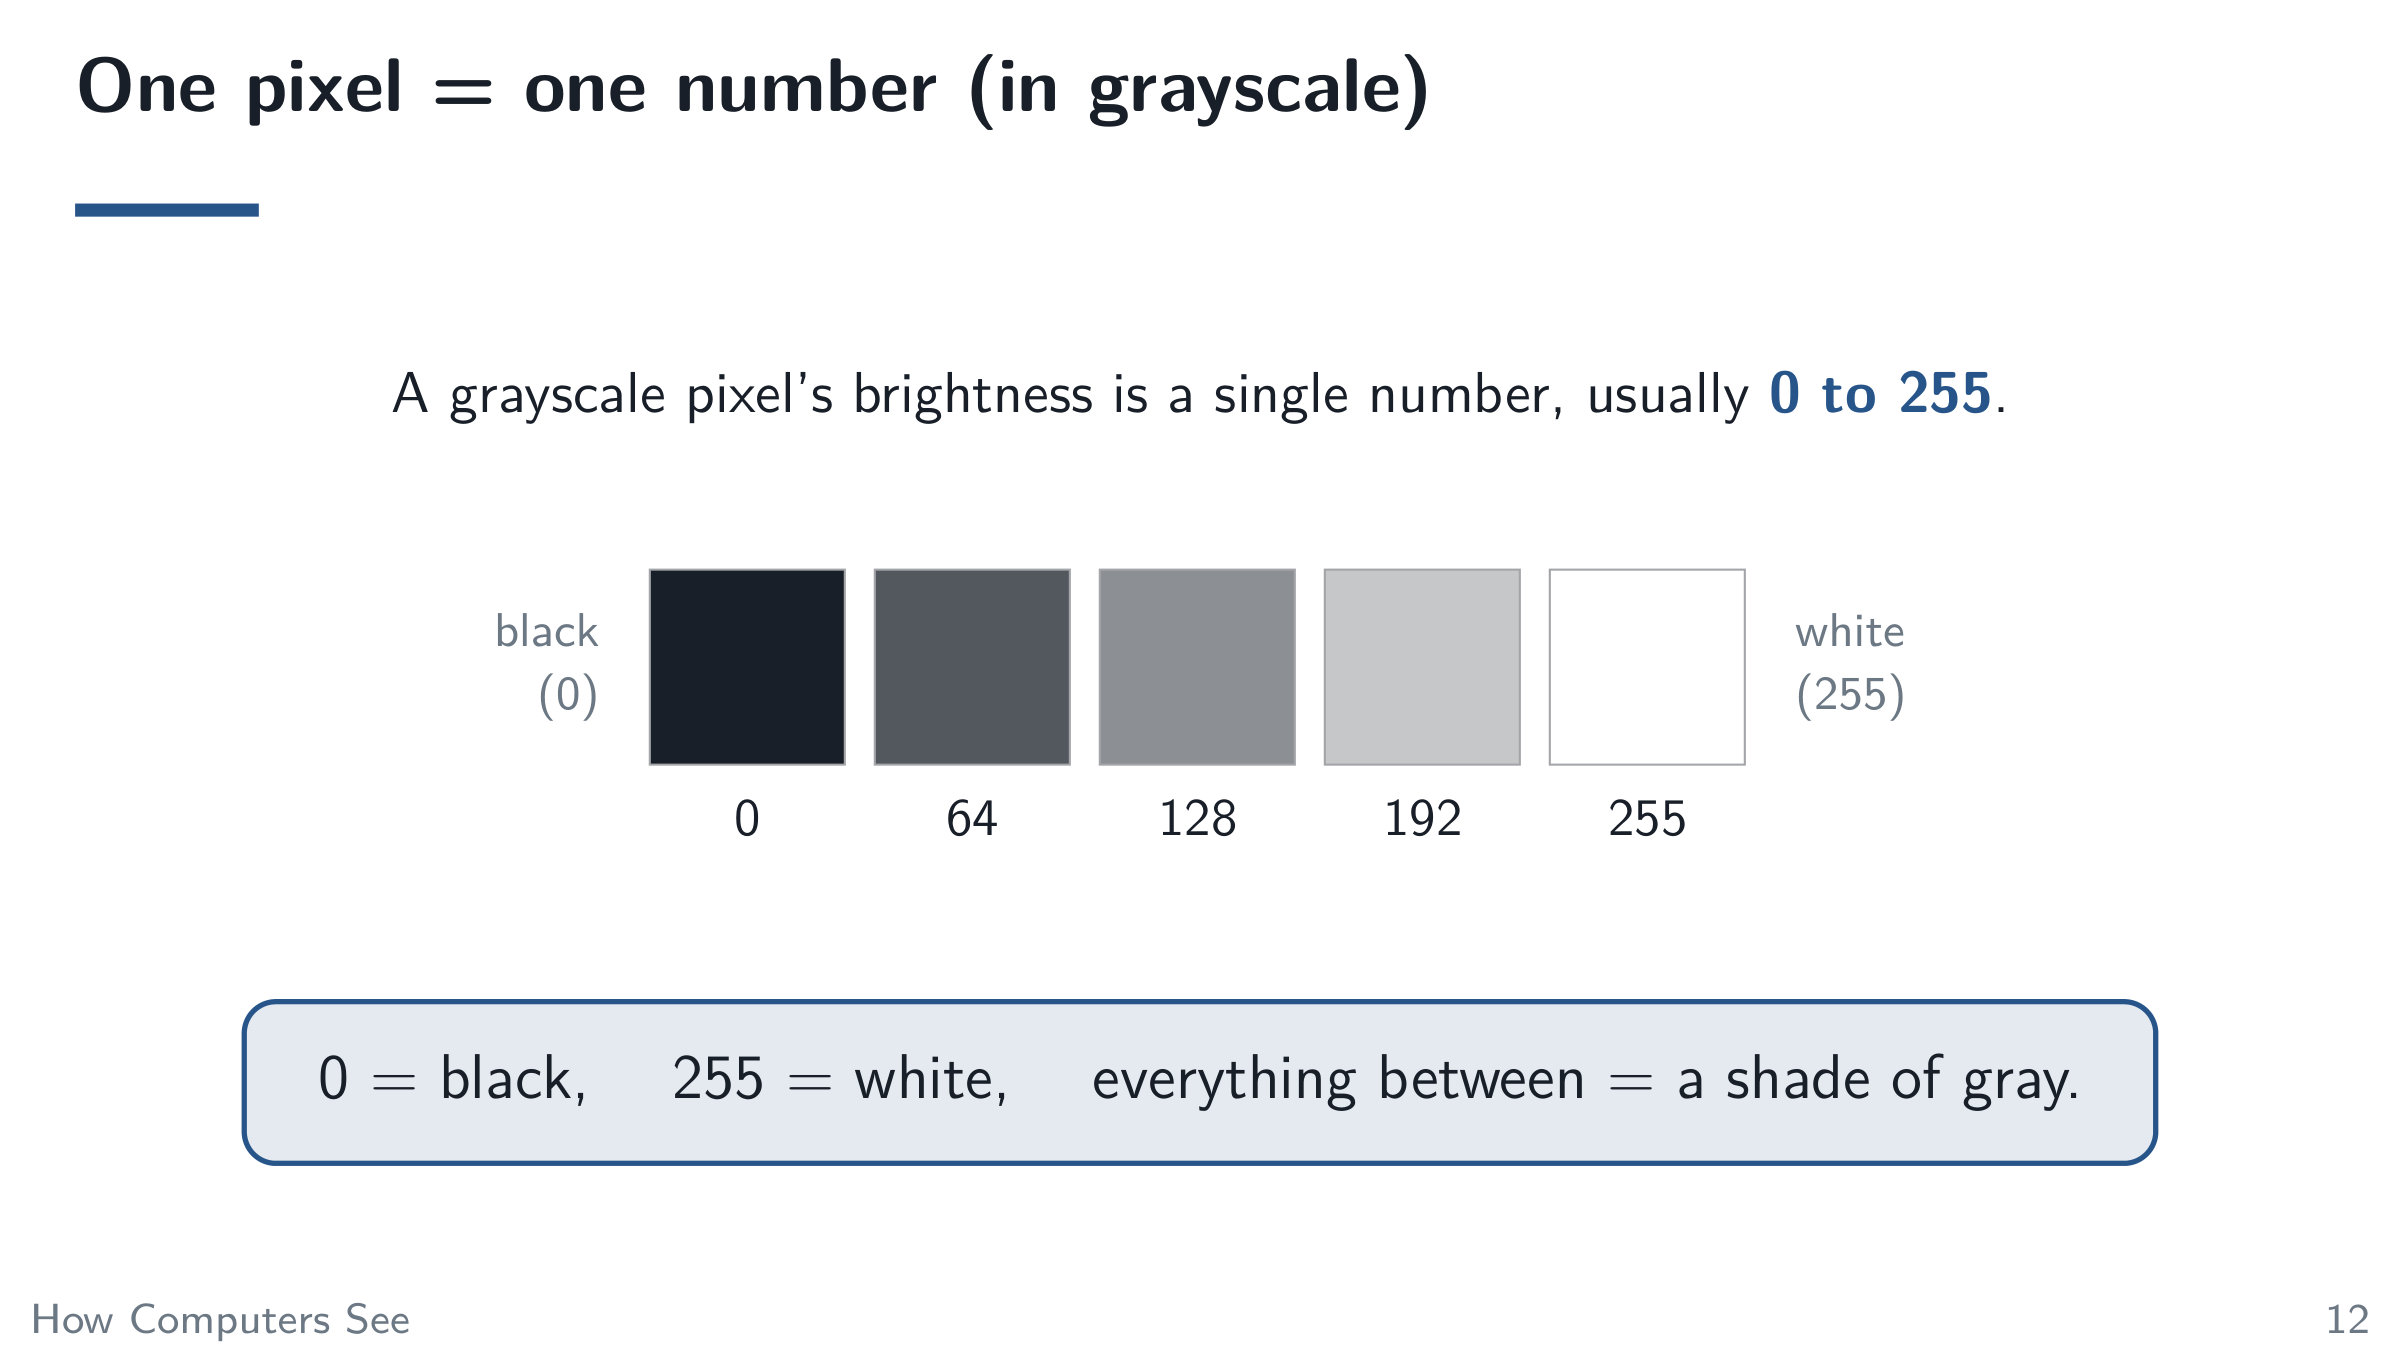
One pixel = one number (in grayscale)
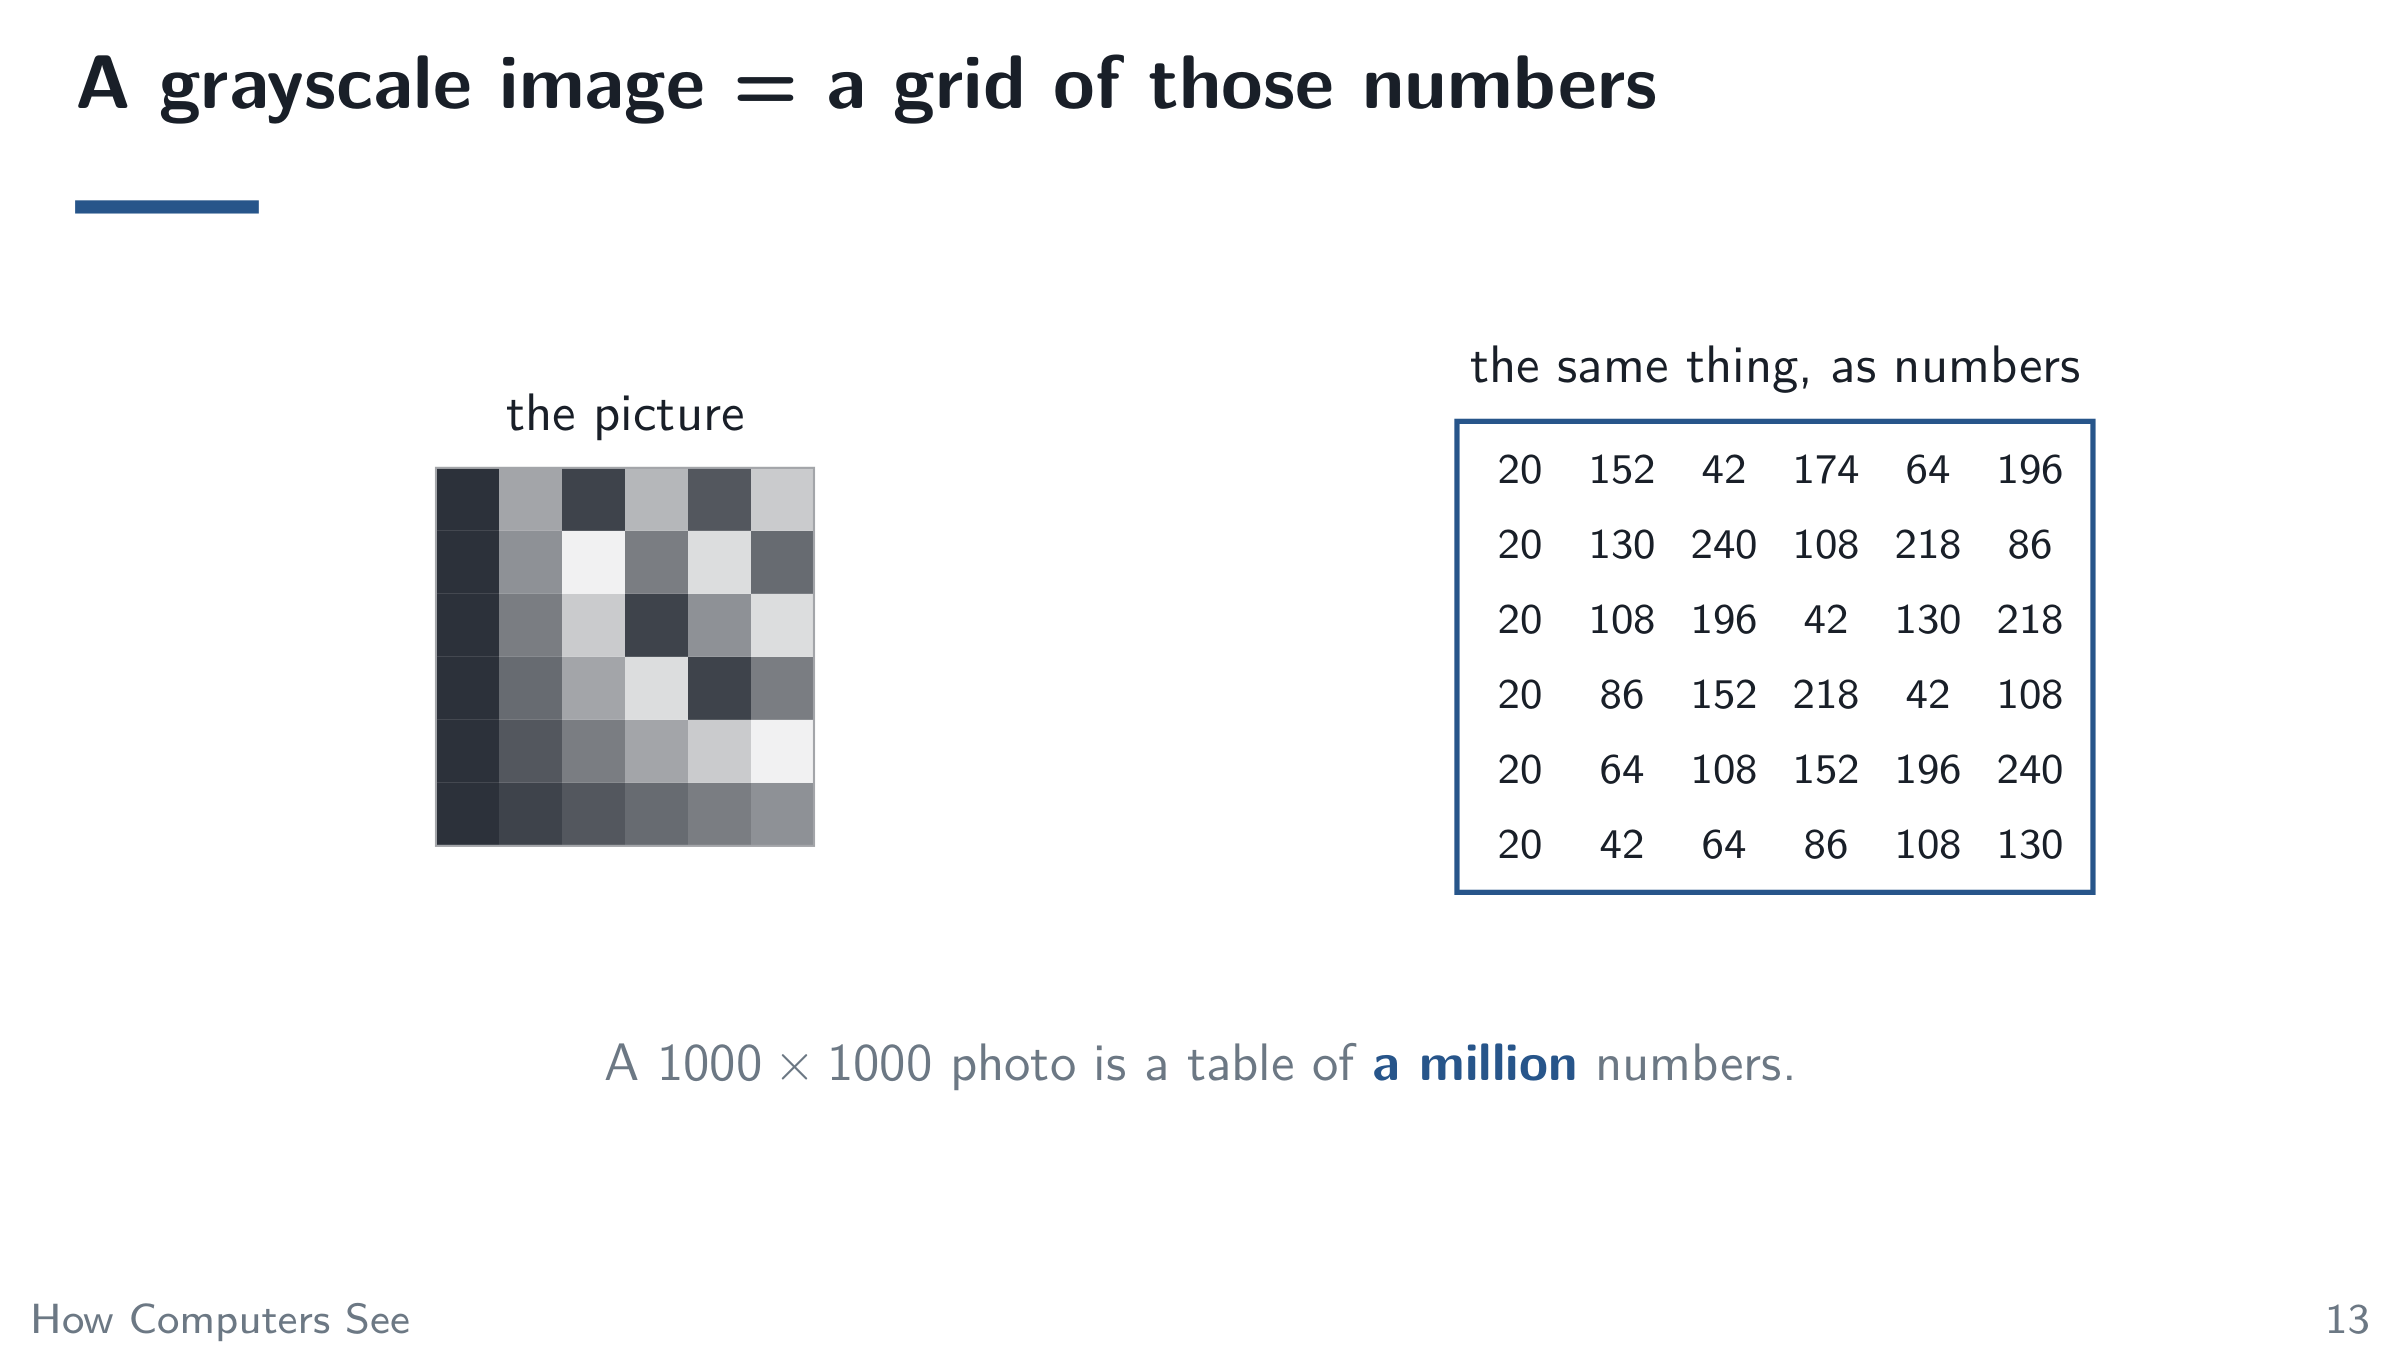
A grayscale image = a grid of those numbers
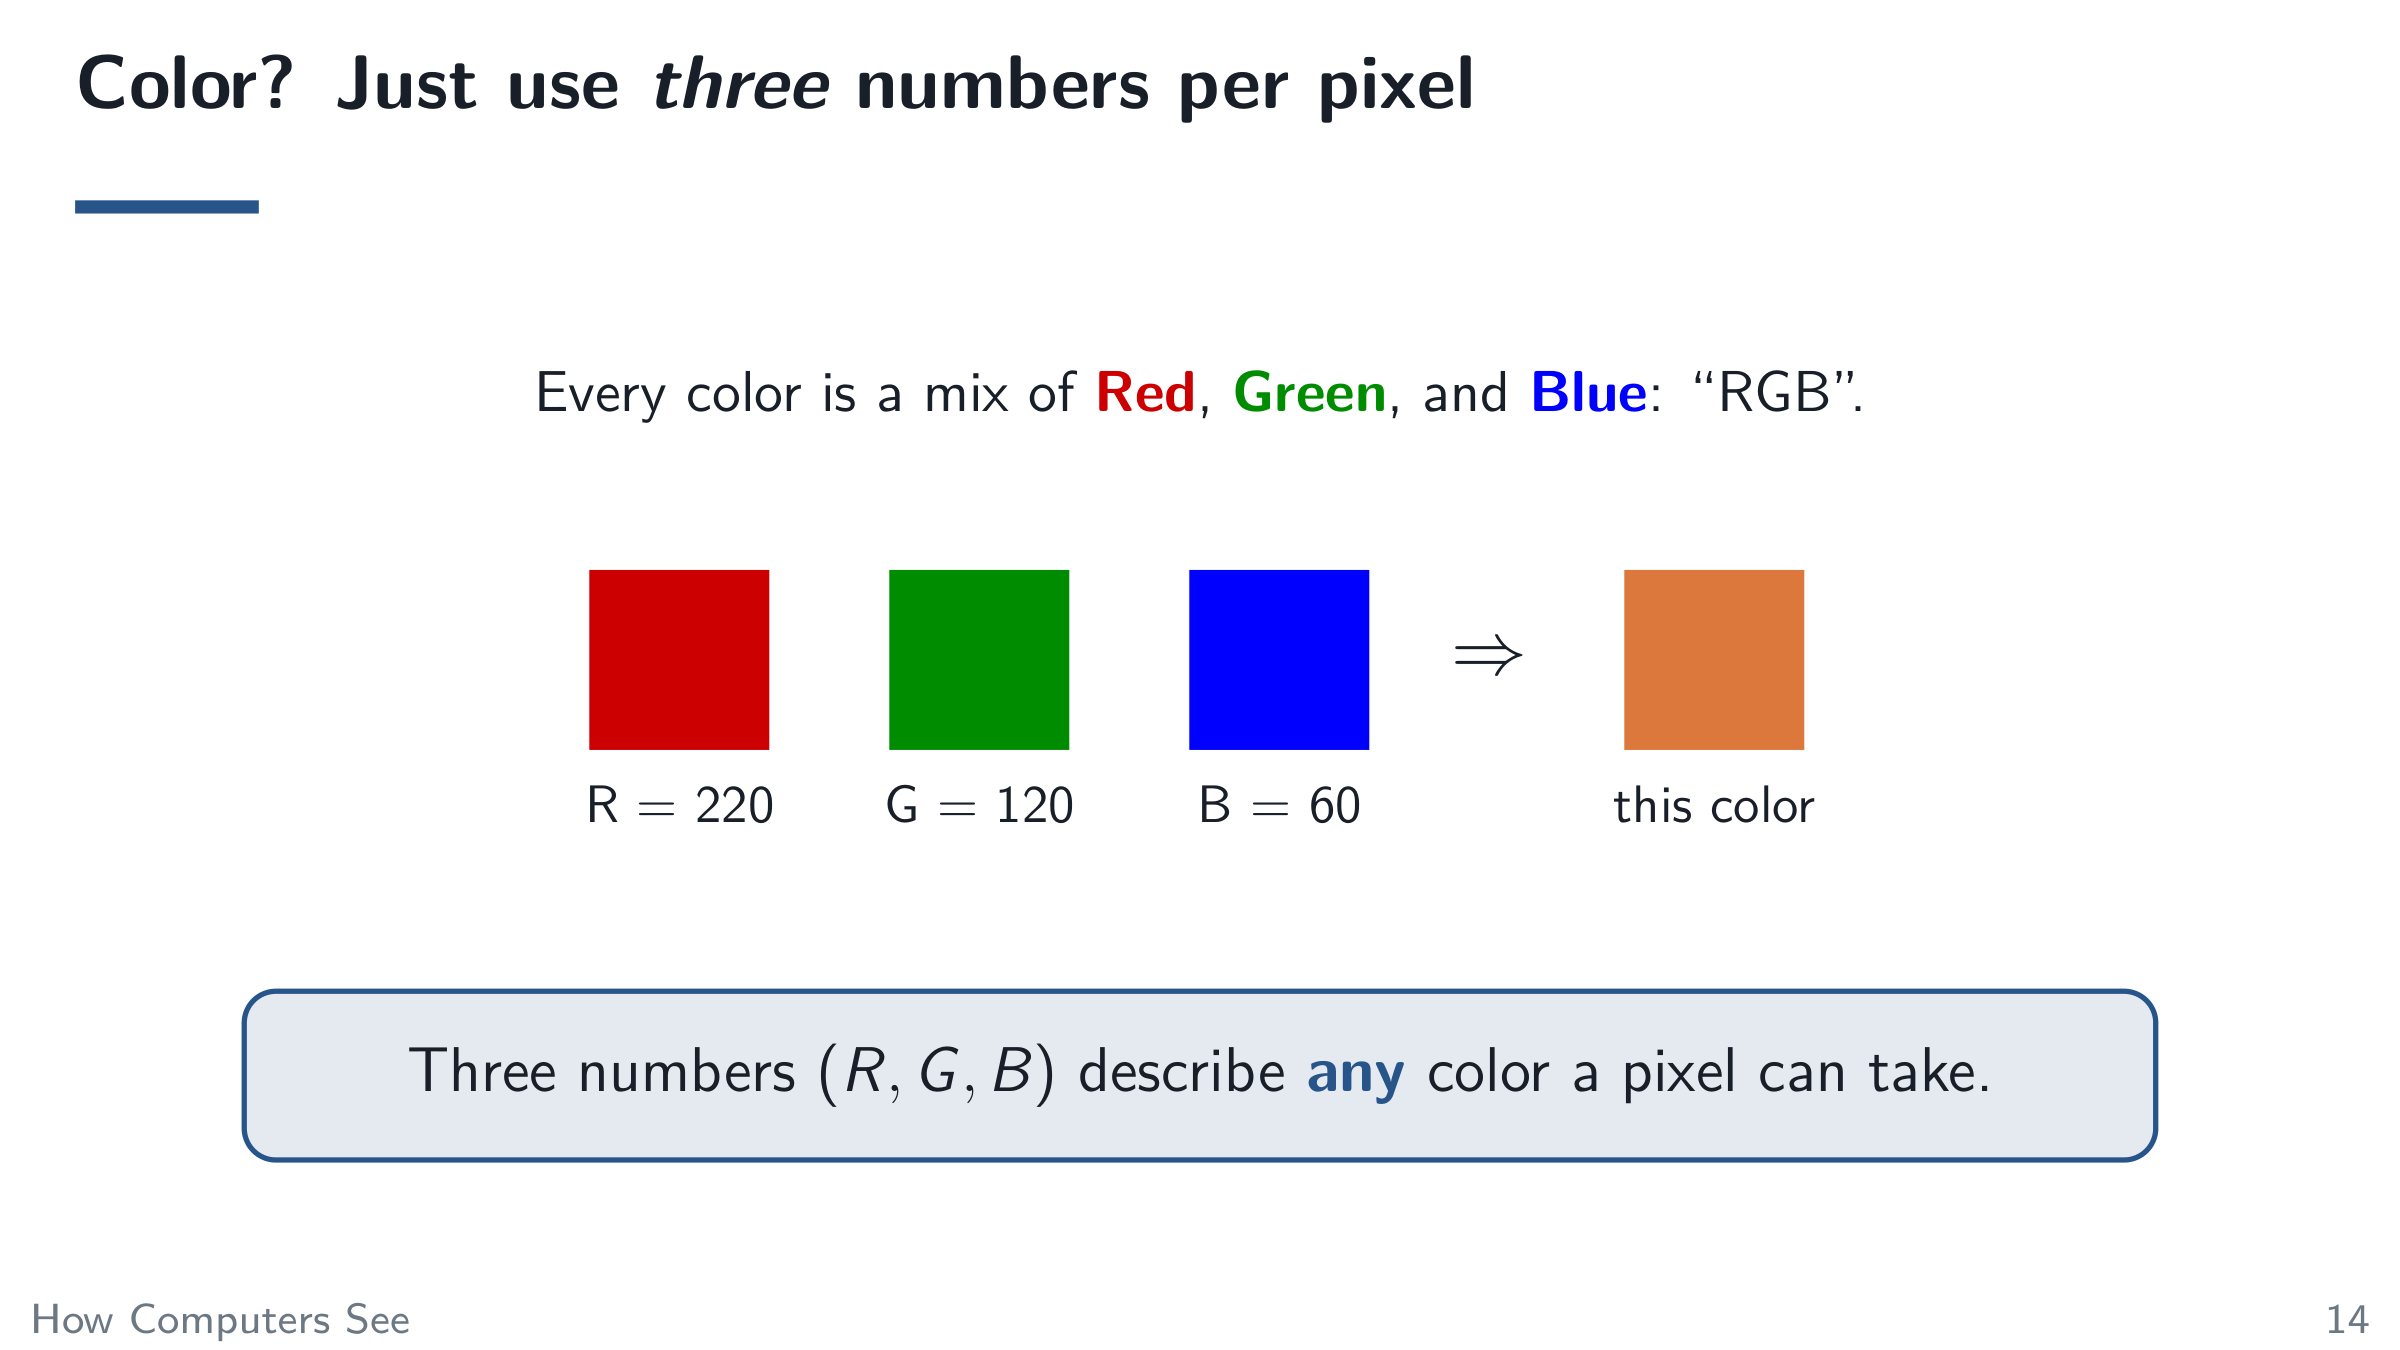
Color? Just use three numbers per pixel
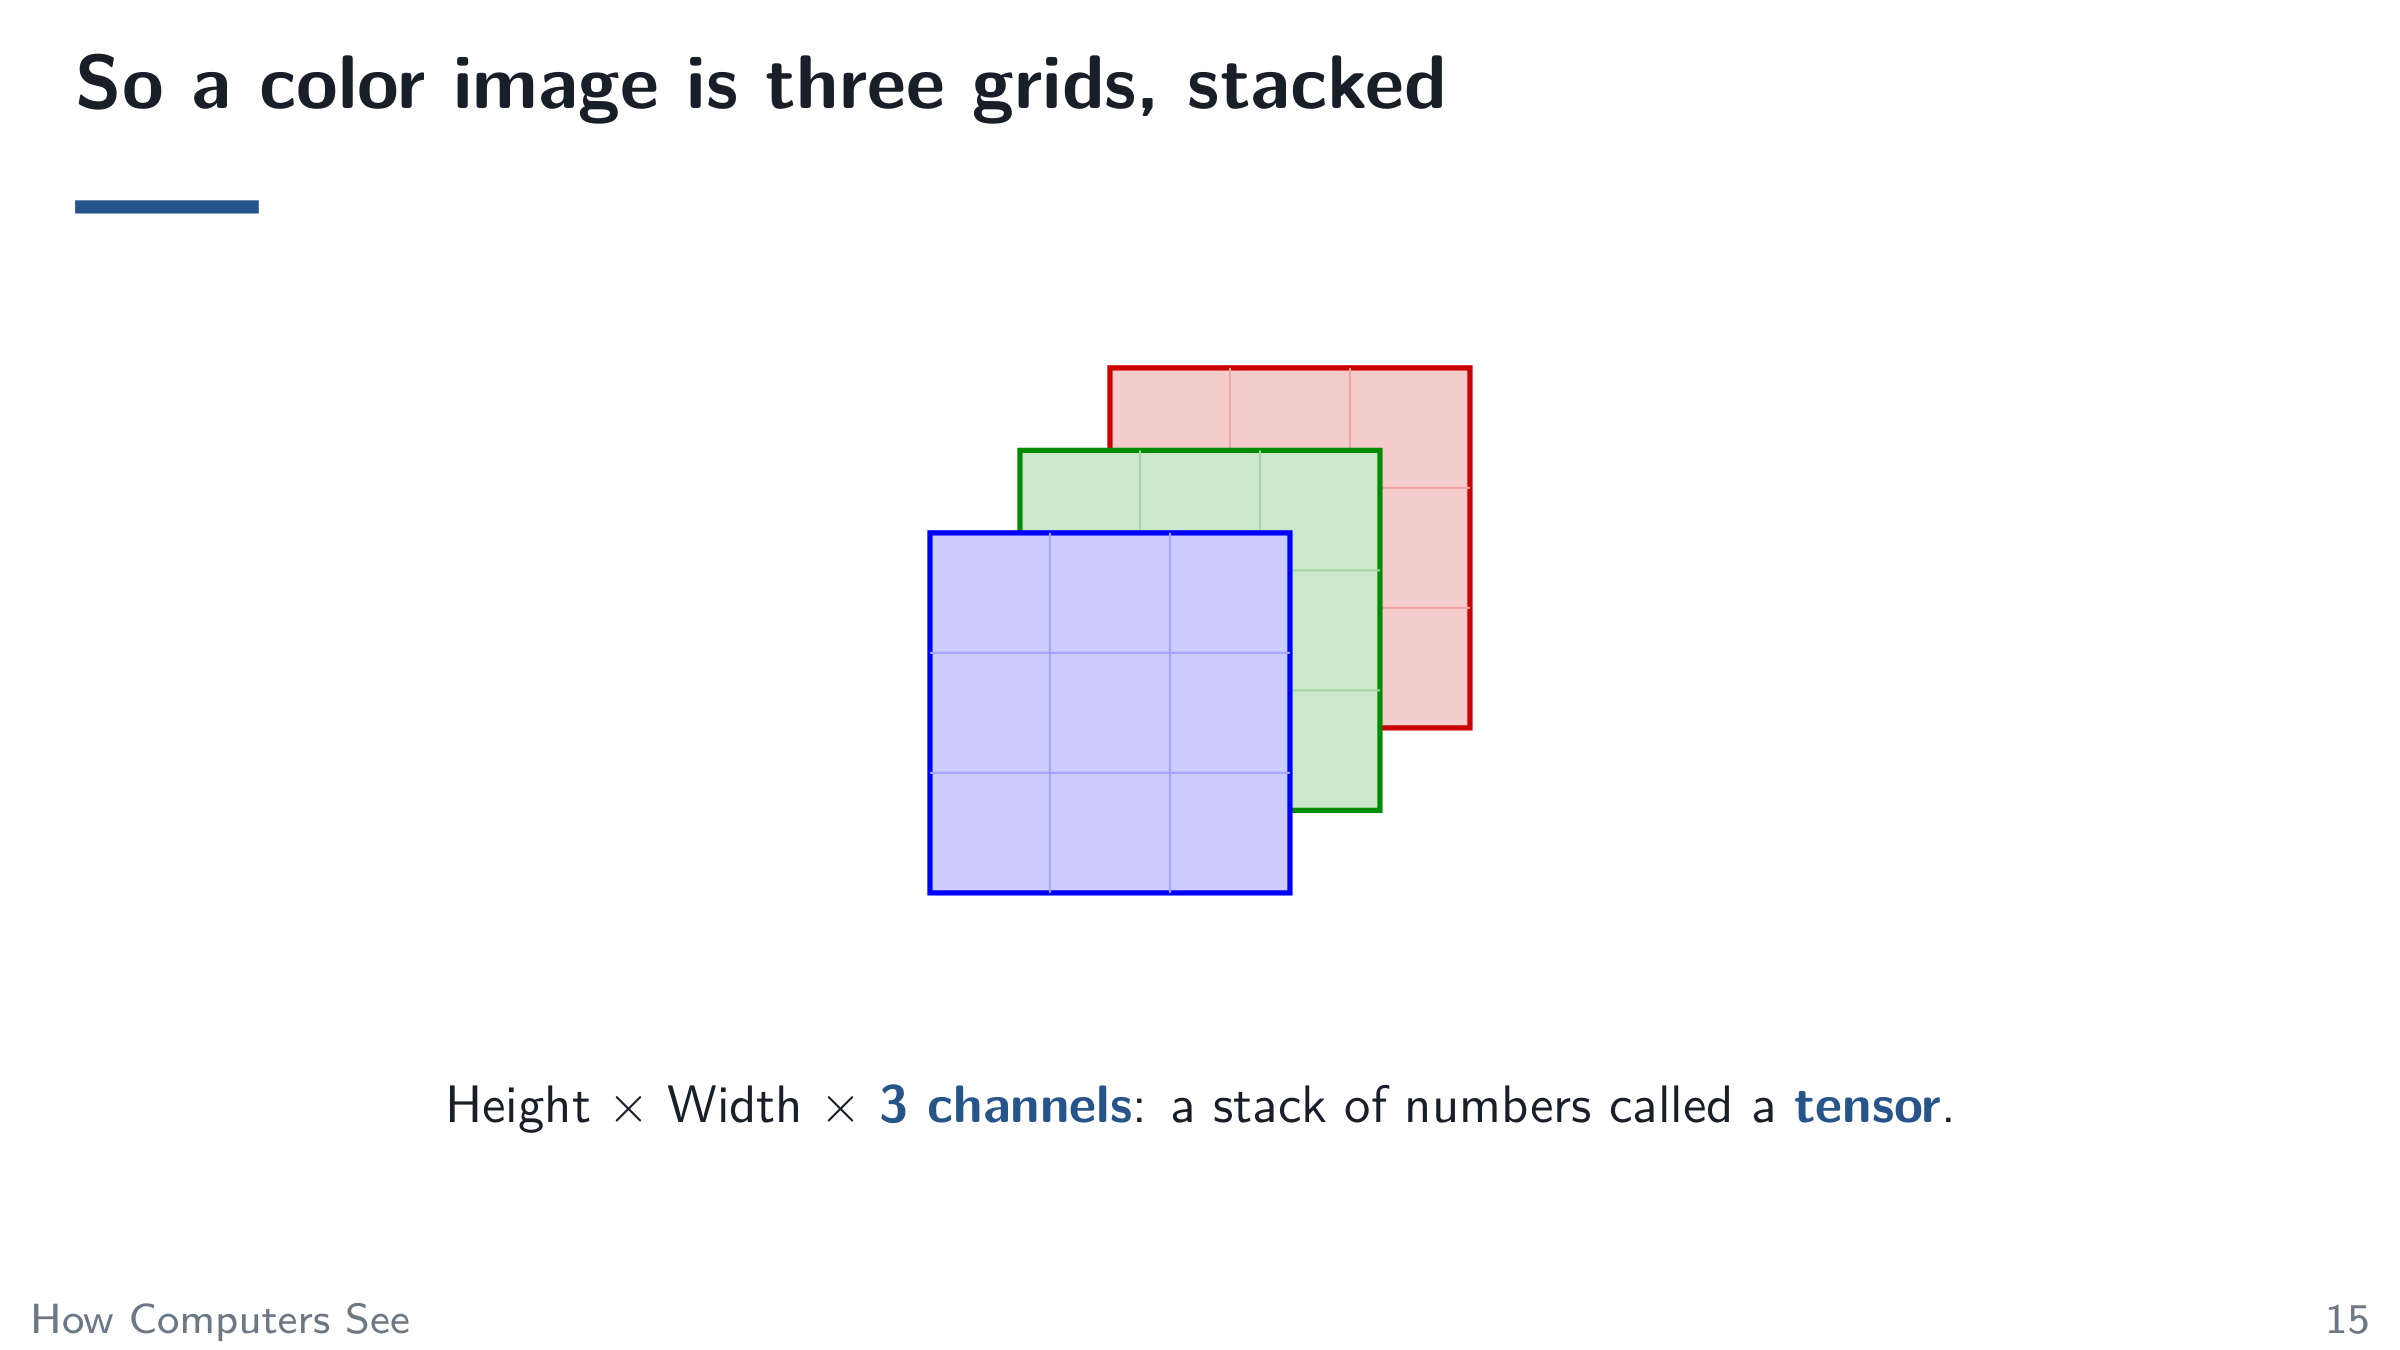
So a color image is three grids, stacked
The key takeaway
Demo: An image really is just numbers ▶︎ Open Lab 4A
Image Classification
Classification asks one question
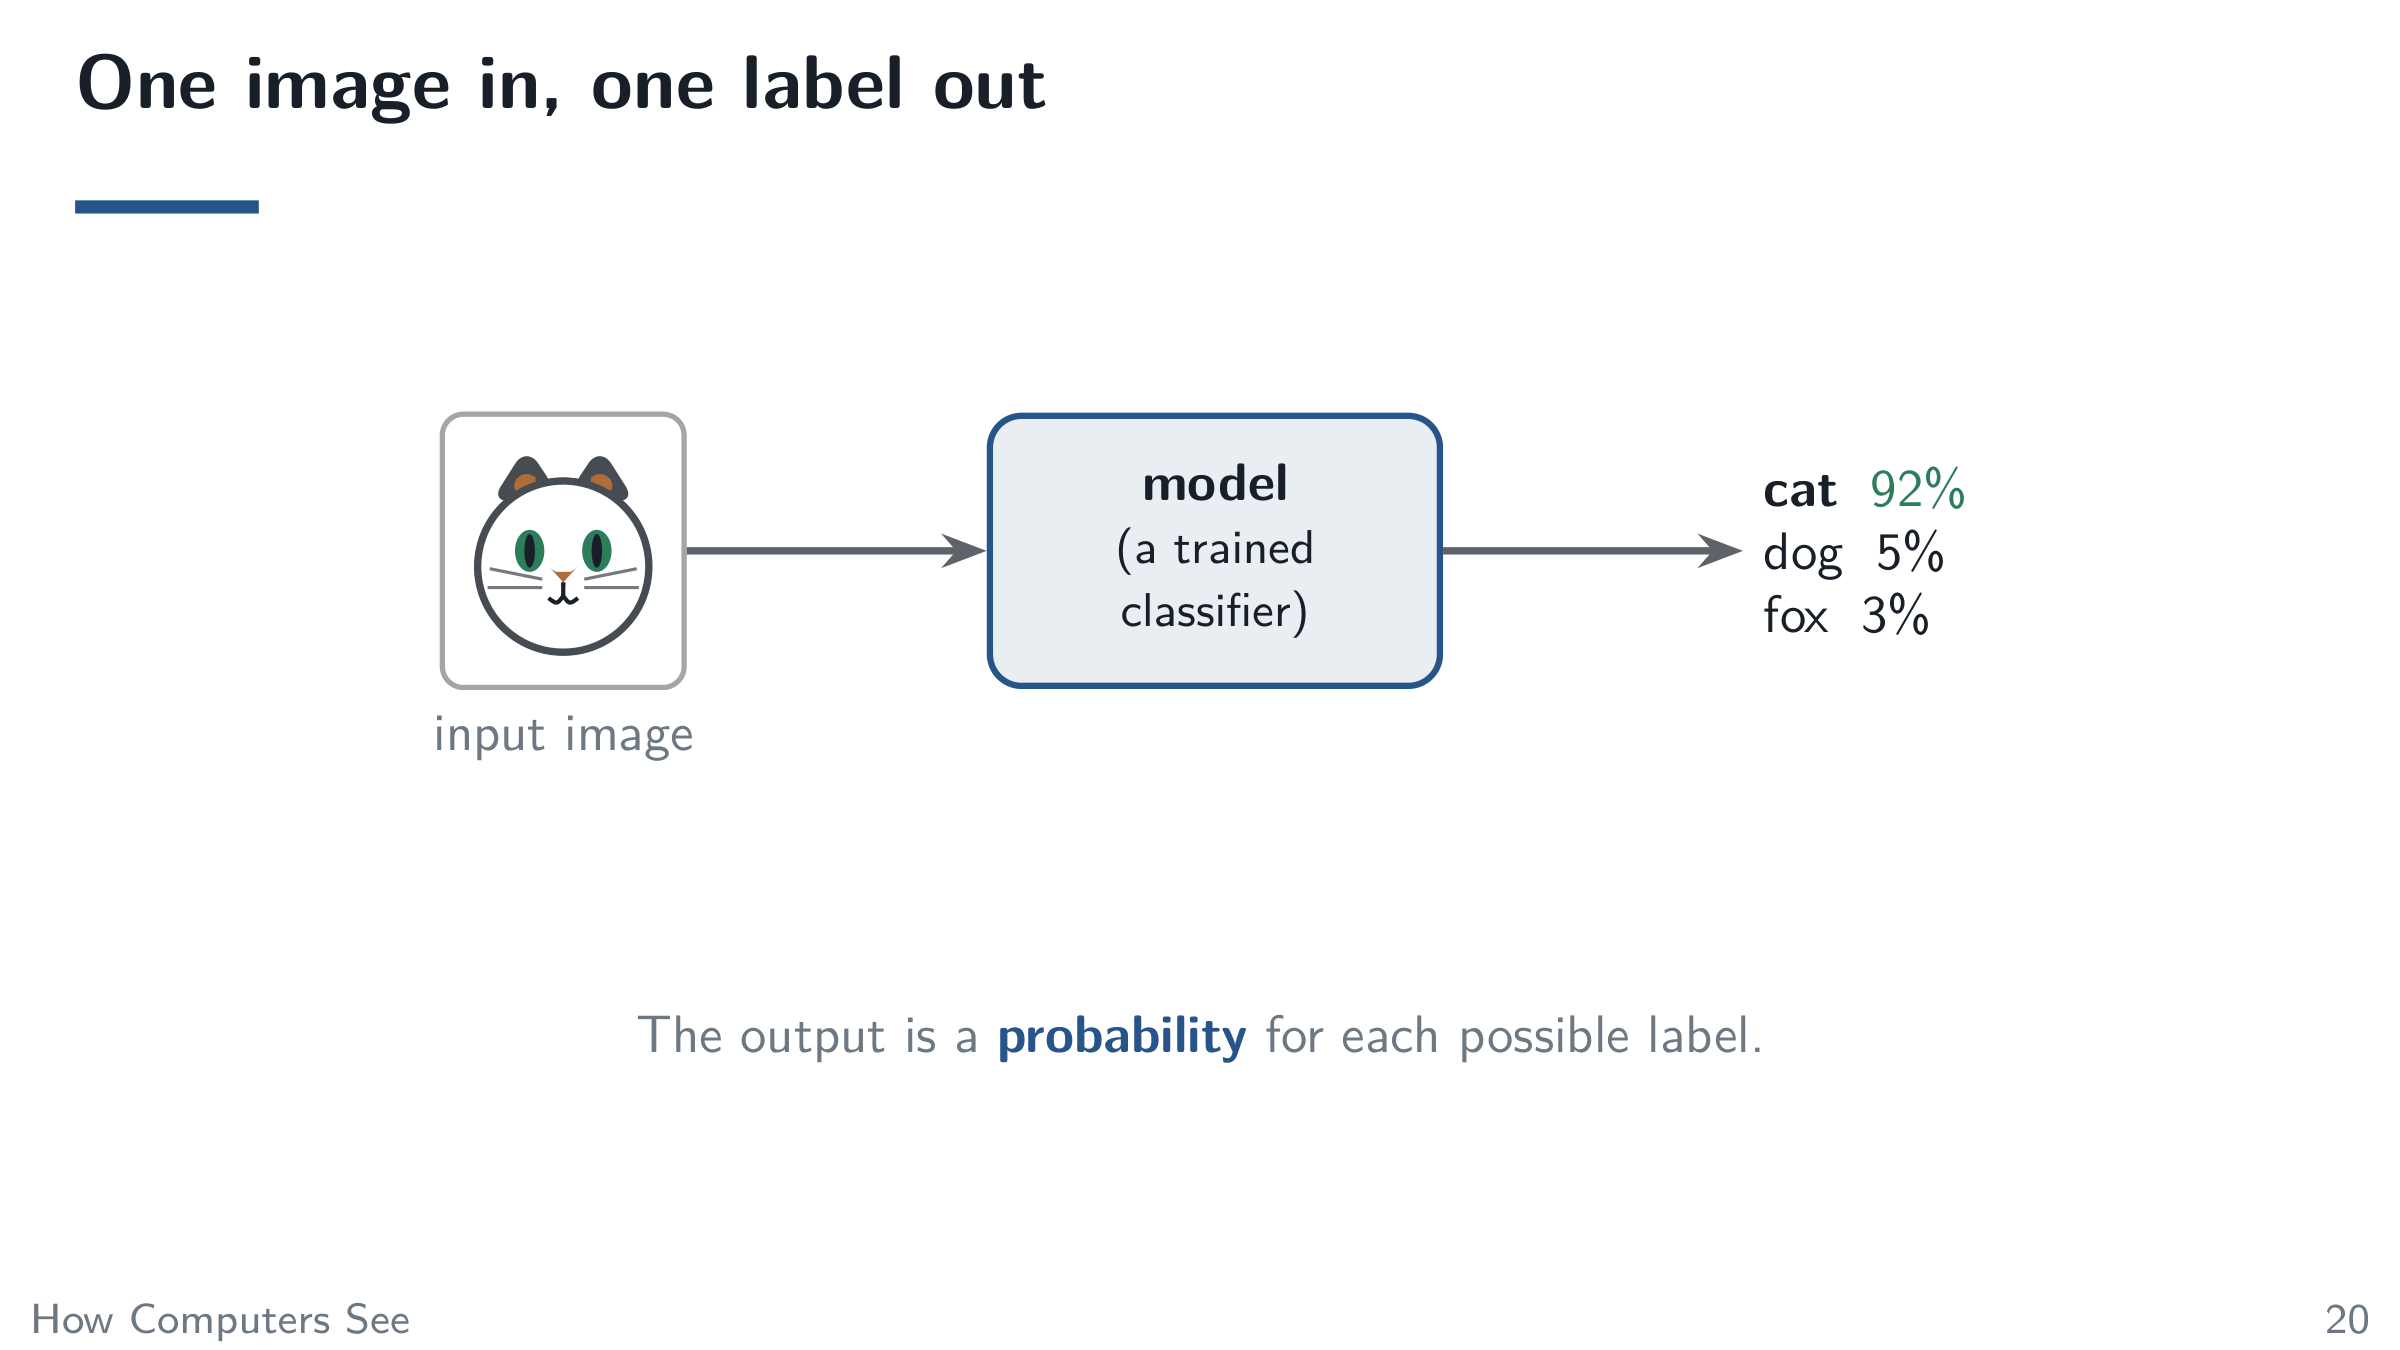
One image in, one label out
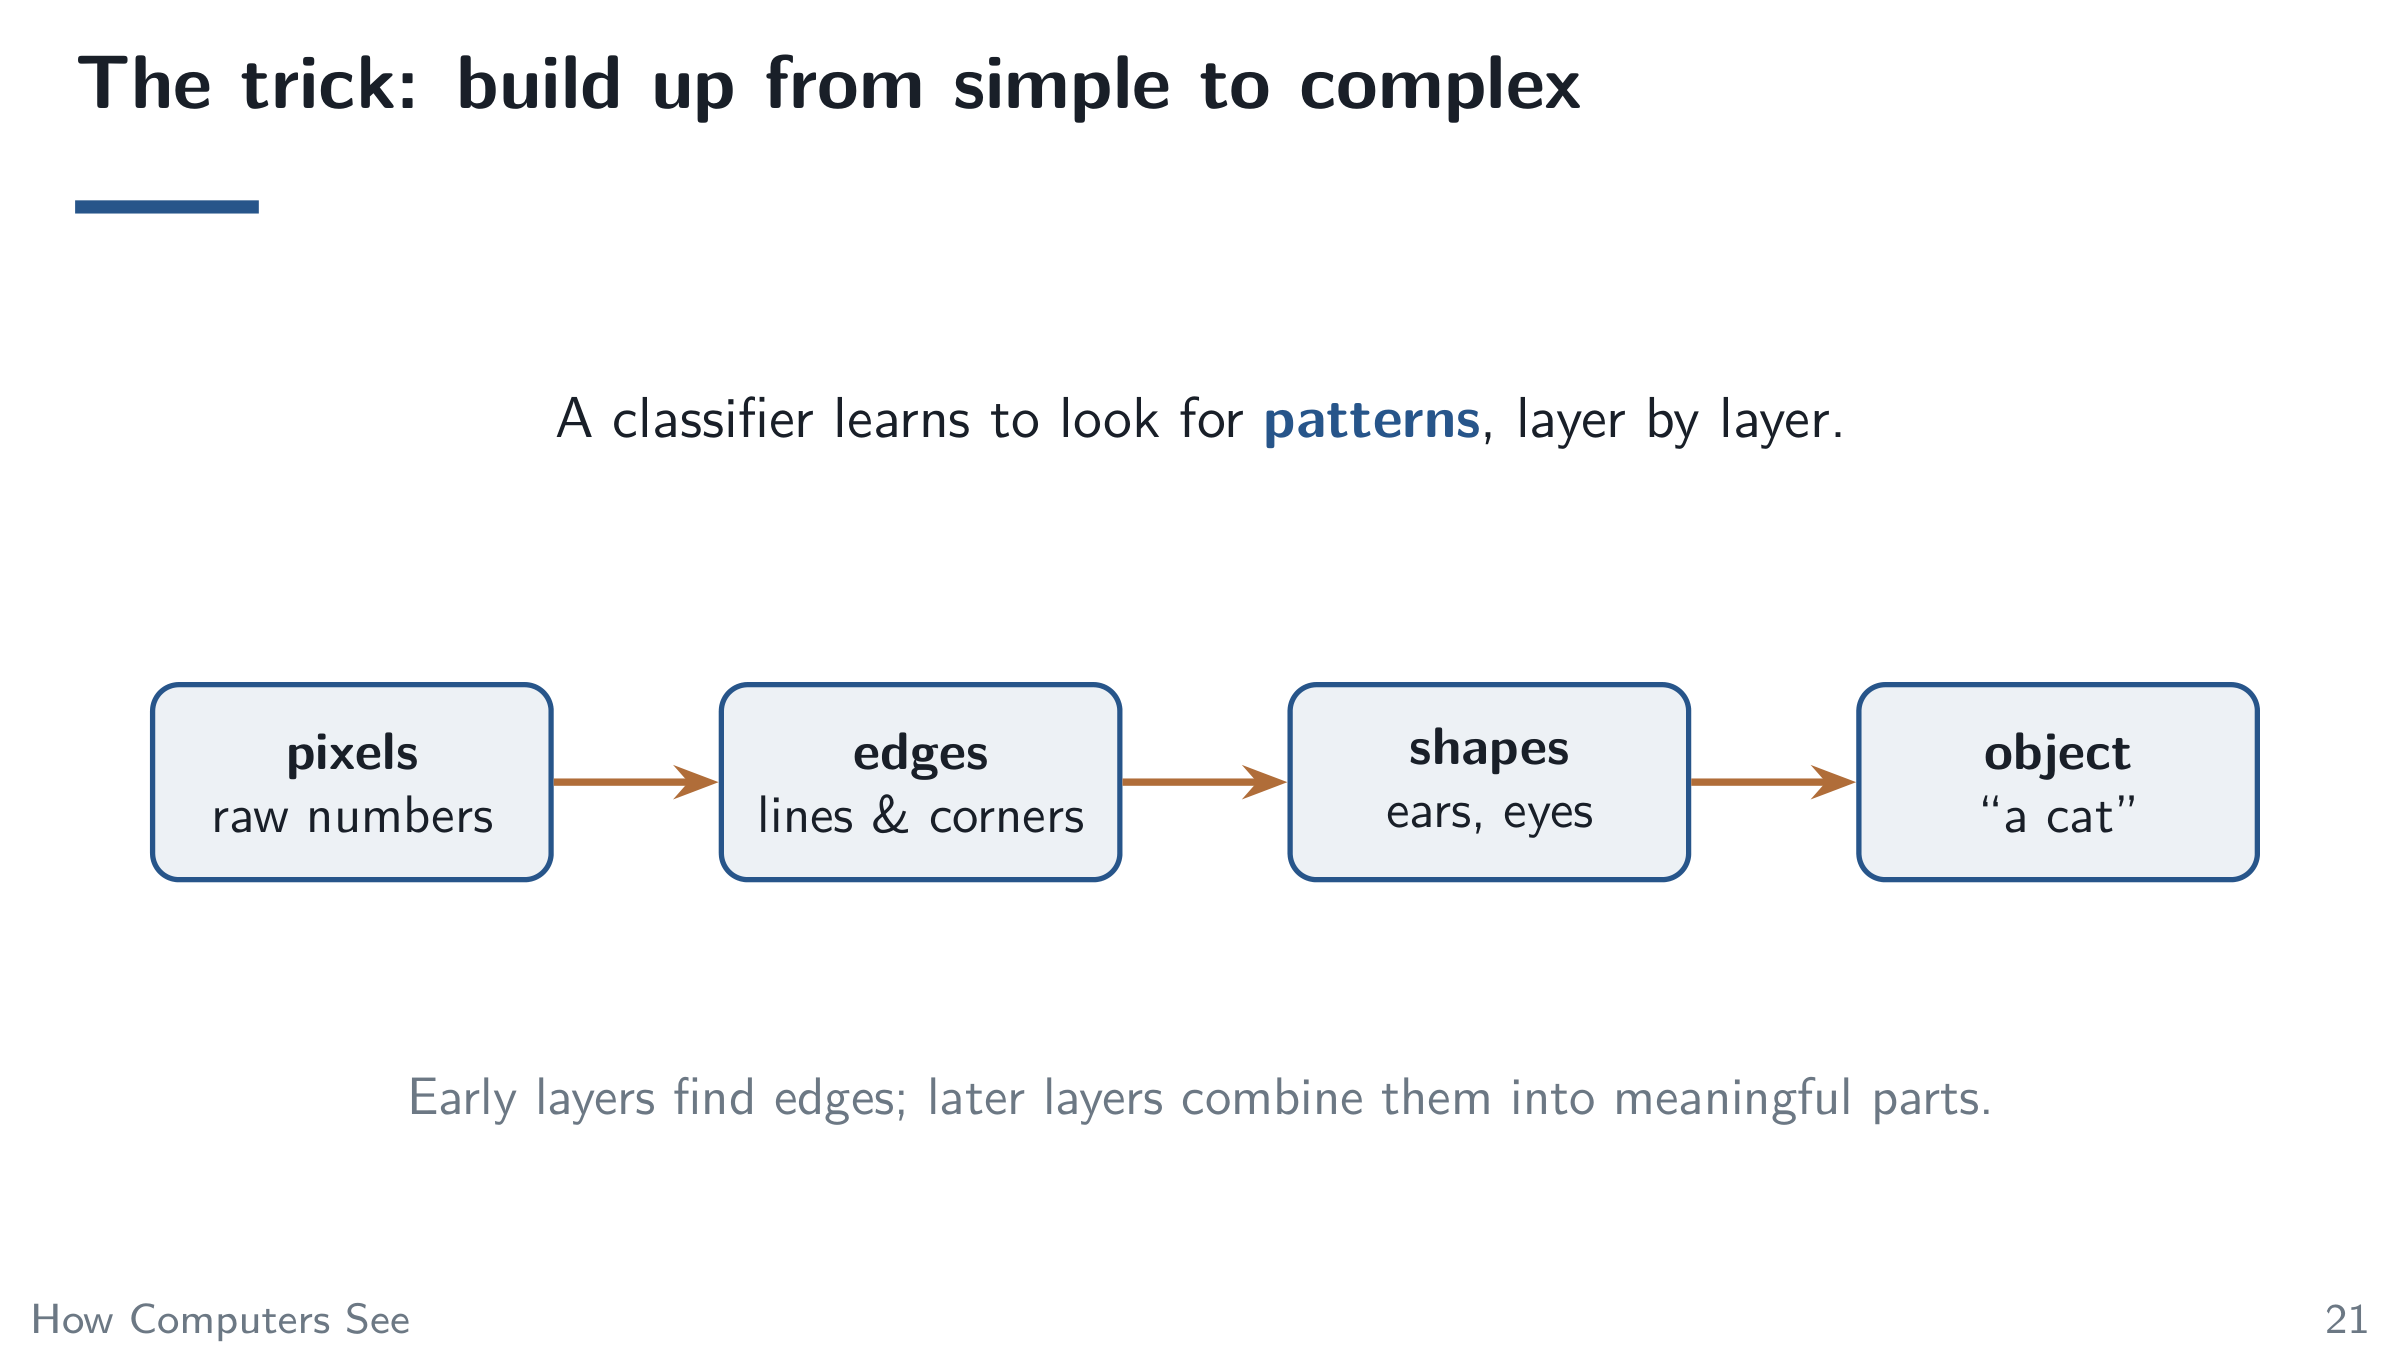
The trick: build up from simple to complex
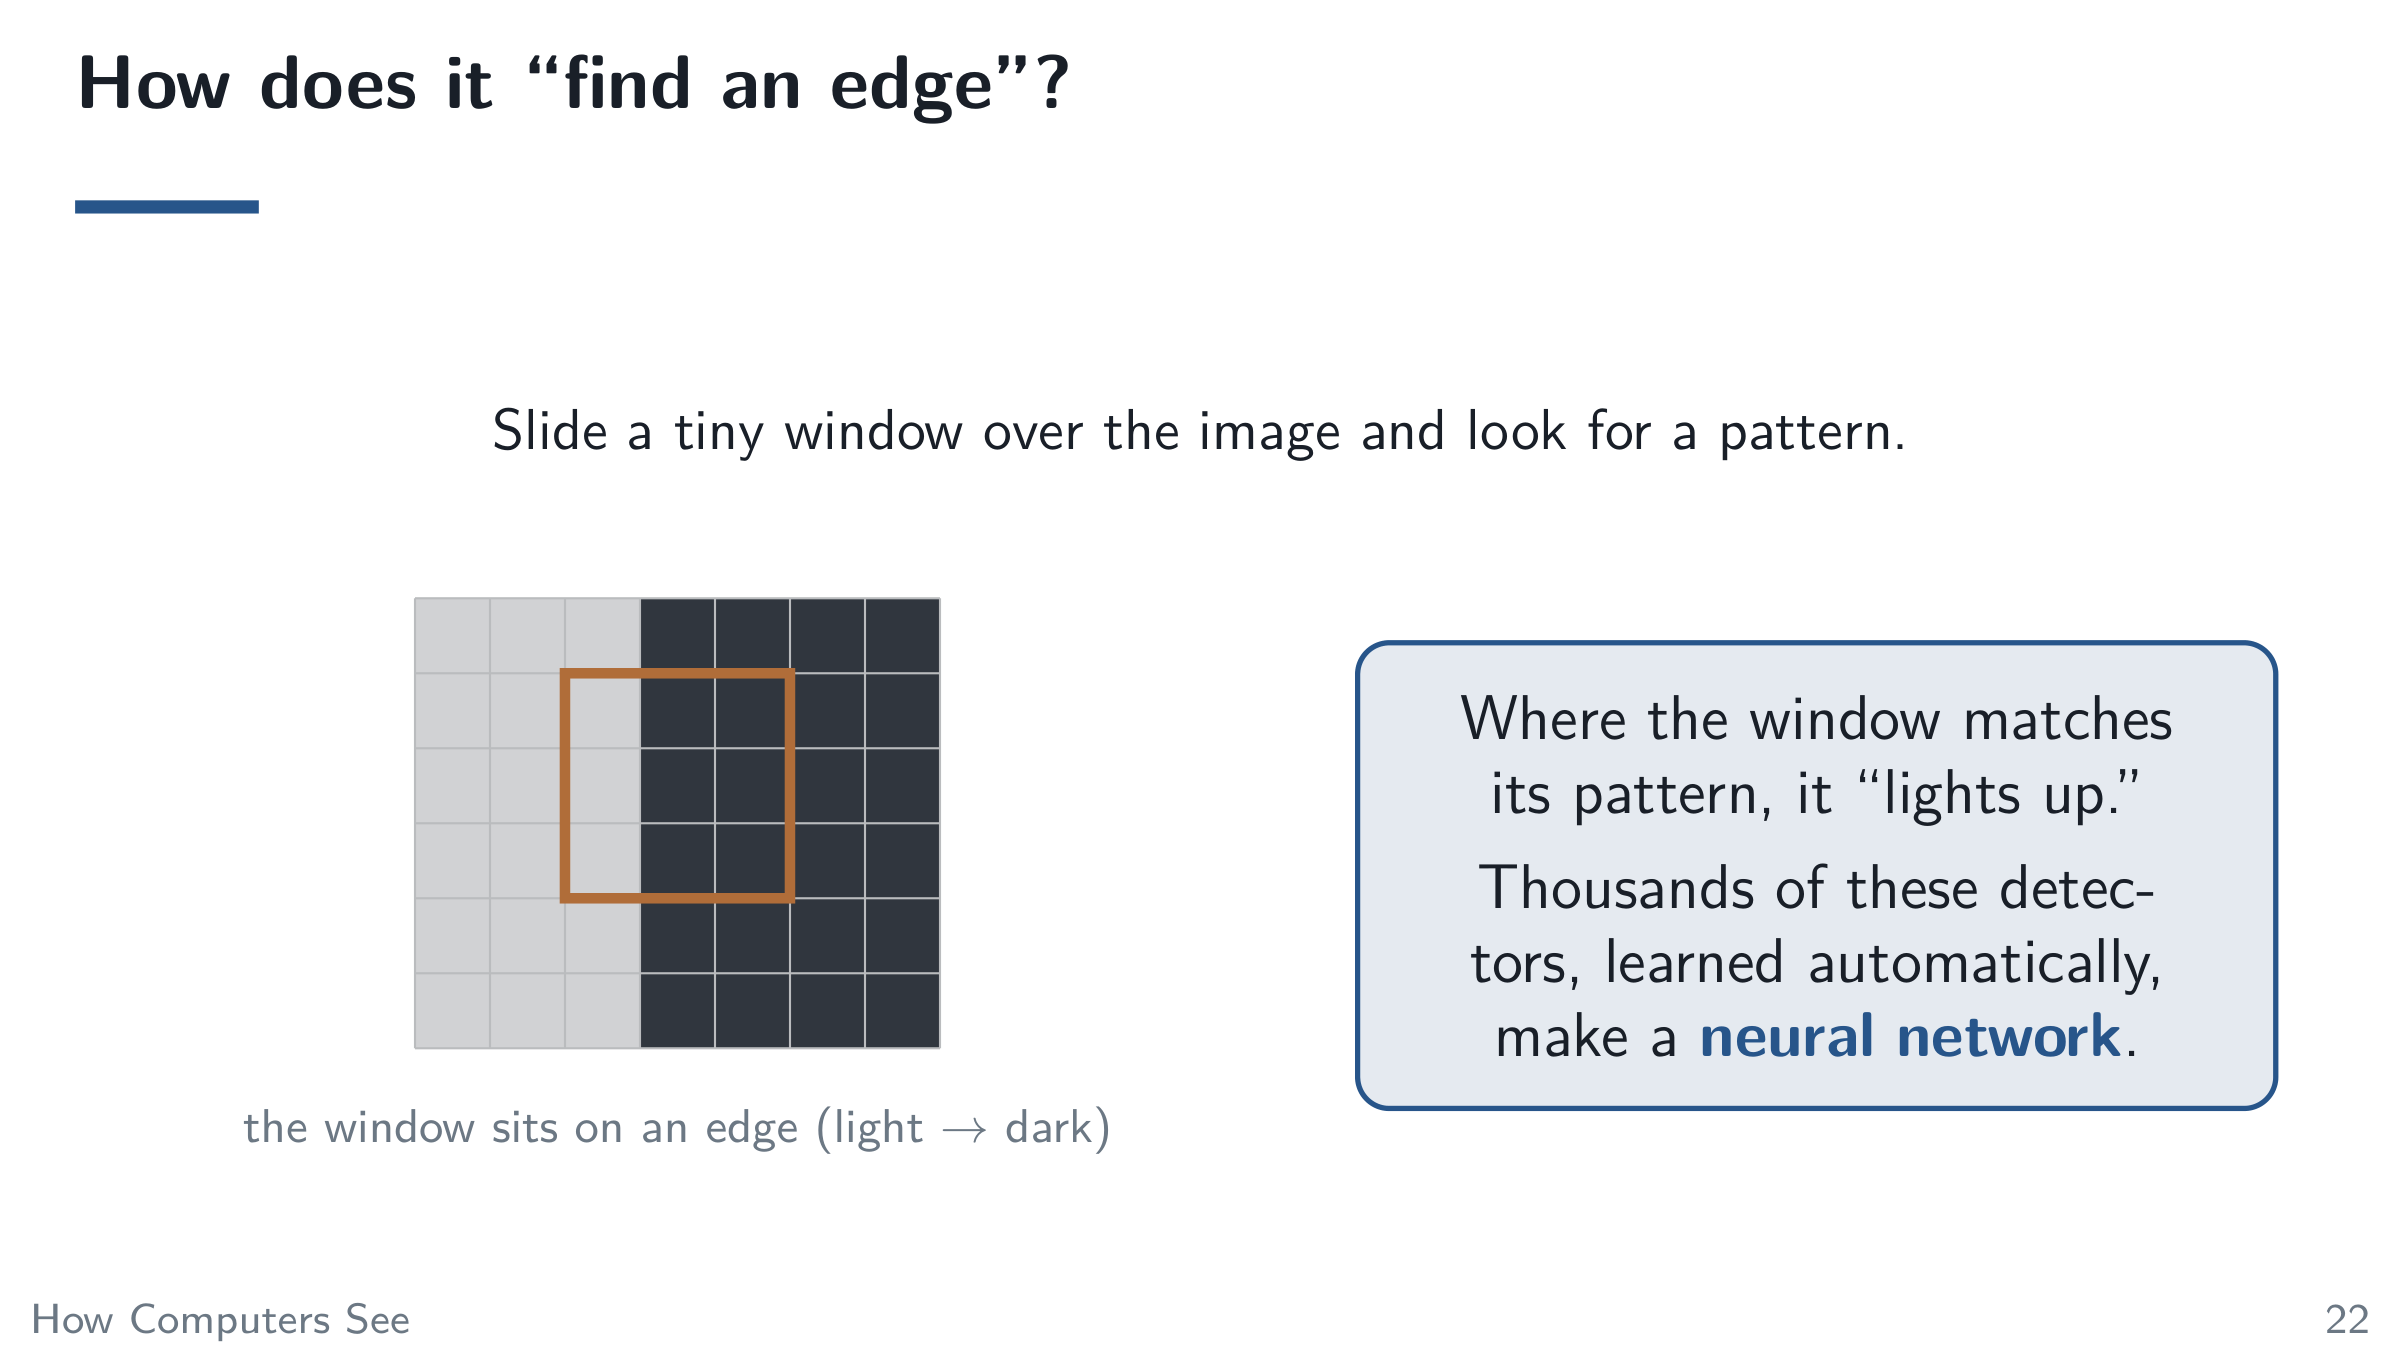
How does it “find an edge”?
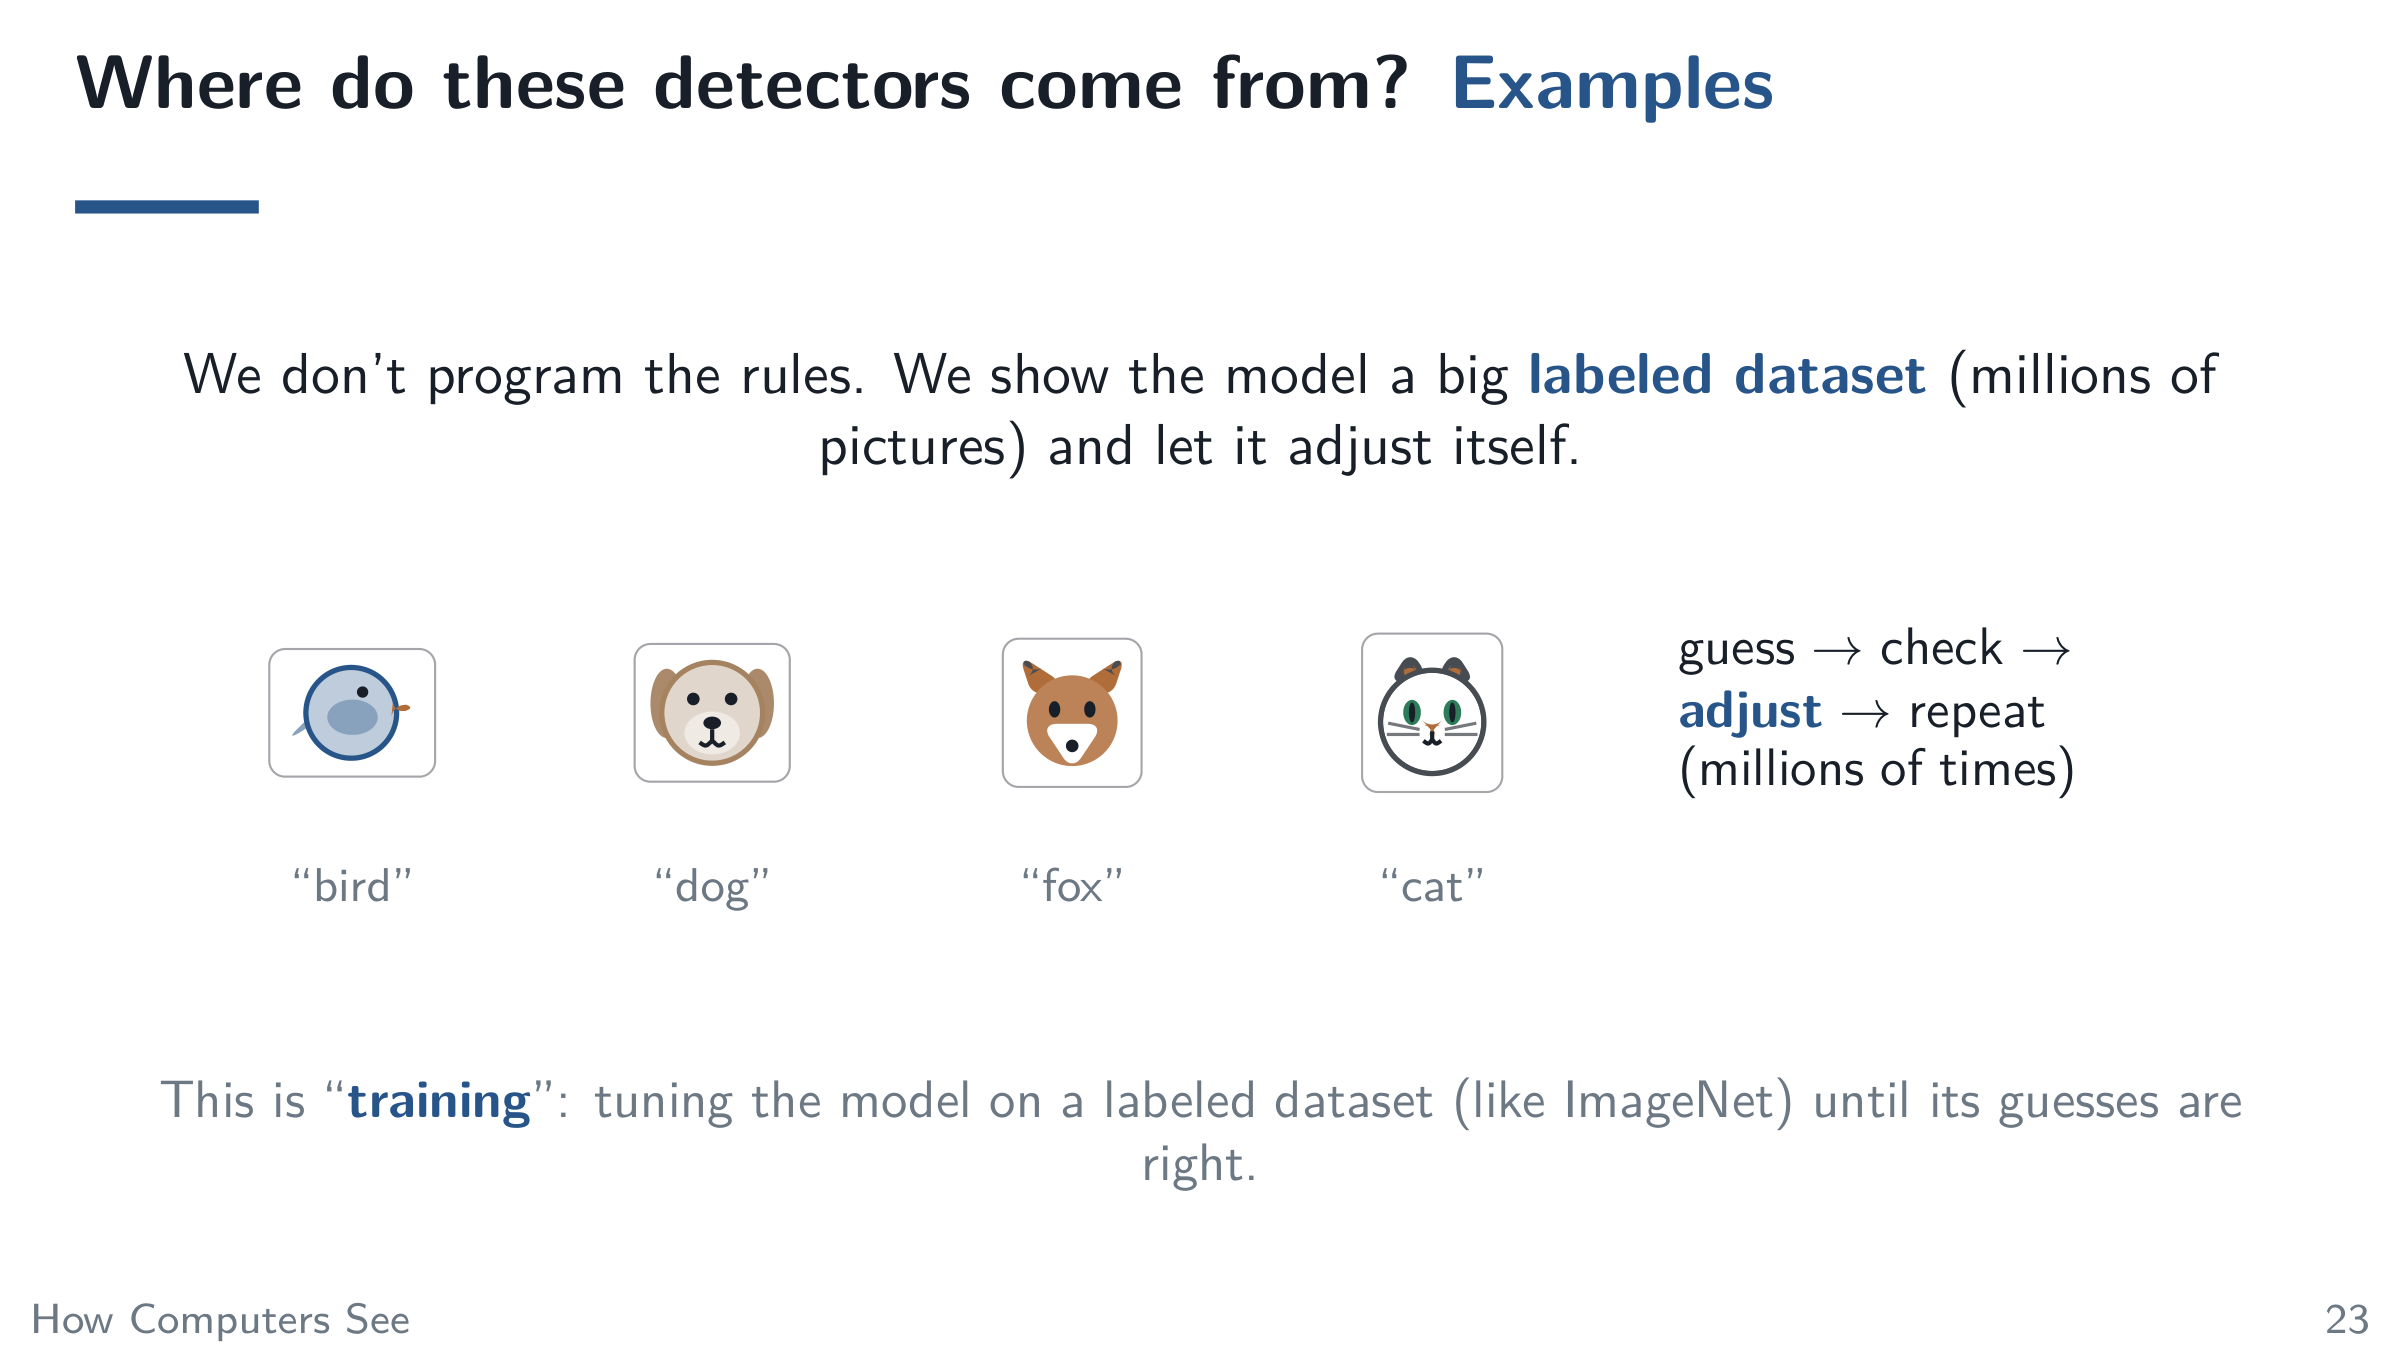
Where do these detectors come from?
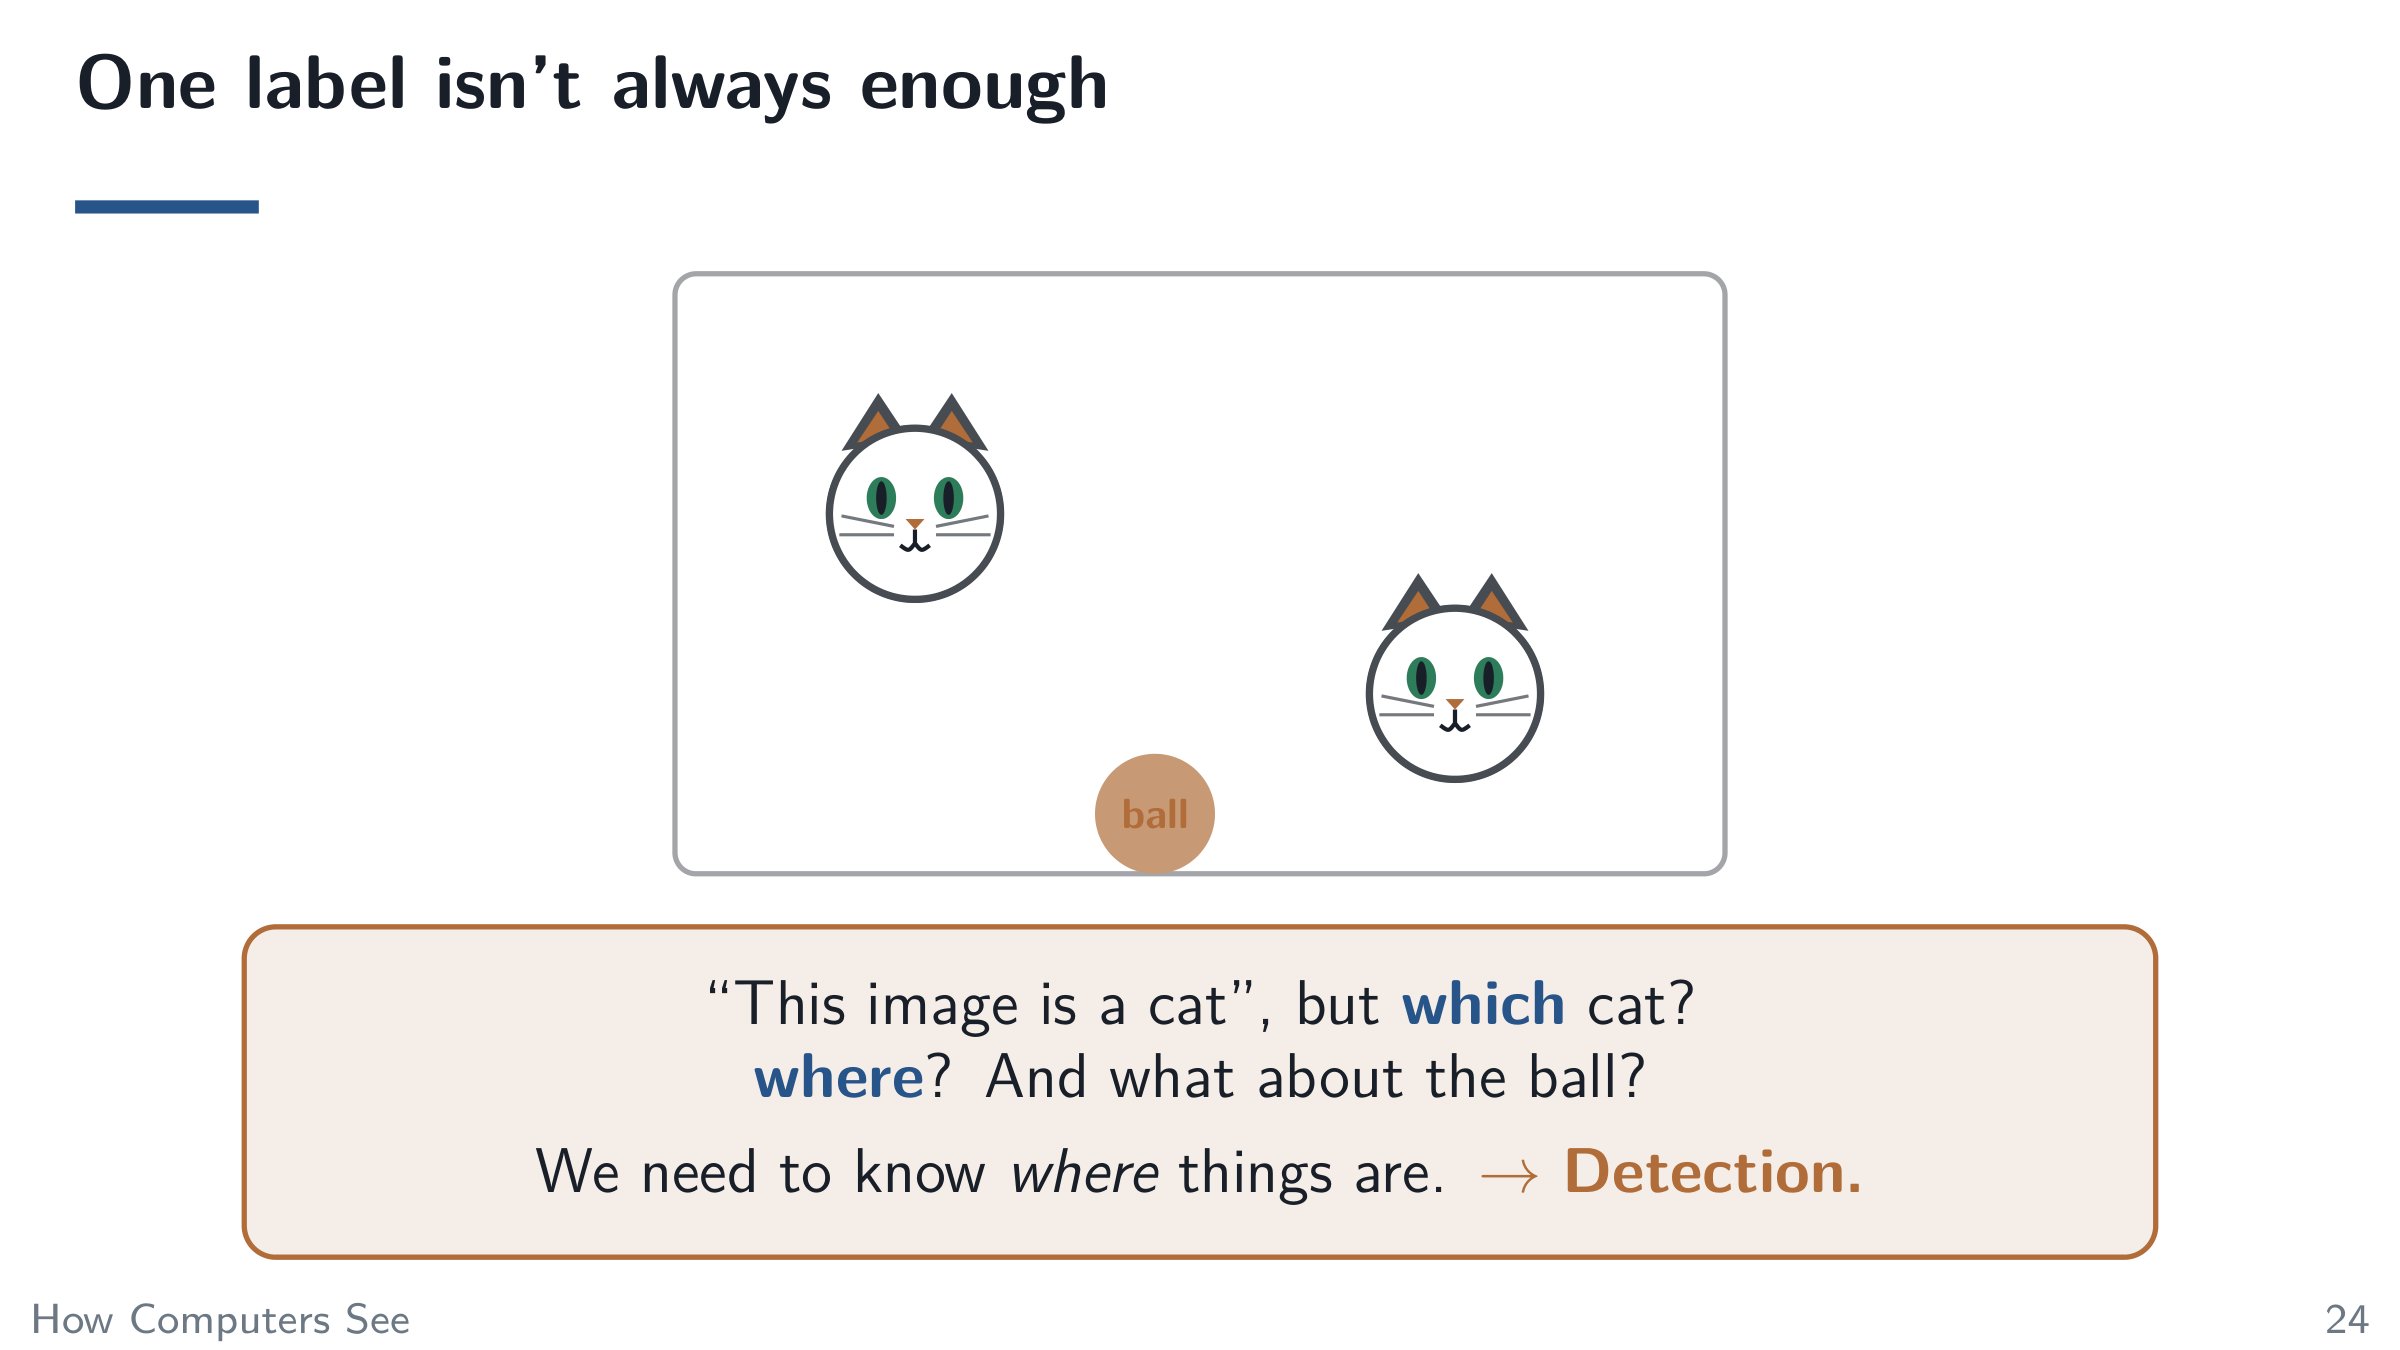
One label isn’t always enough
Demo: Classify a photo ▶︎ Open Lab 4B
Object Detection
Detection asks: what and where?
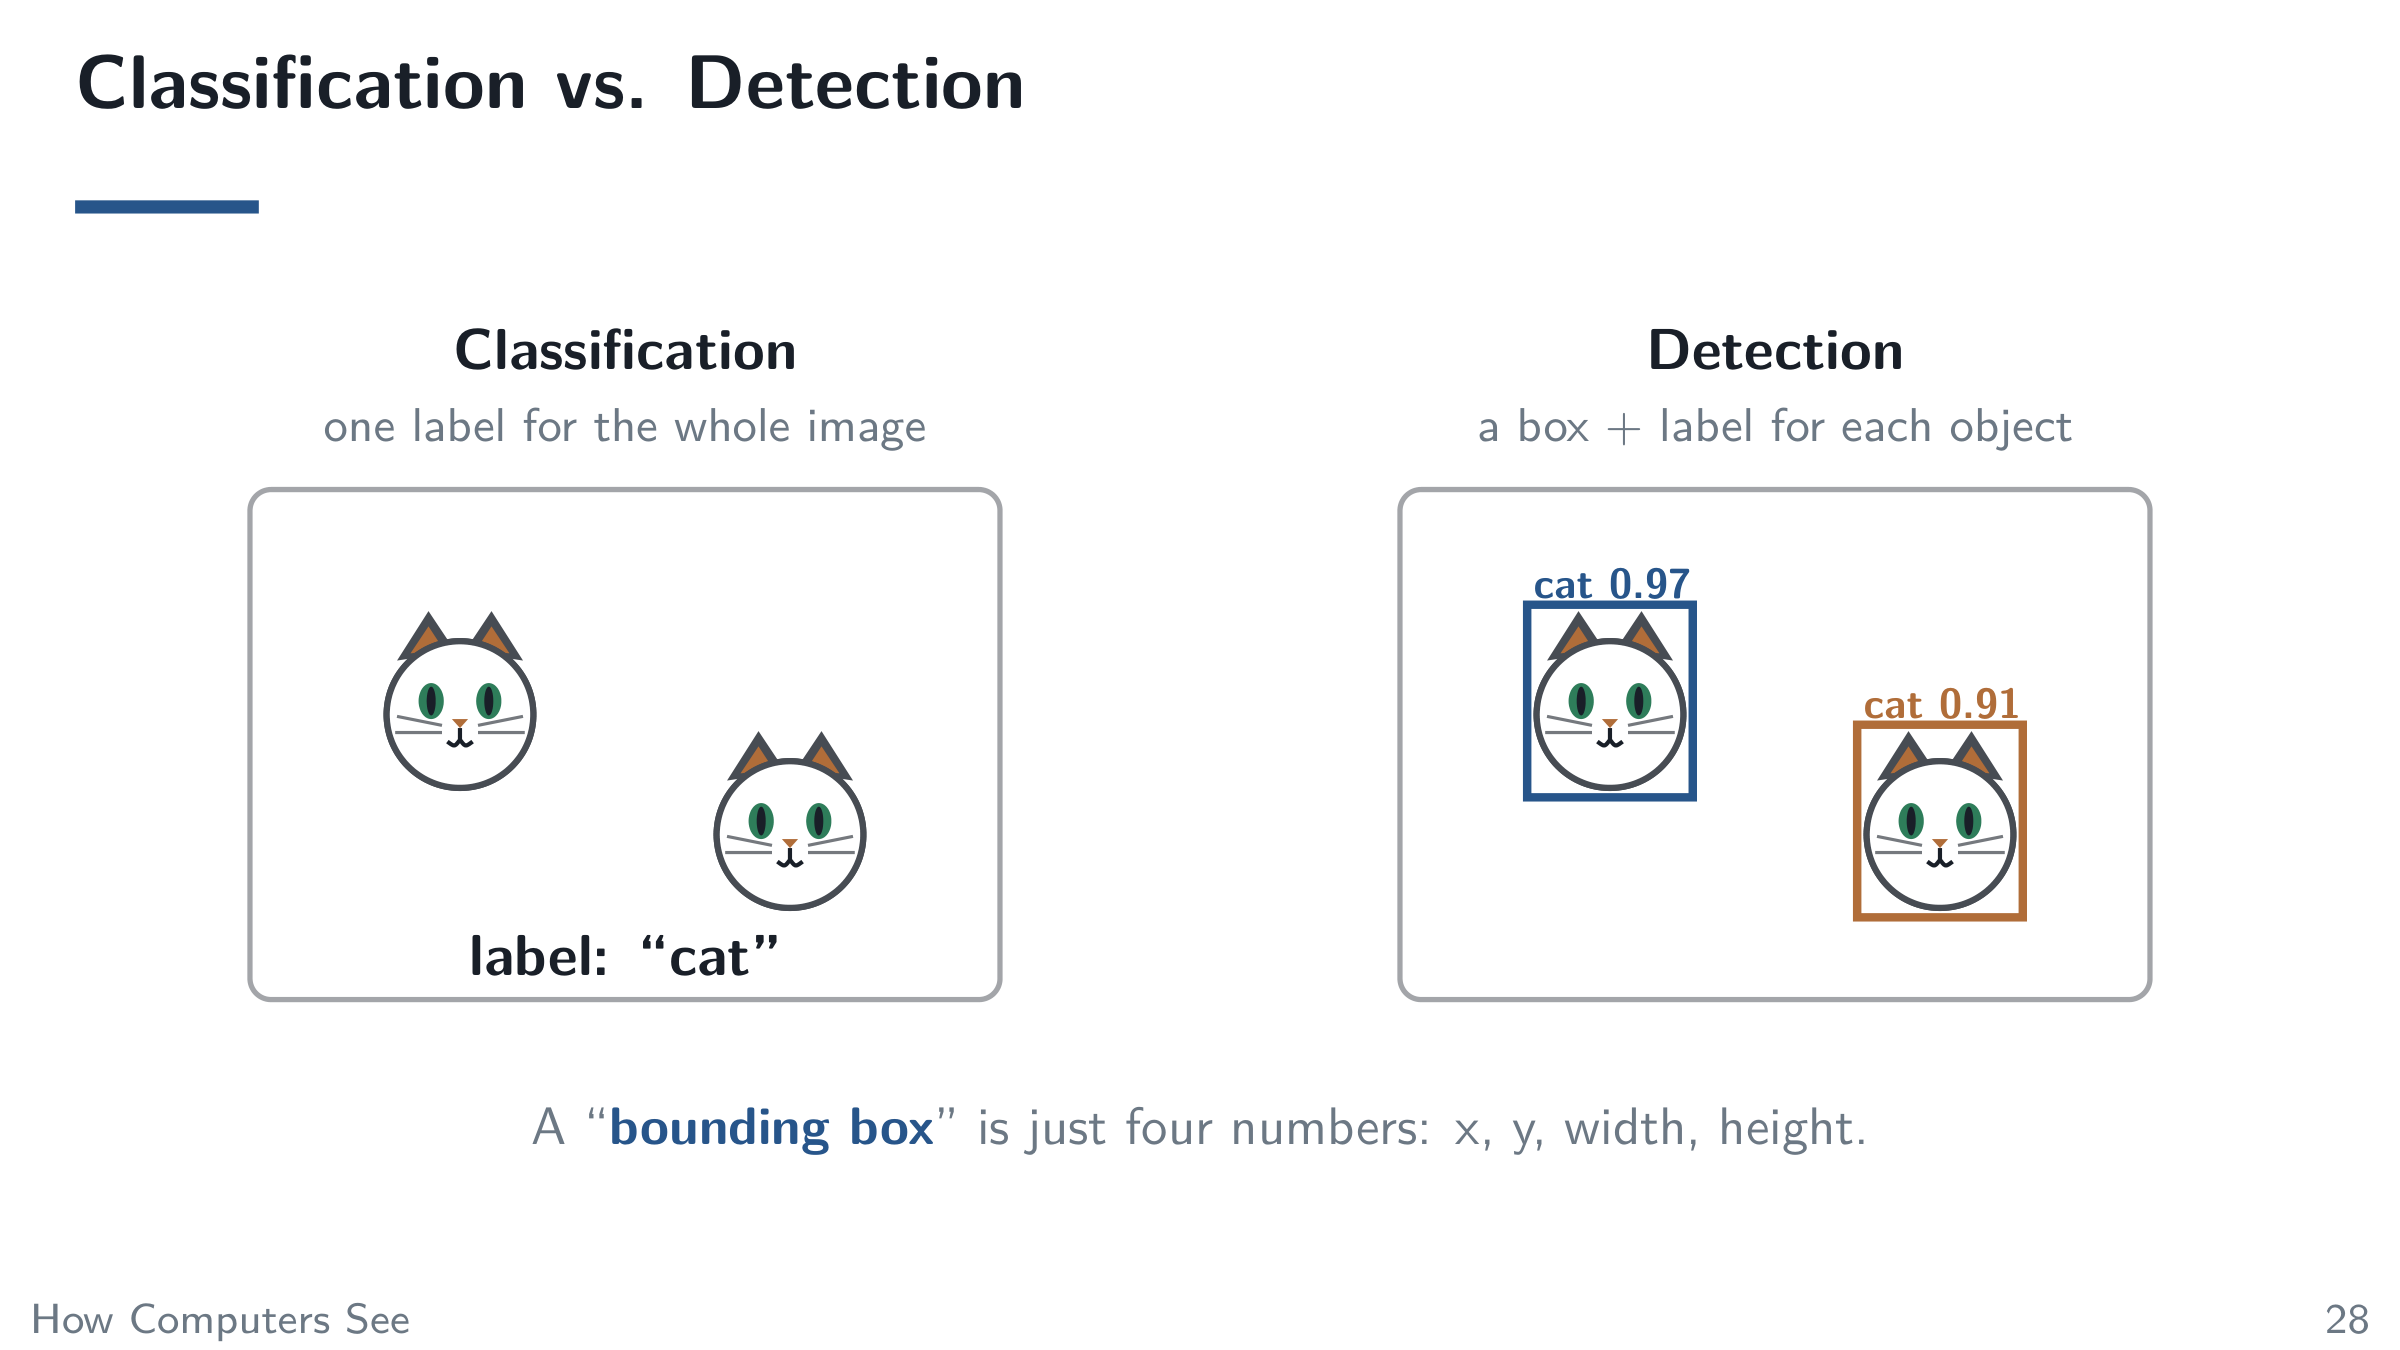
Classification vs. Detection
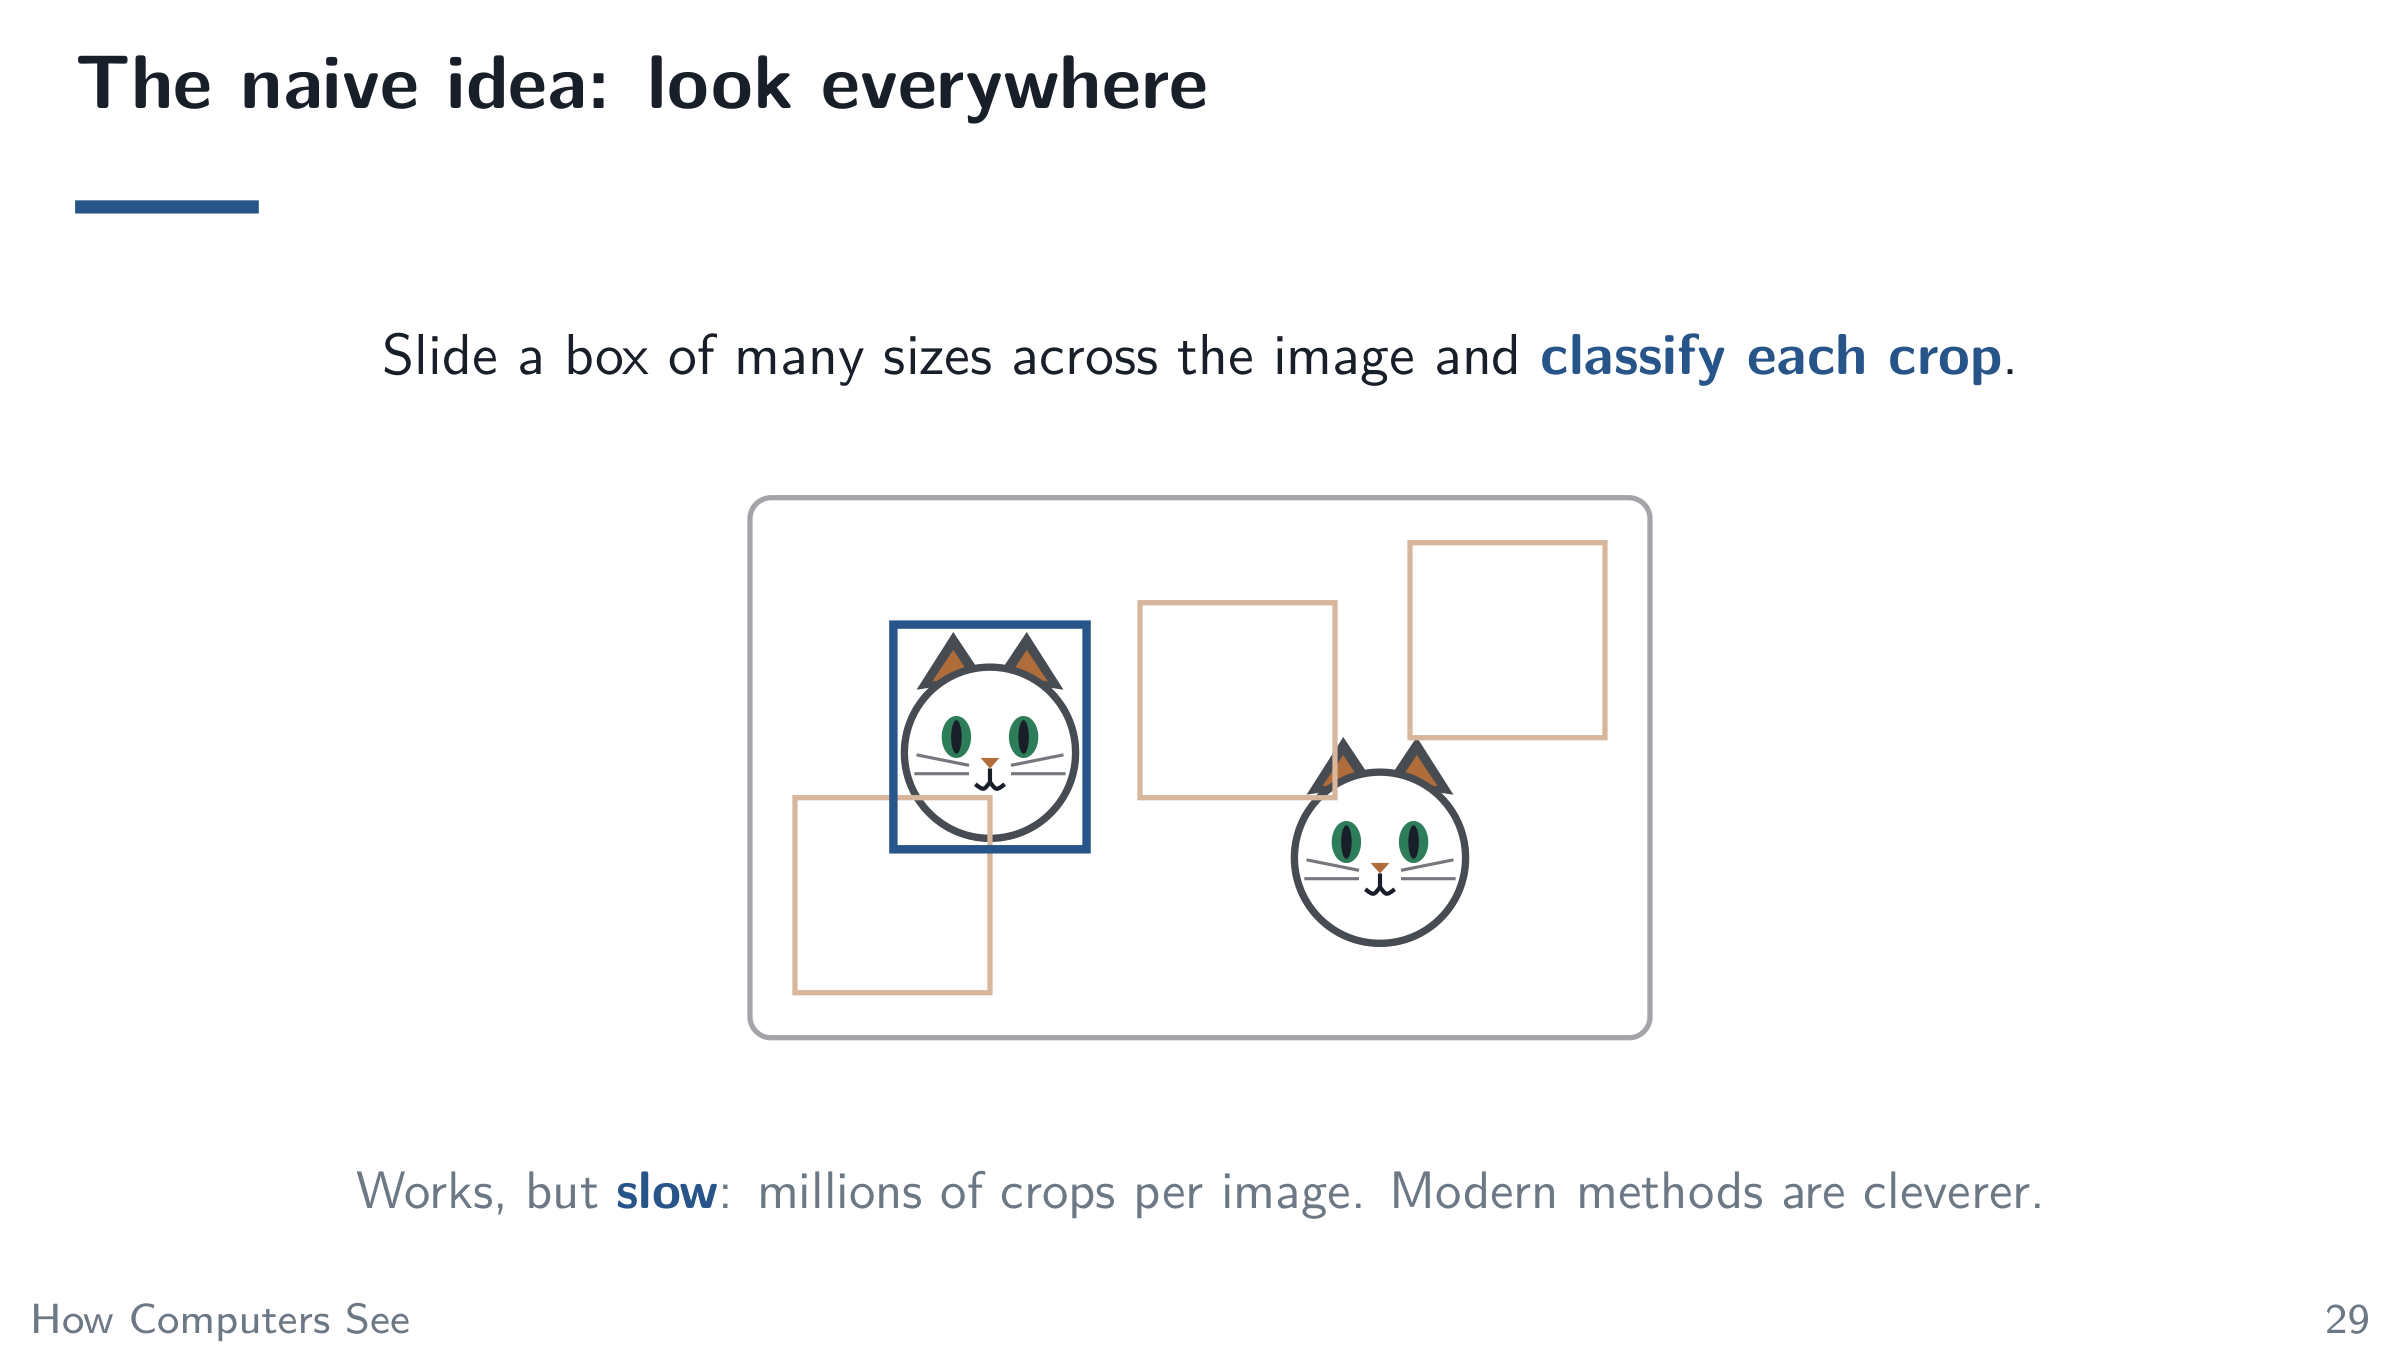
The naive idea: look everywhere
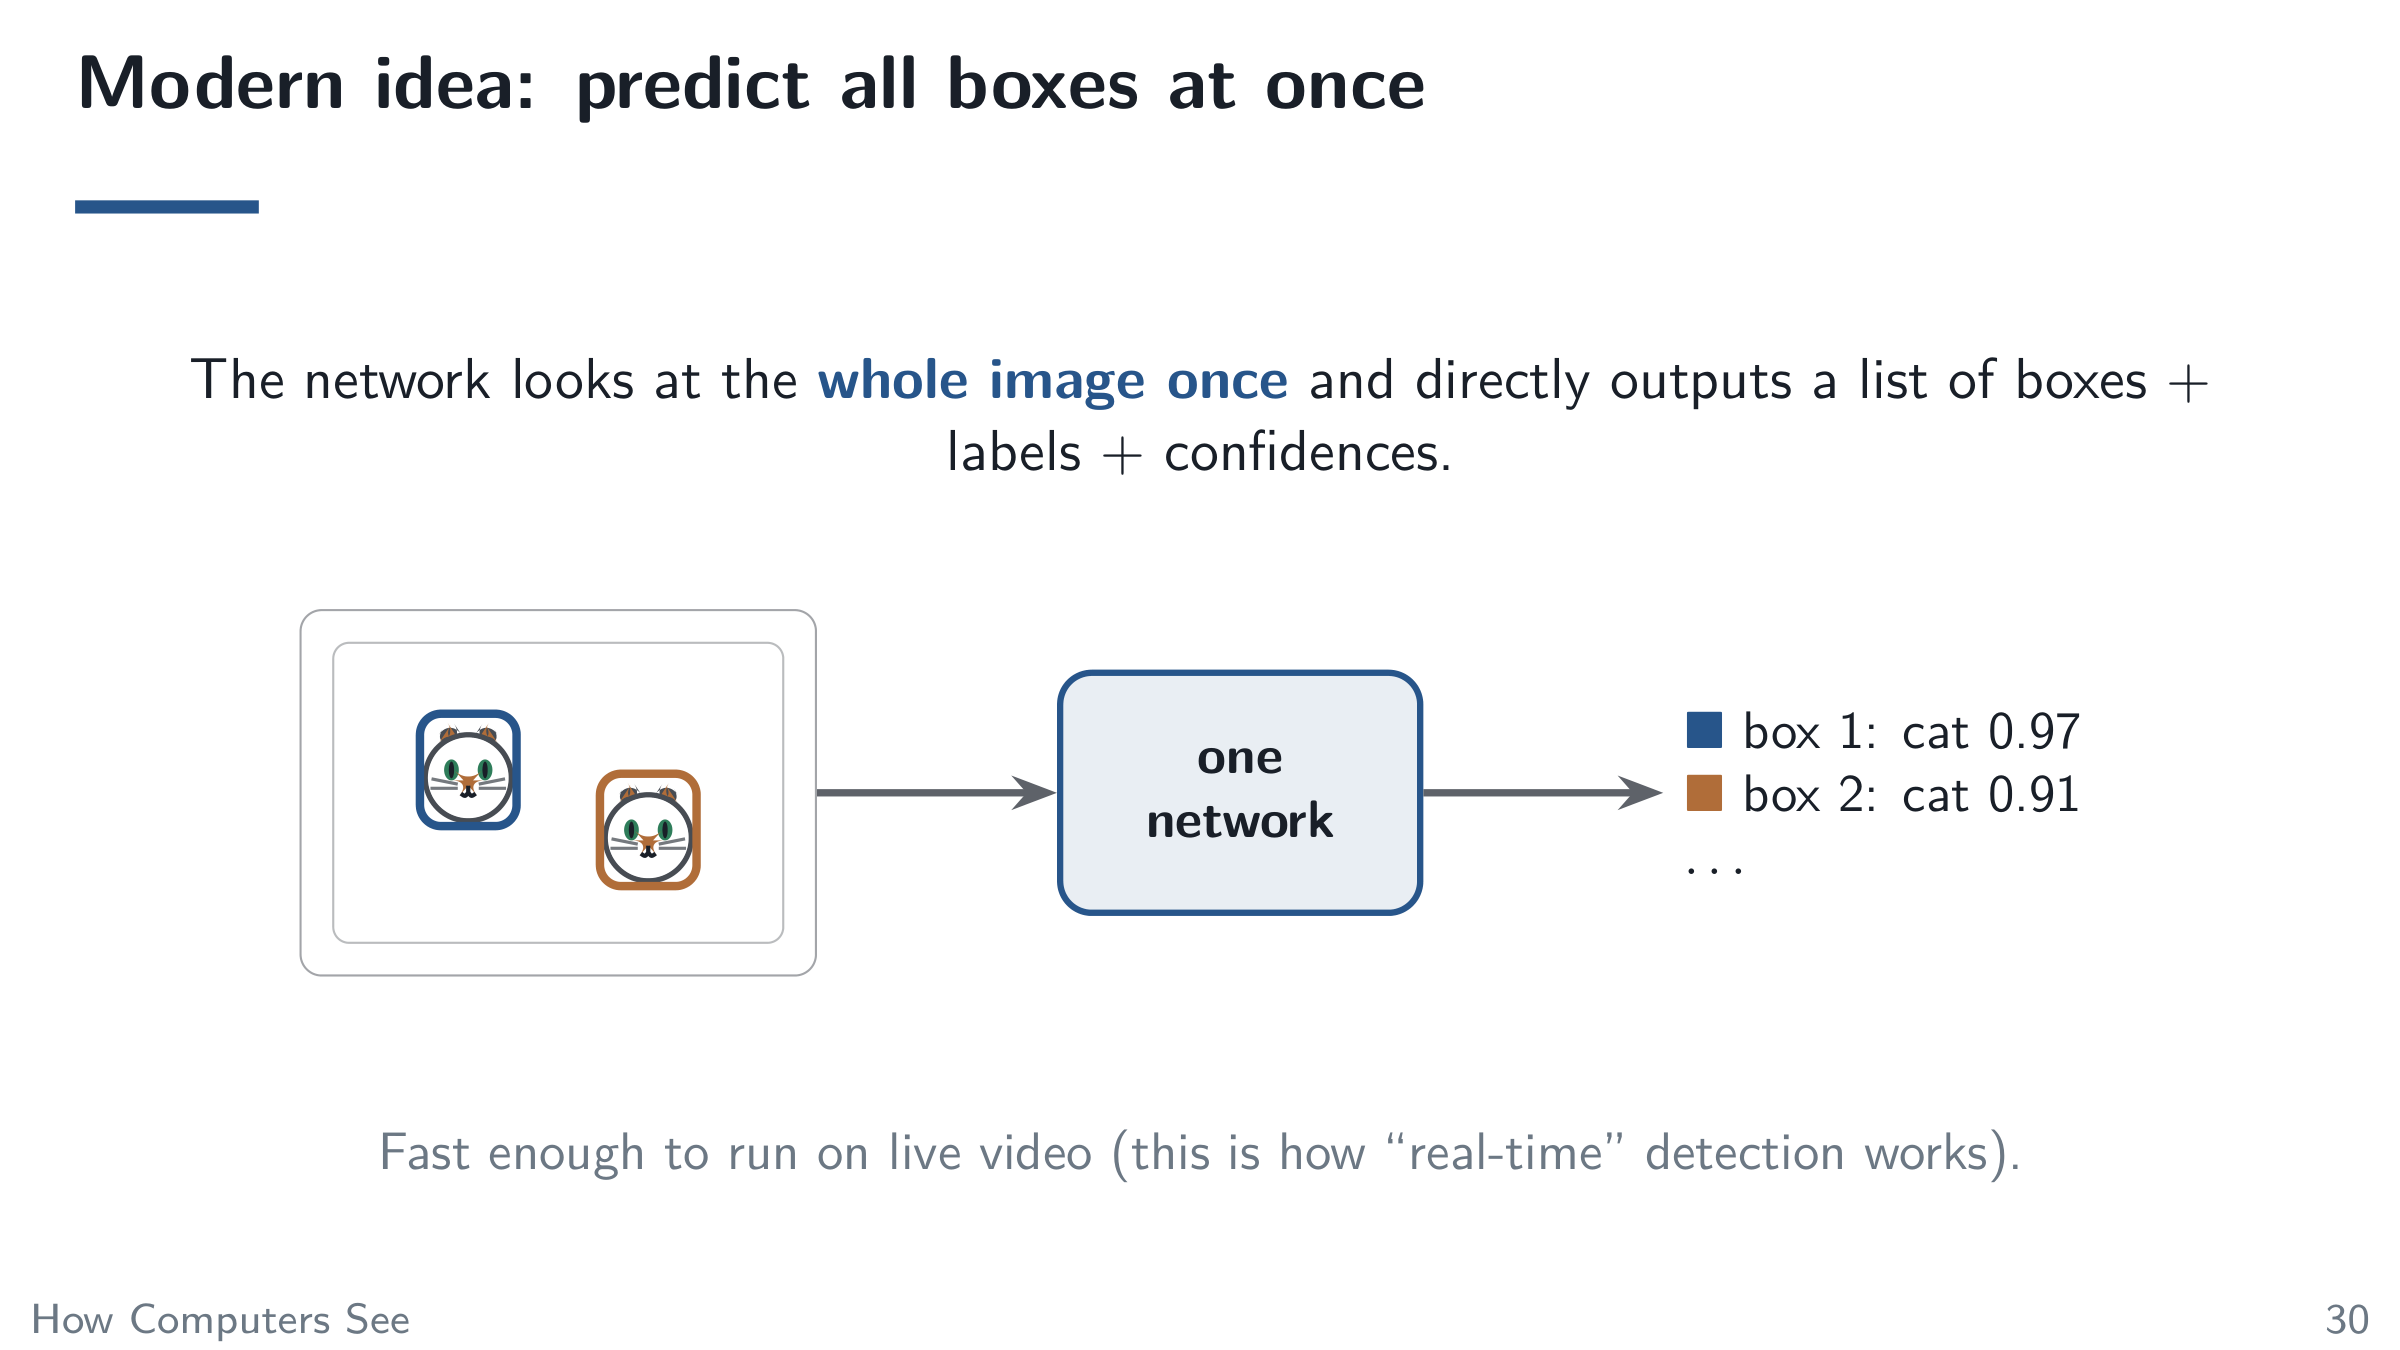
Modern idea: predict all boxes at once
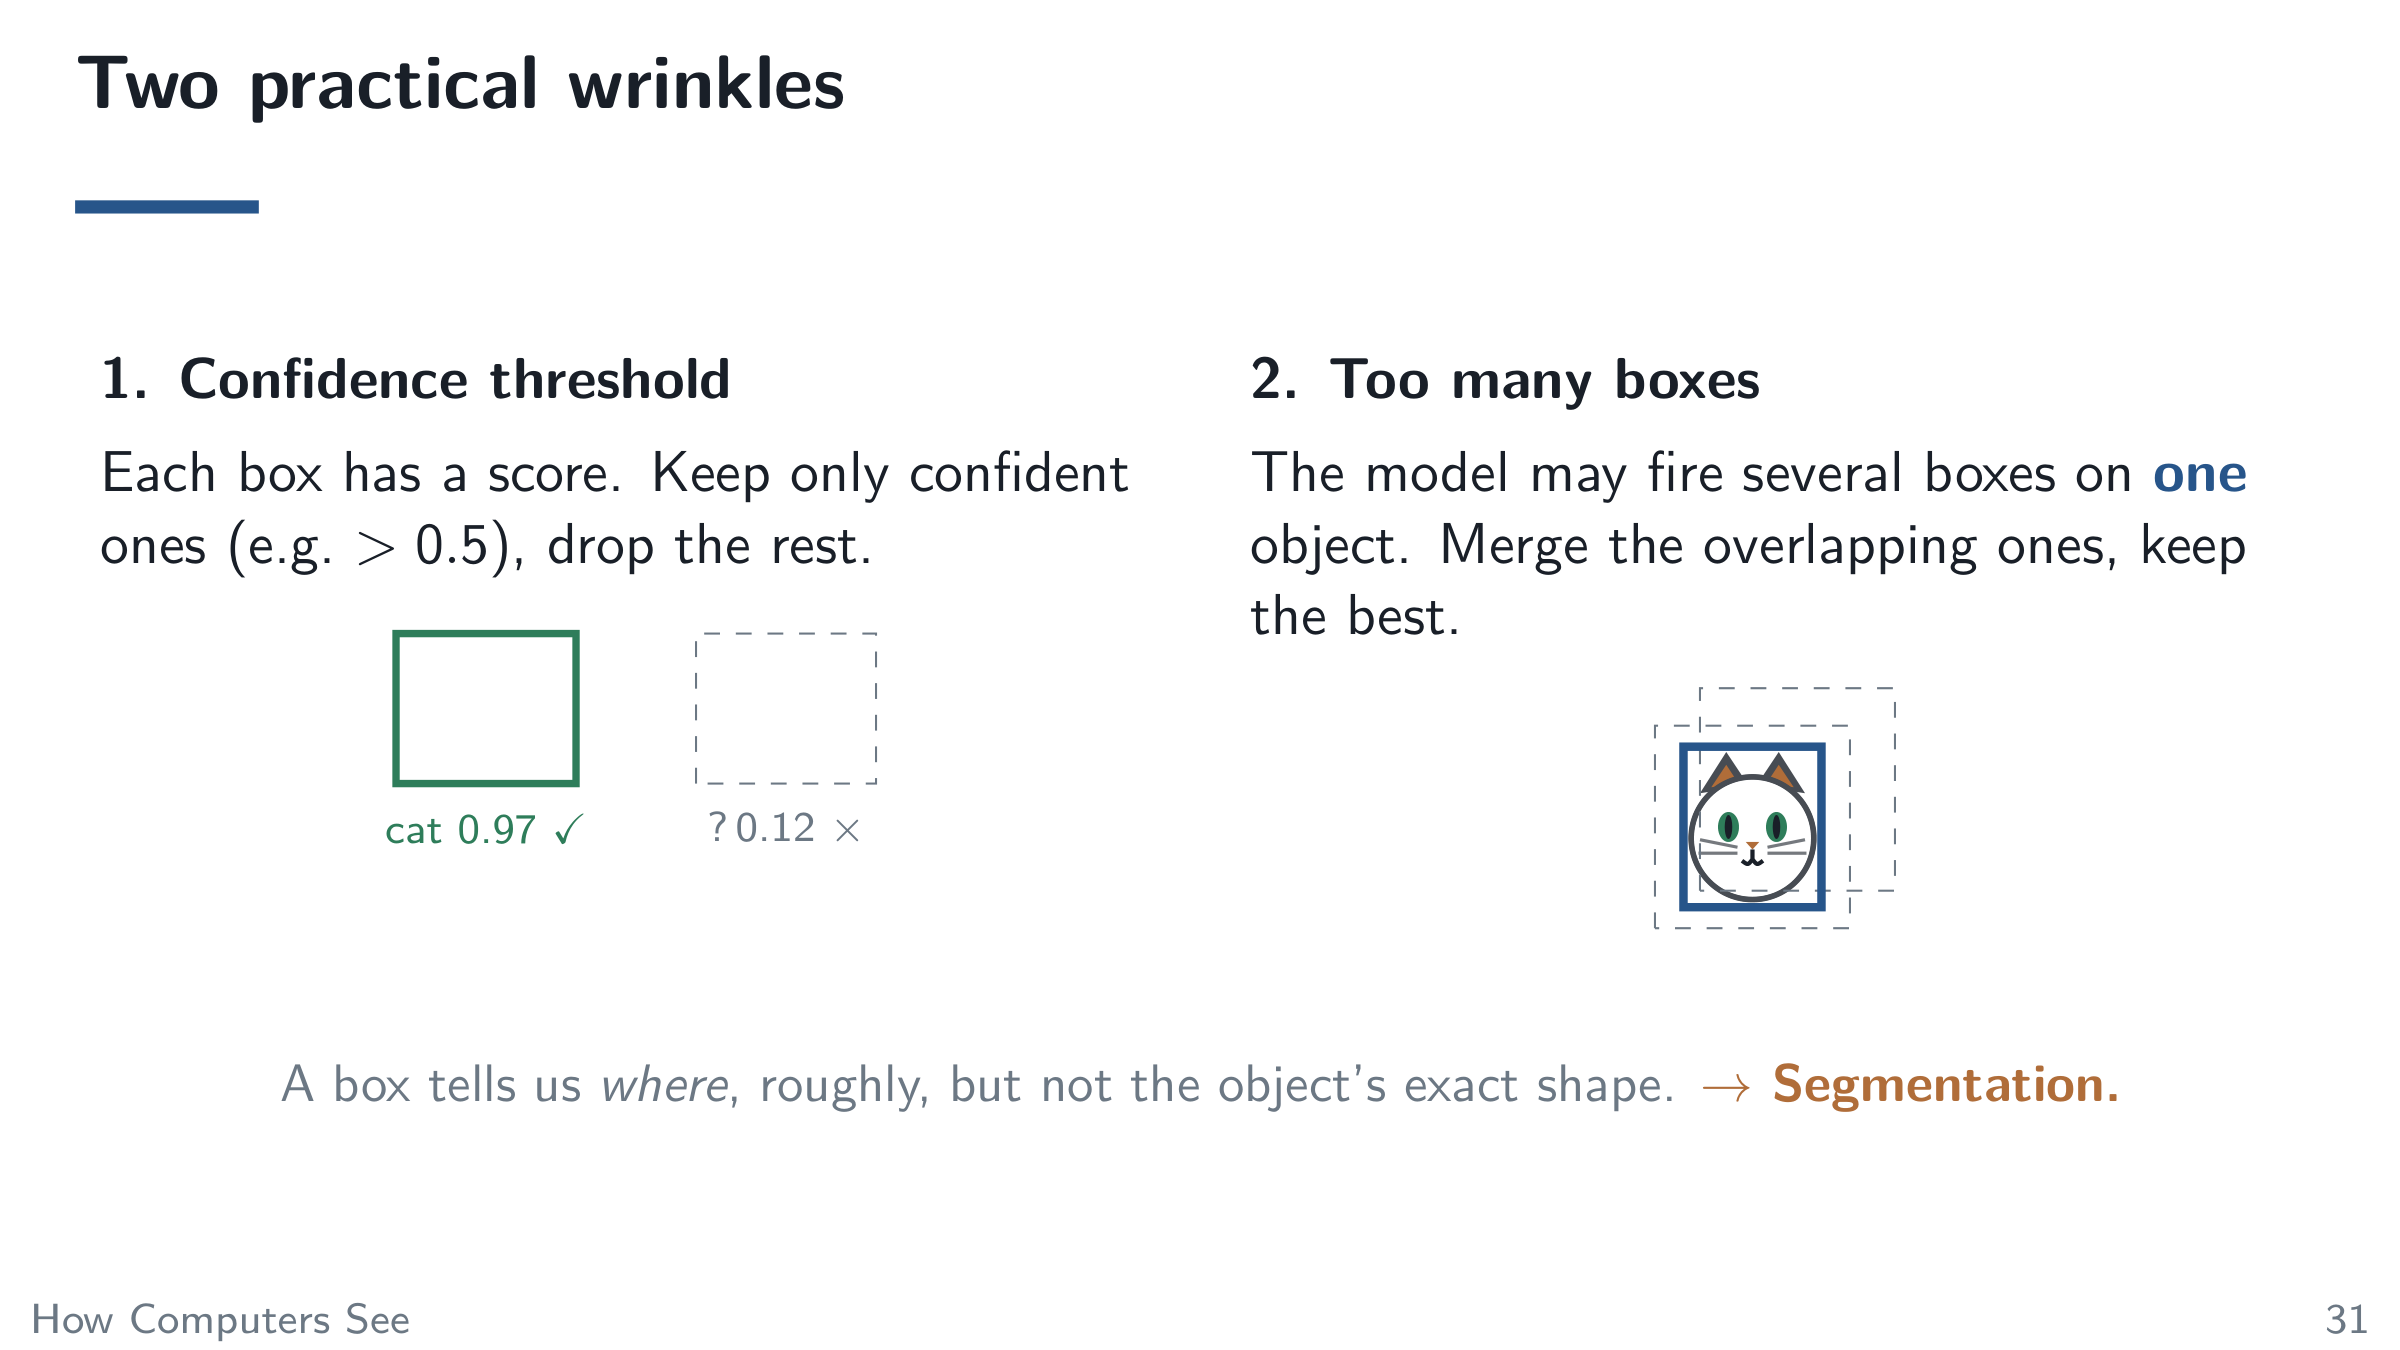
Two practical wrinkles
Demo: Detect objects ▶︎ Open Lab 4C
Object Segmentation
Segmentation asks: which exact pixels?
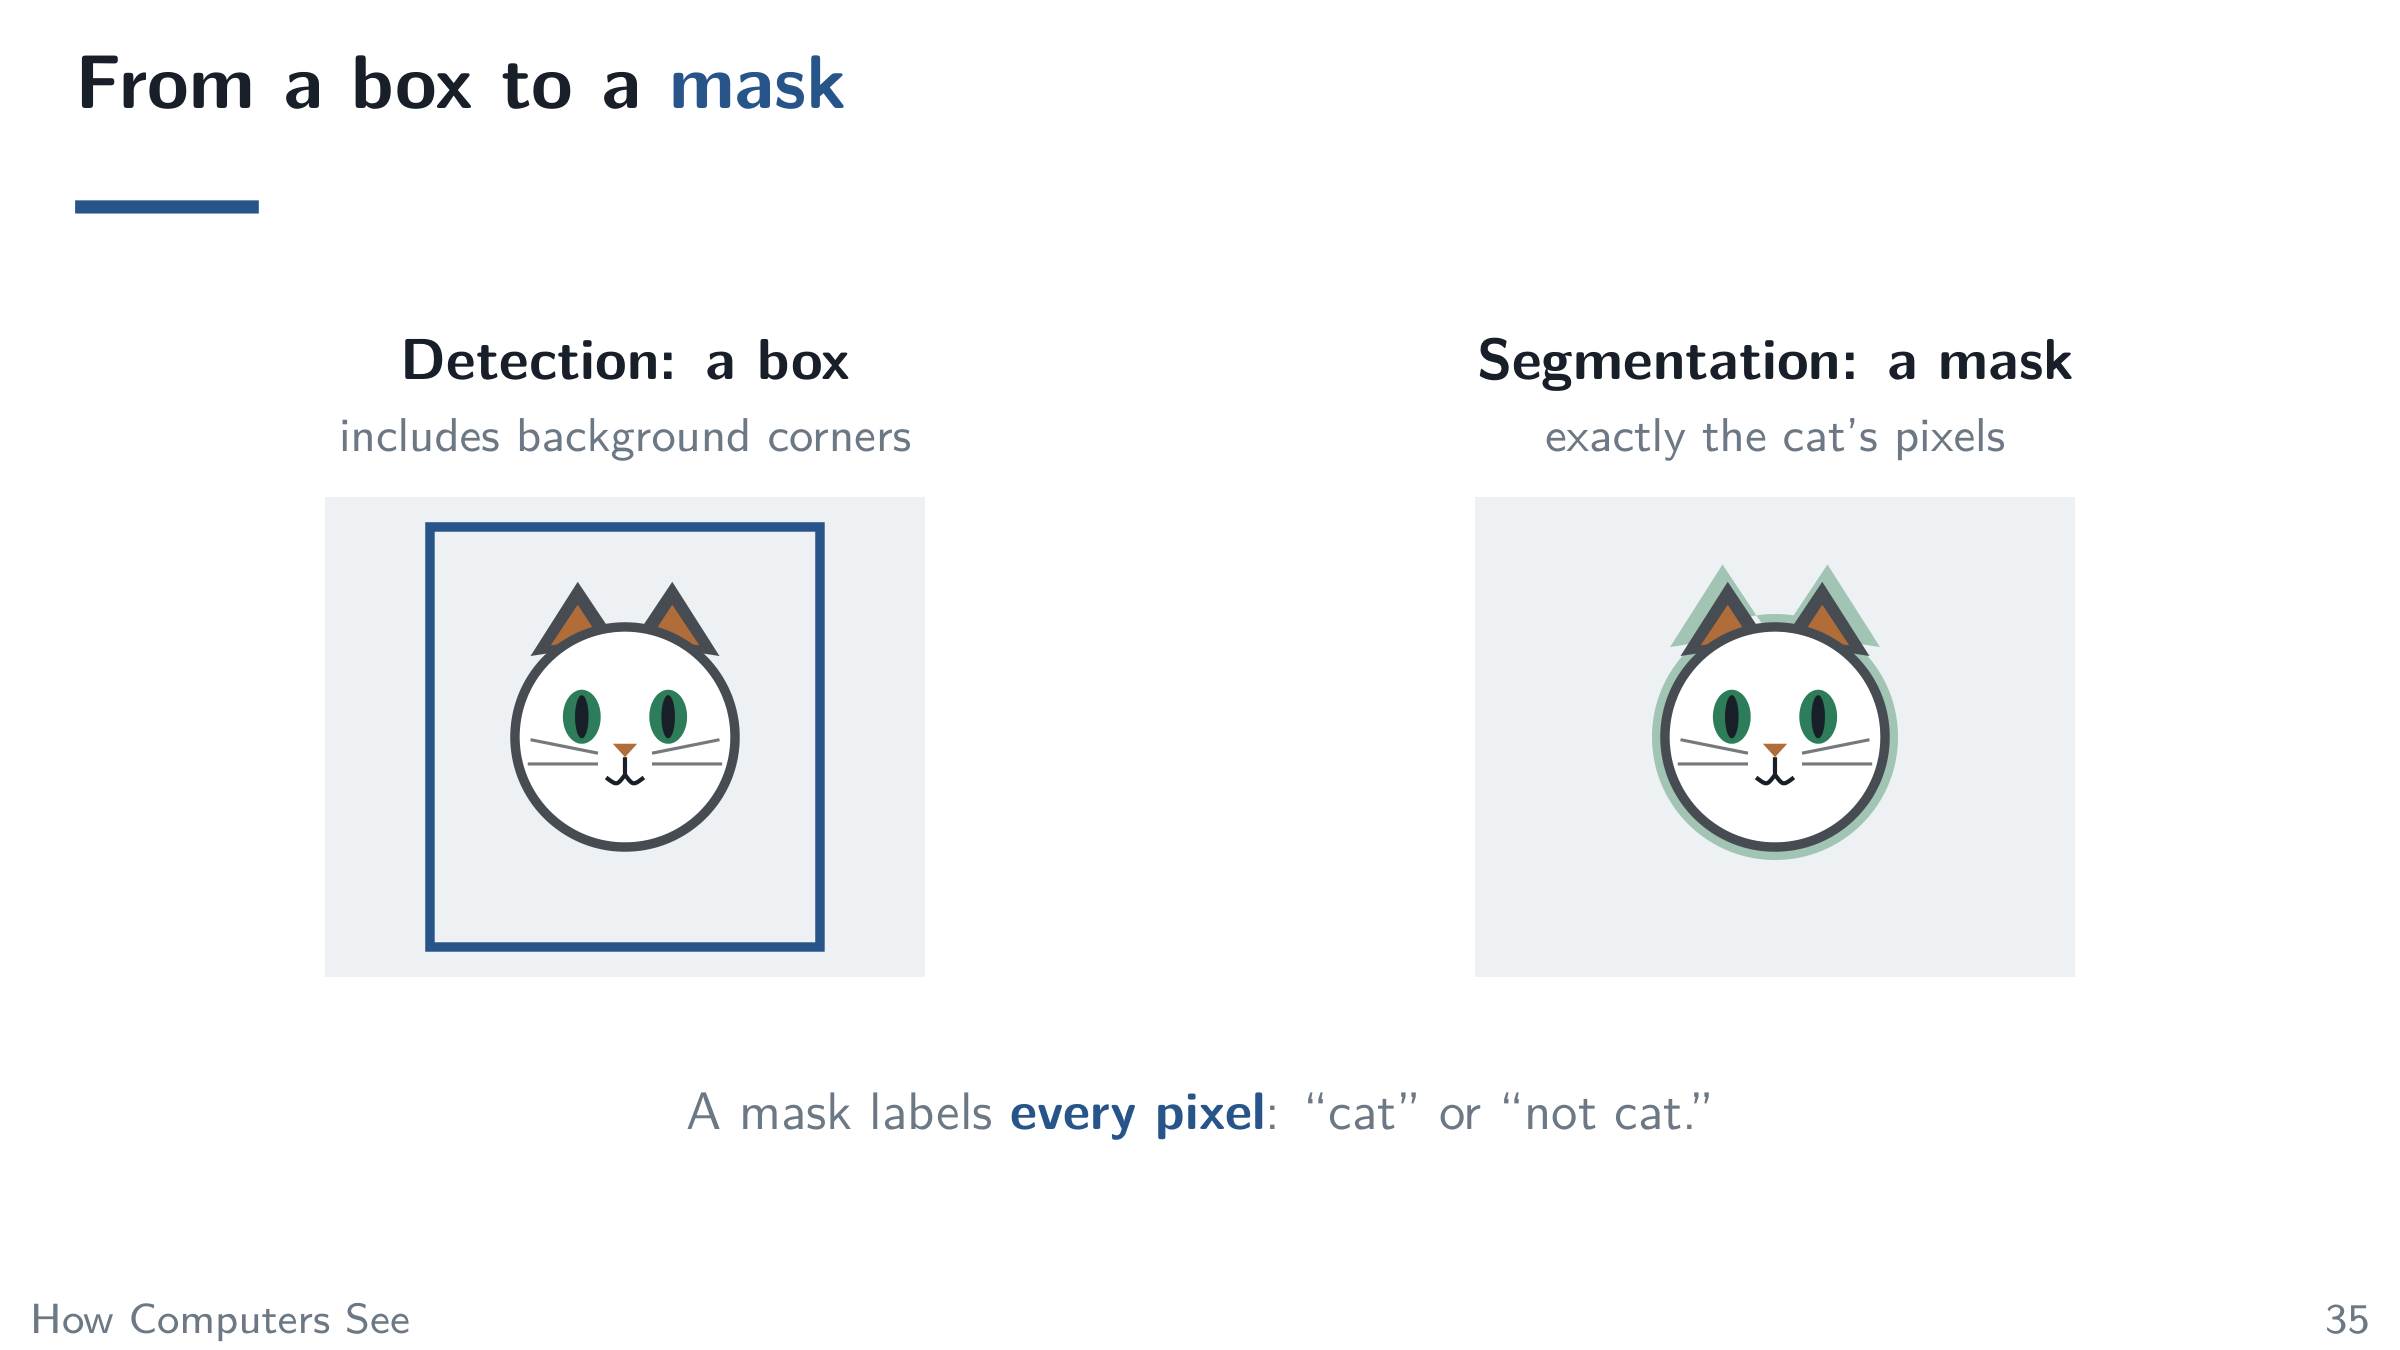
From a box to a mask
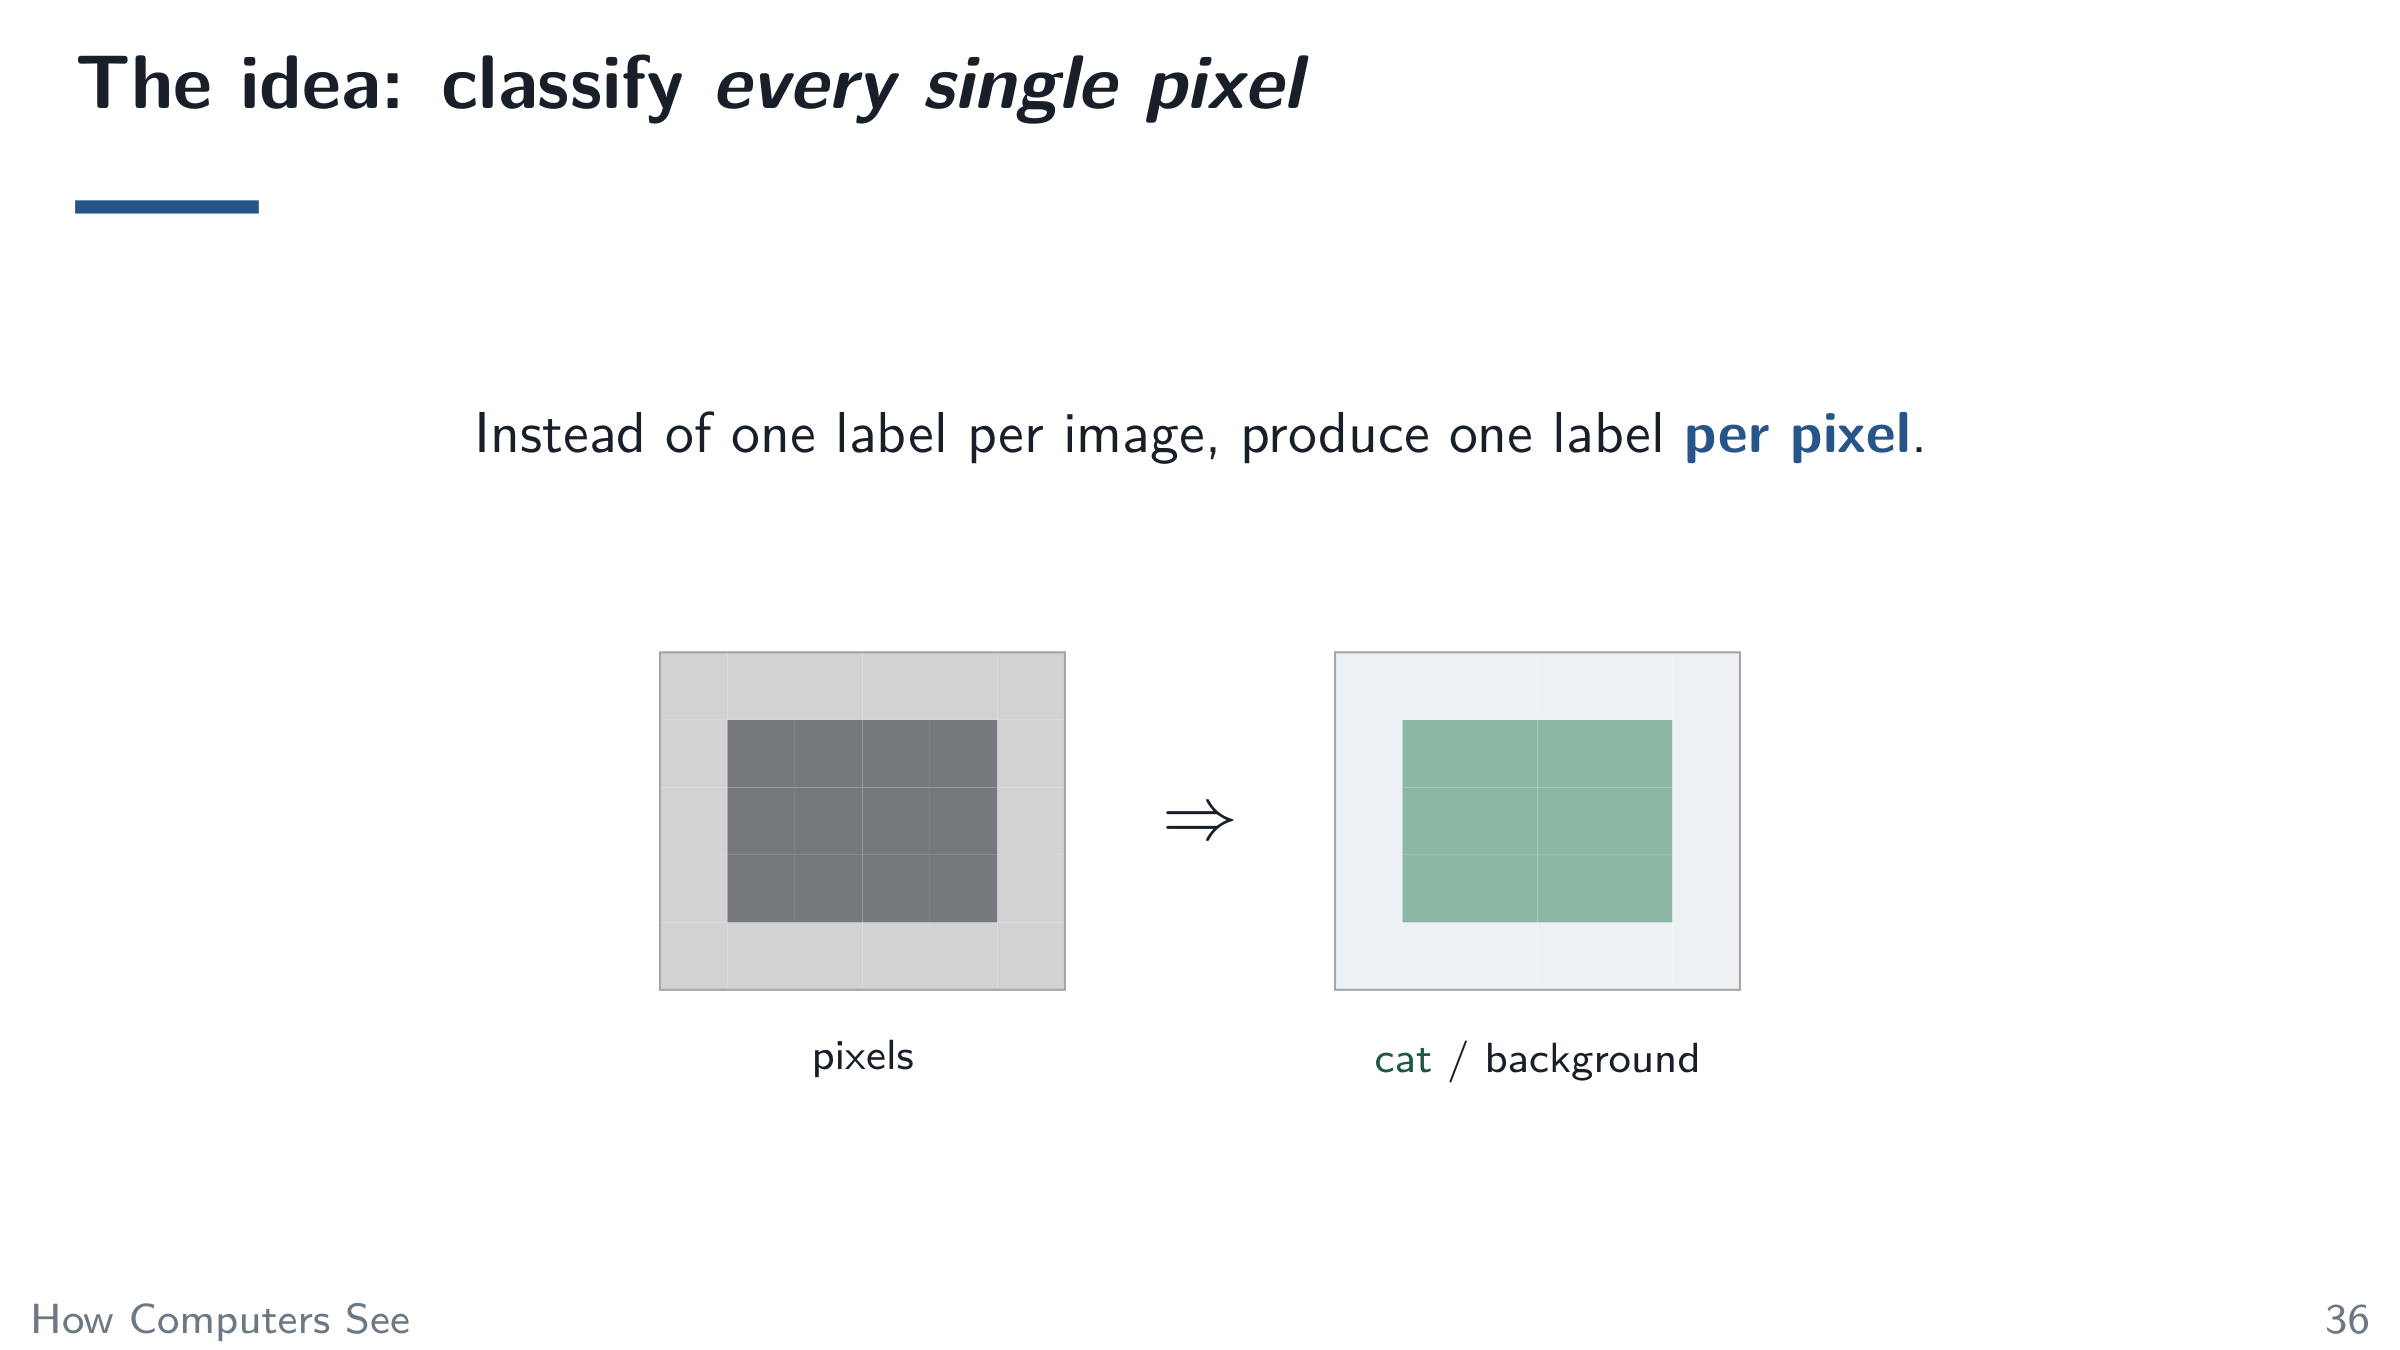
The idea: classify every single pixel
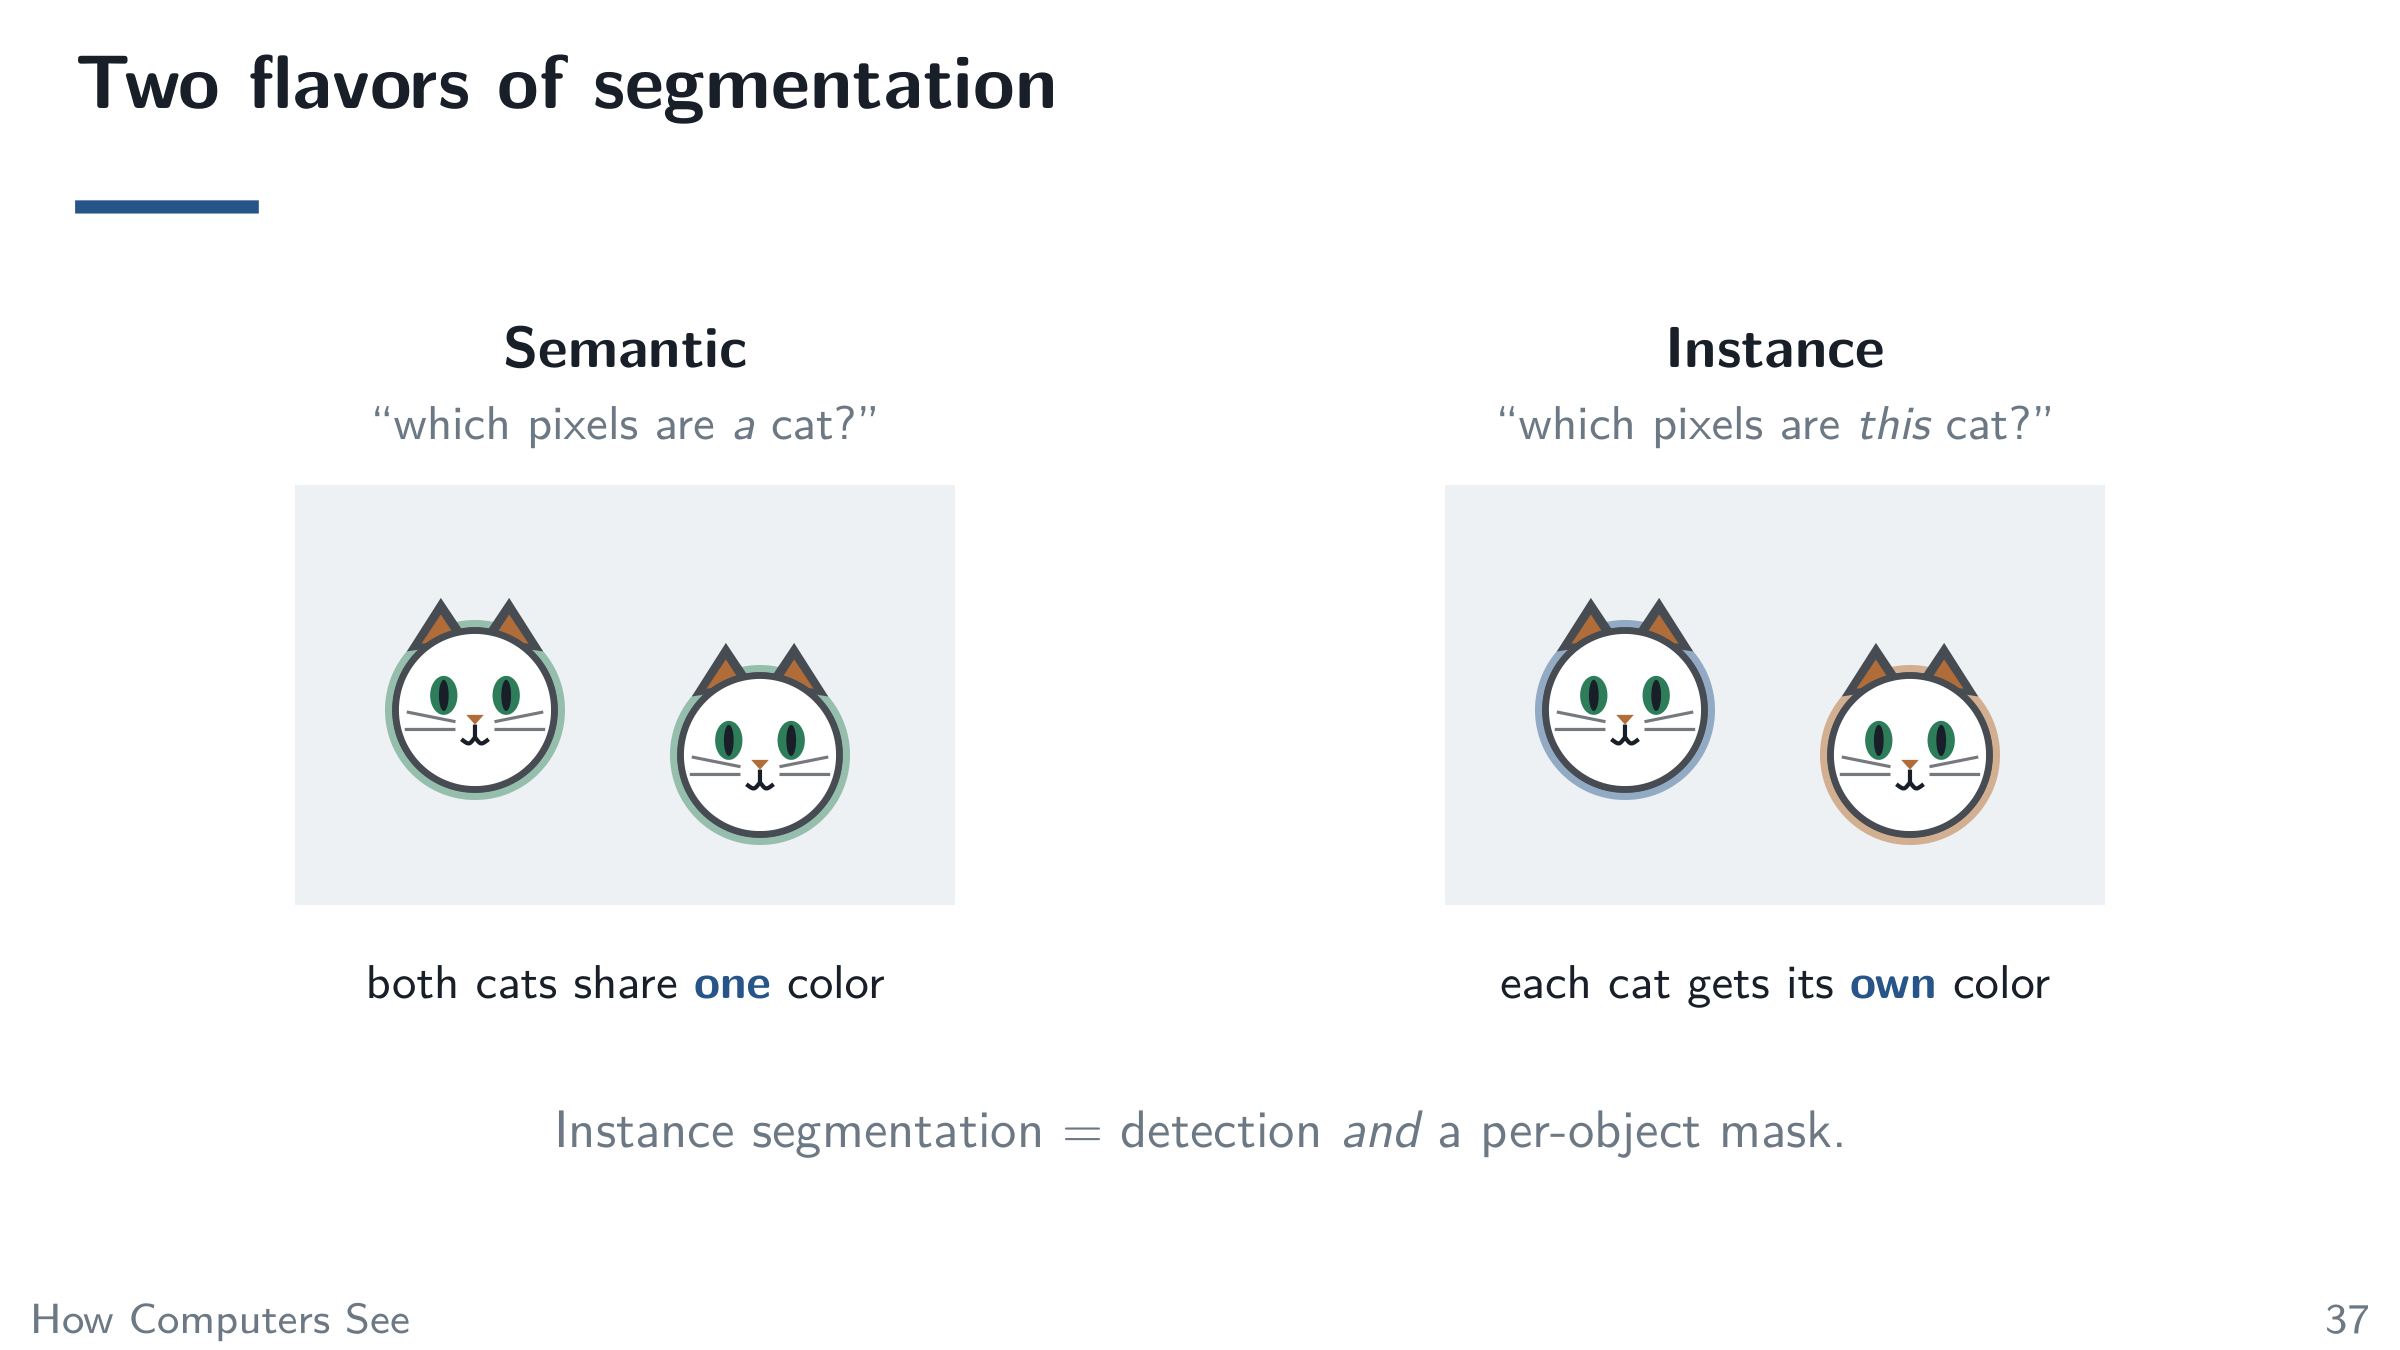
Two flavors of segmentation
Why go to all this trouble?
Demo: Paint the pixels ▶︎ Open Lab 4D
Image Understanding
Understanding asks: what is going on?
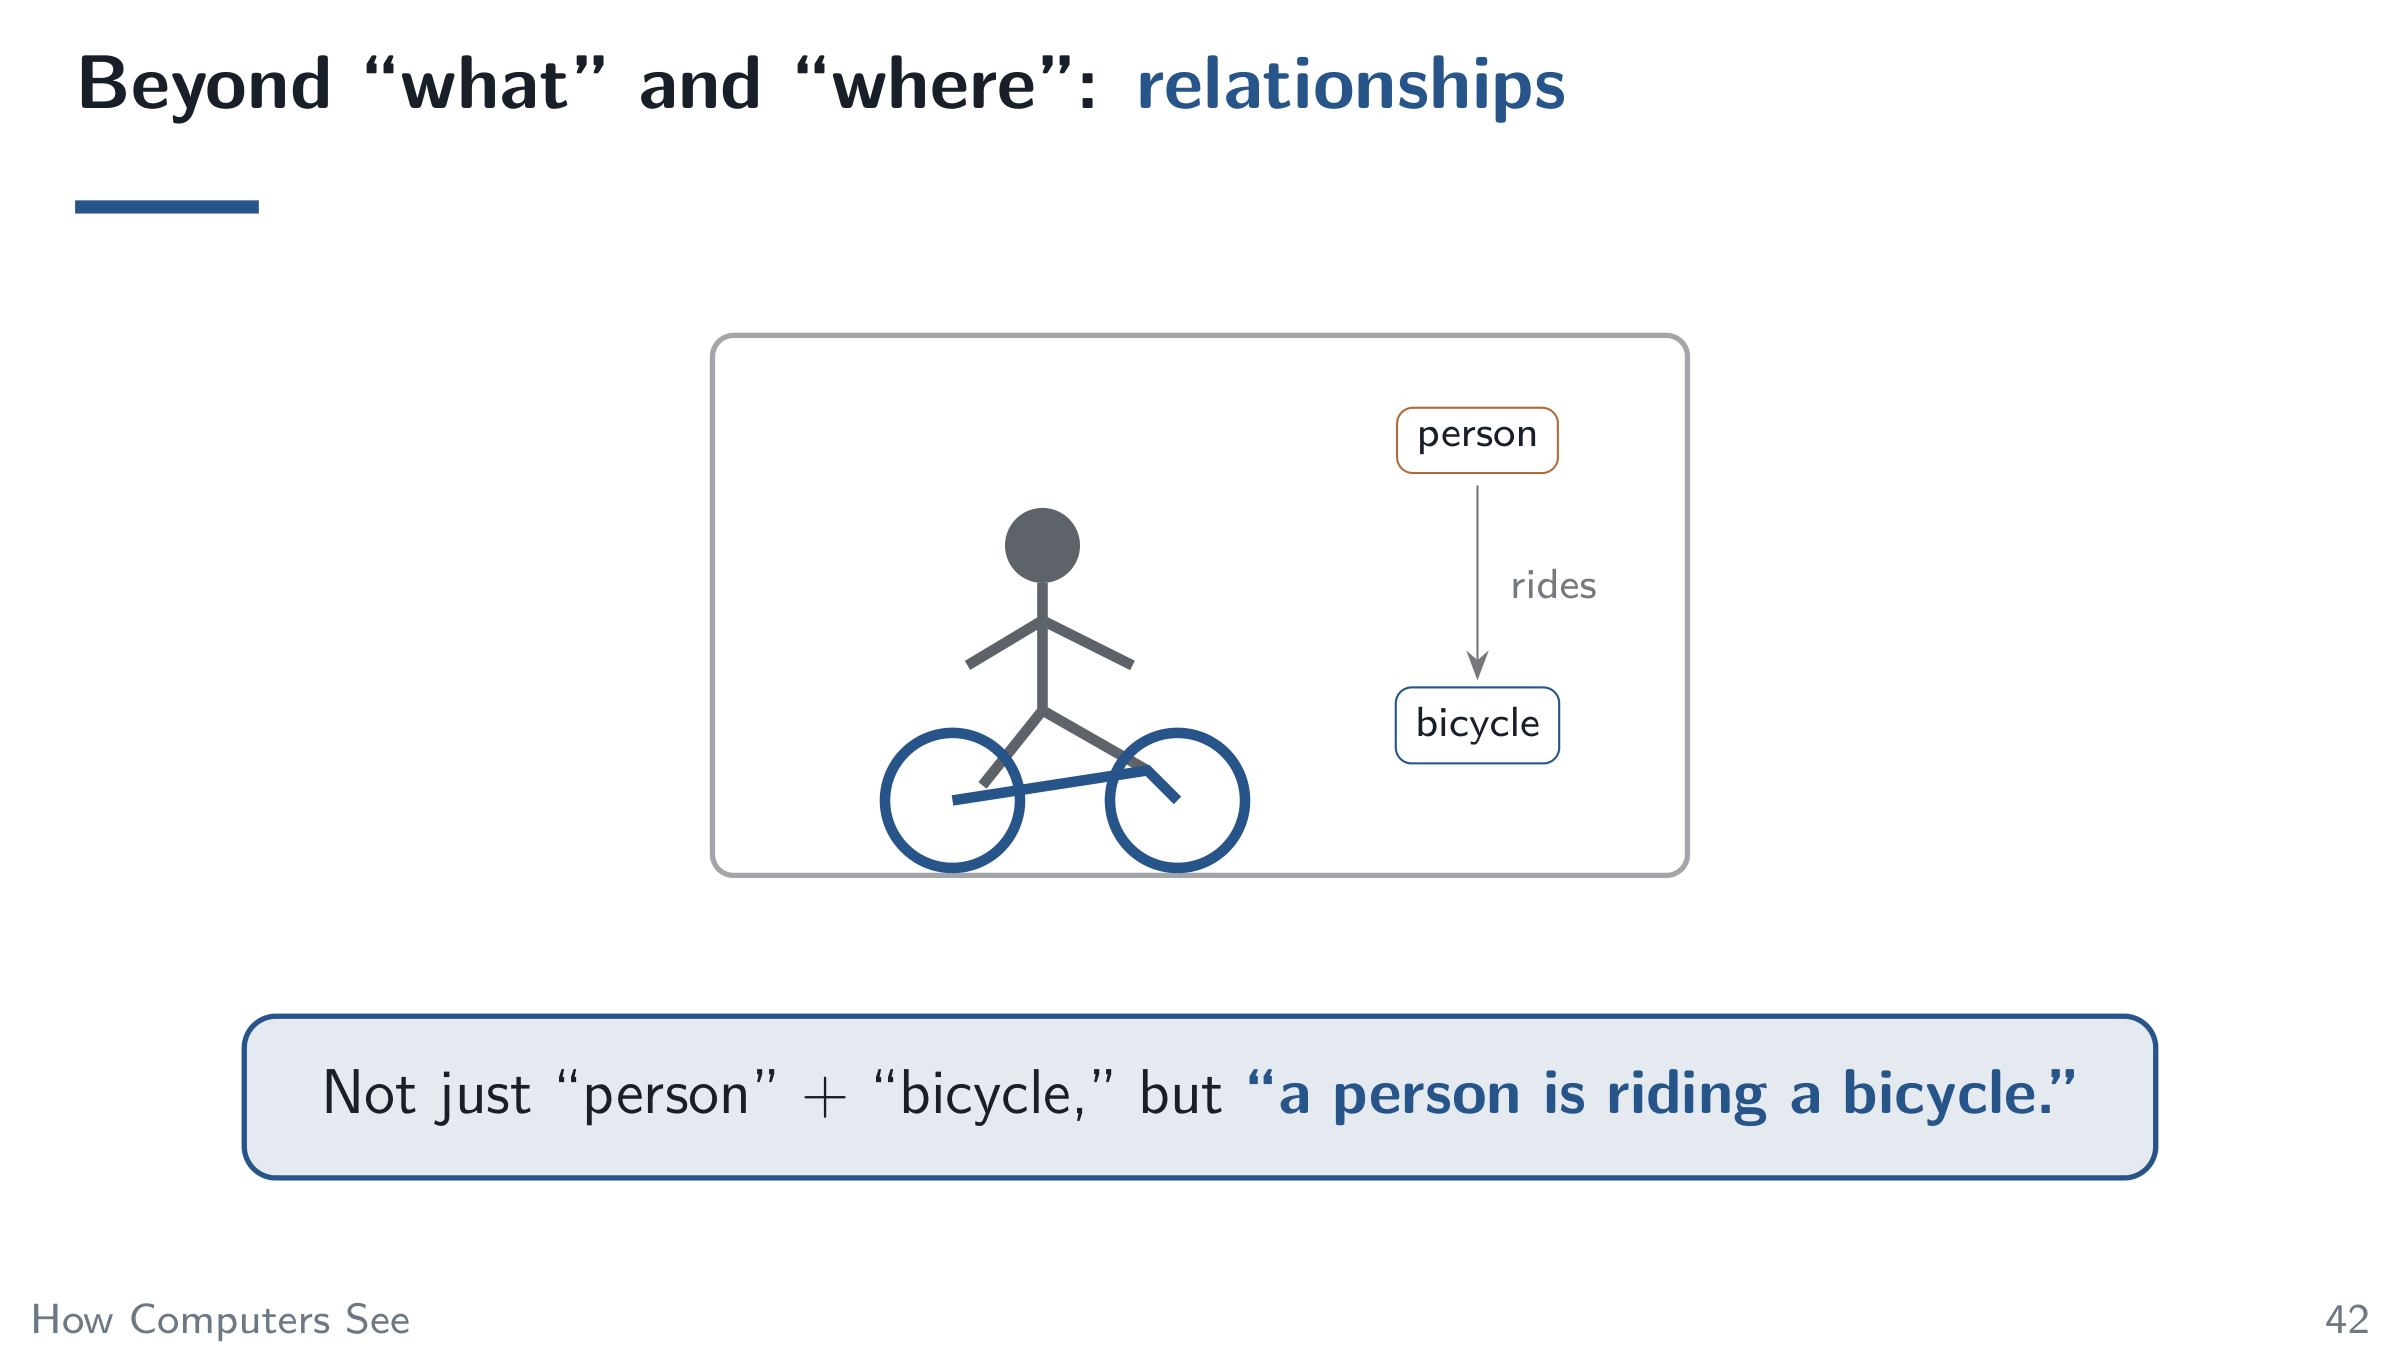
Beyond “what” and “where”: relationships
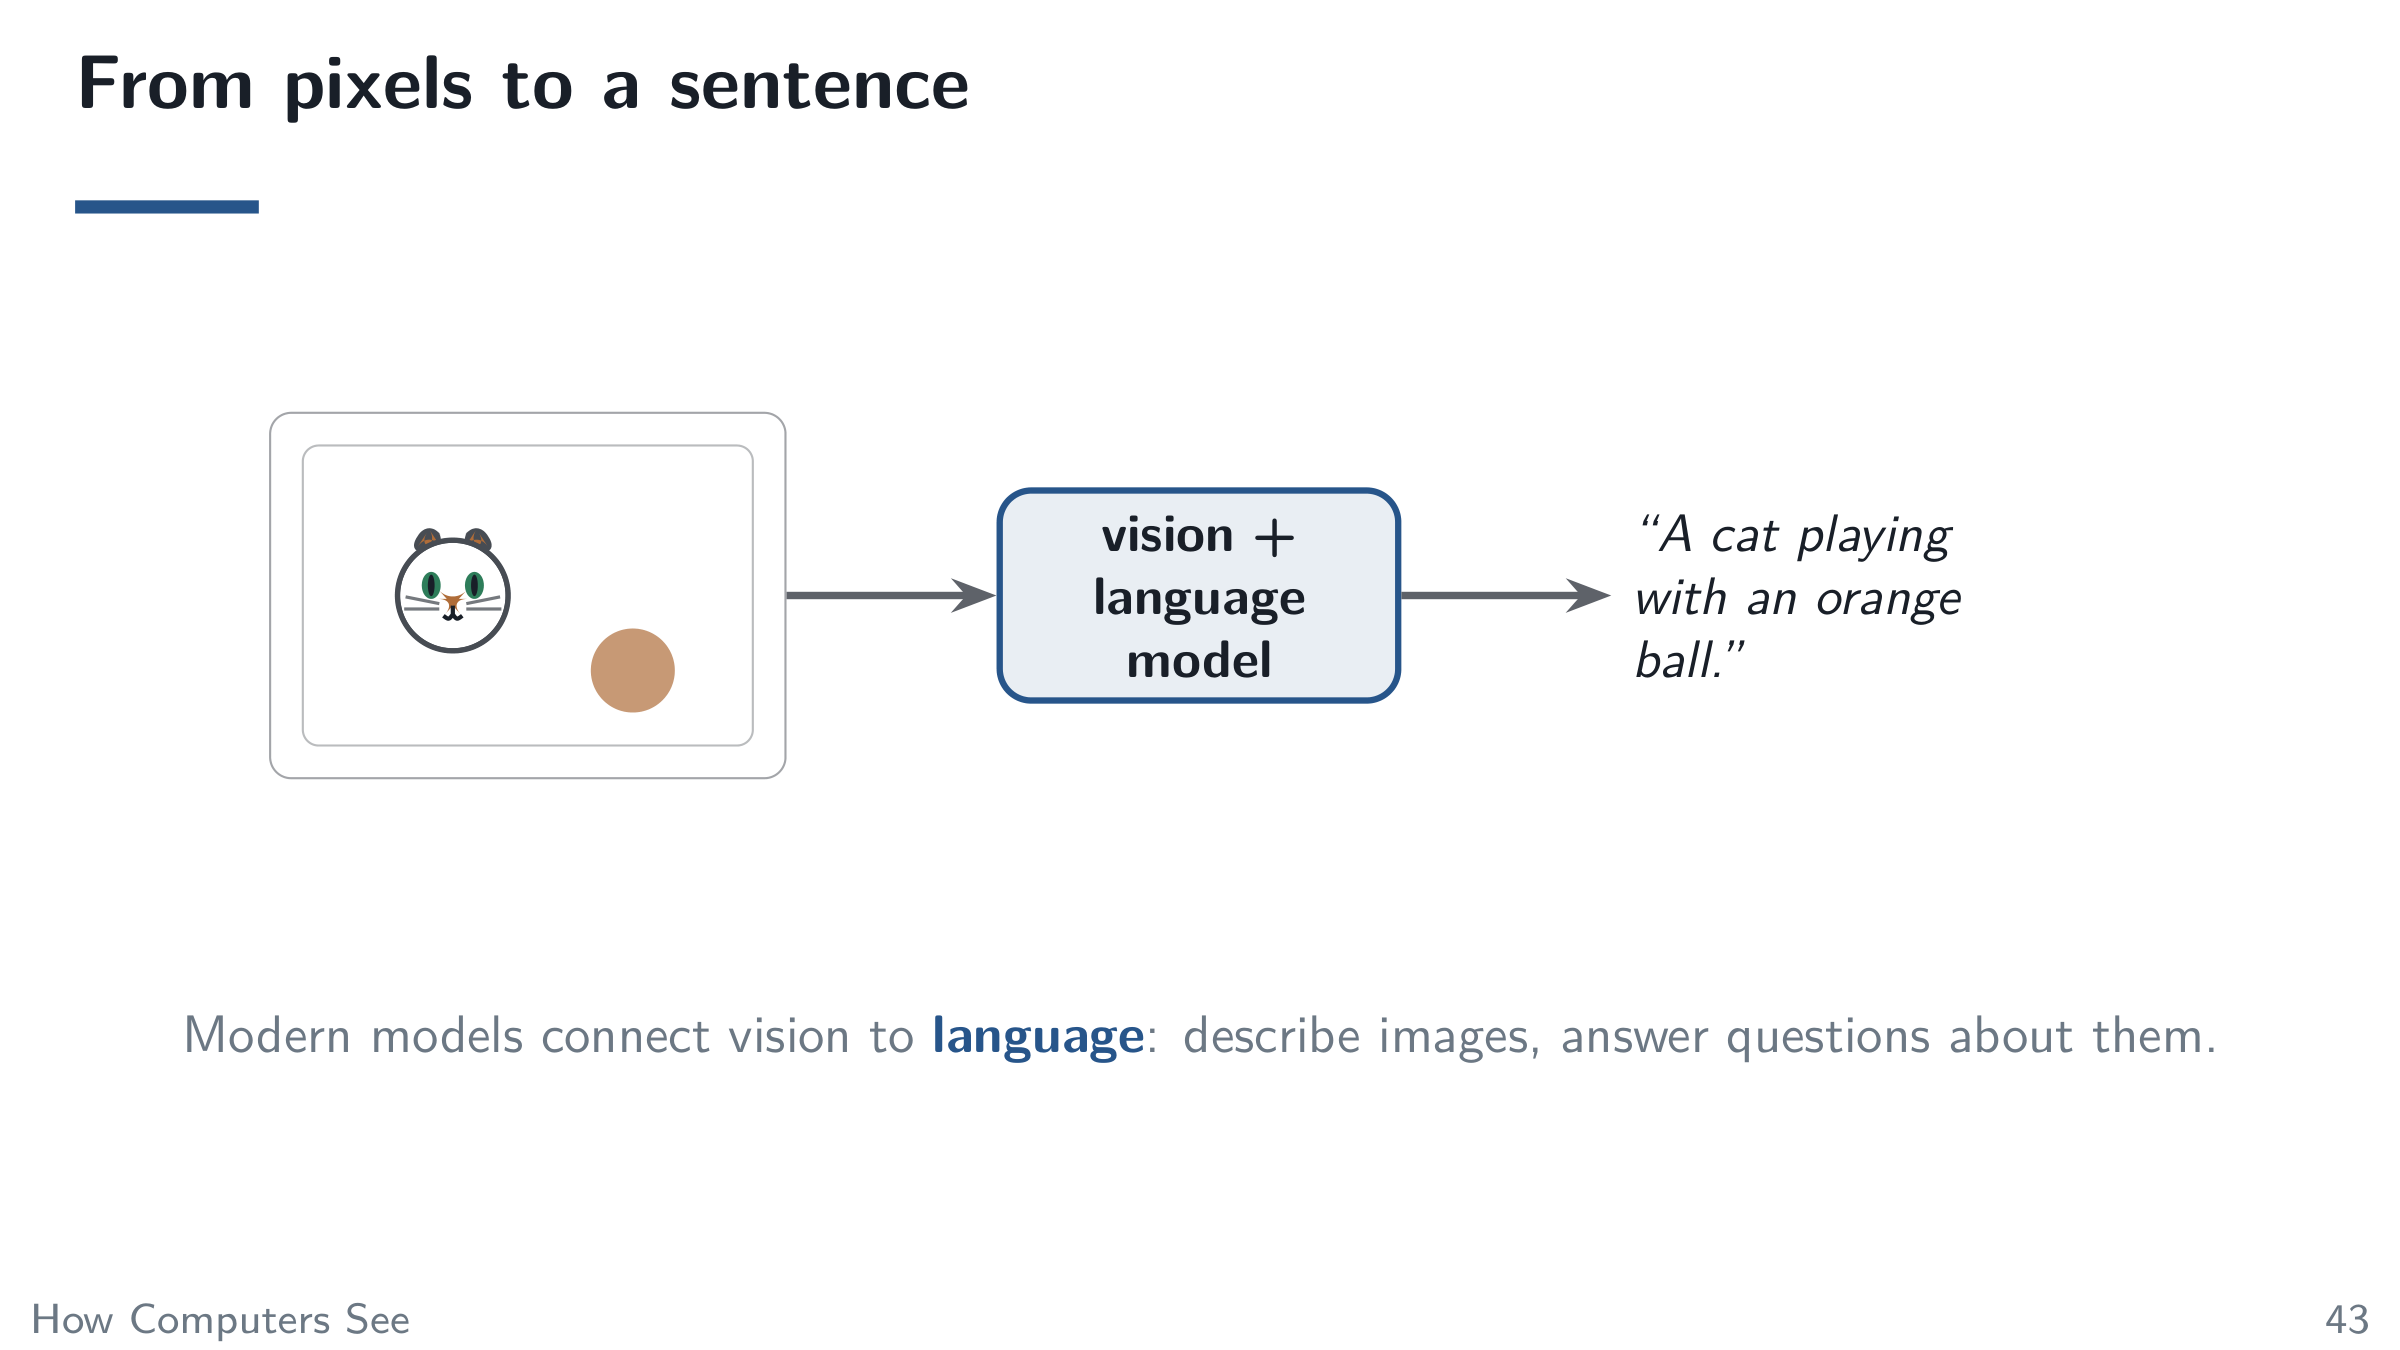
From pixels to a sentence
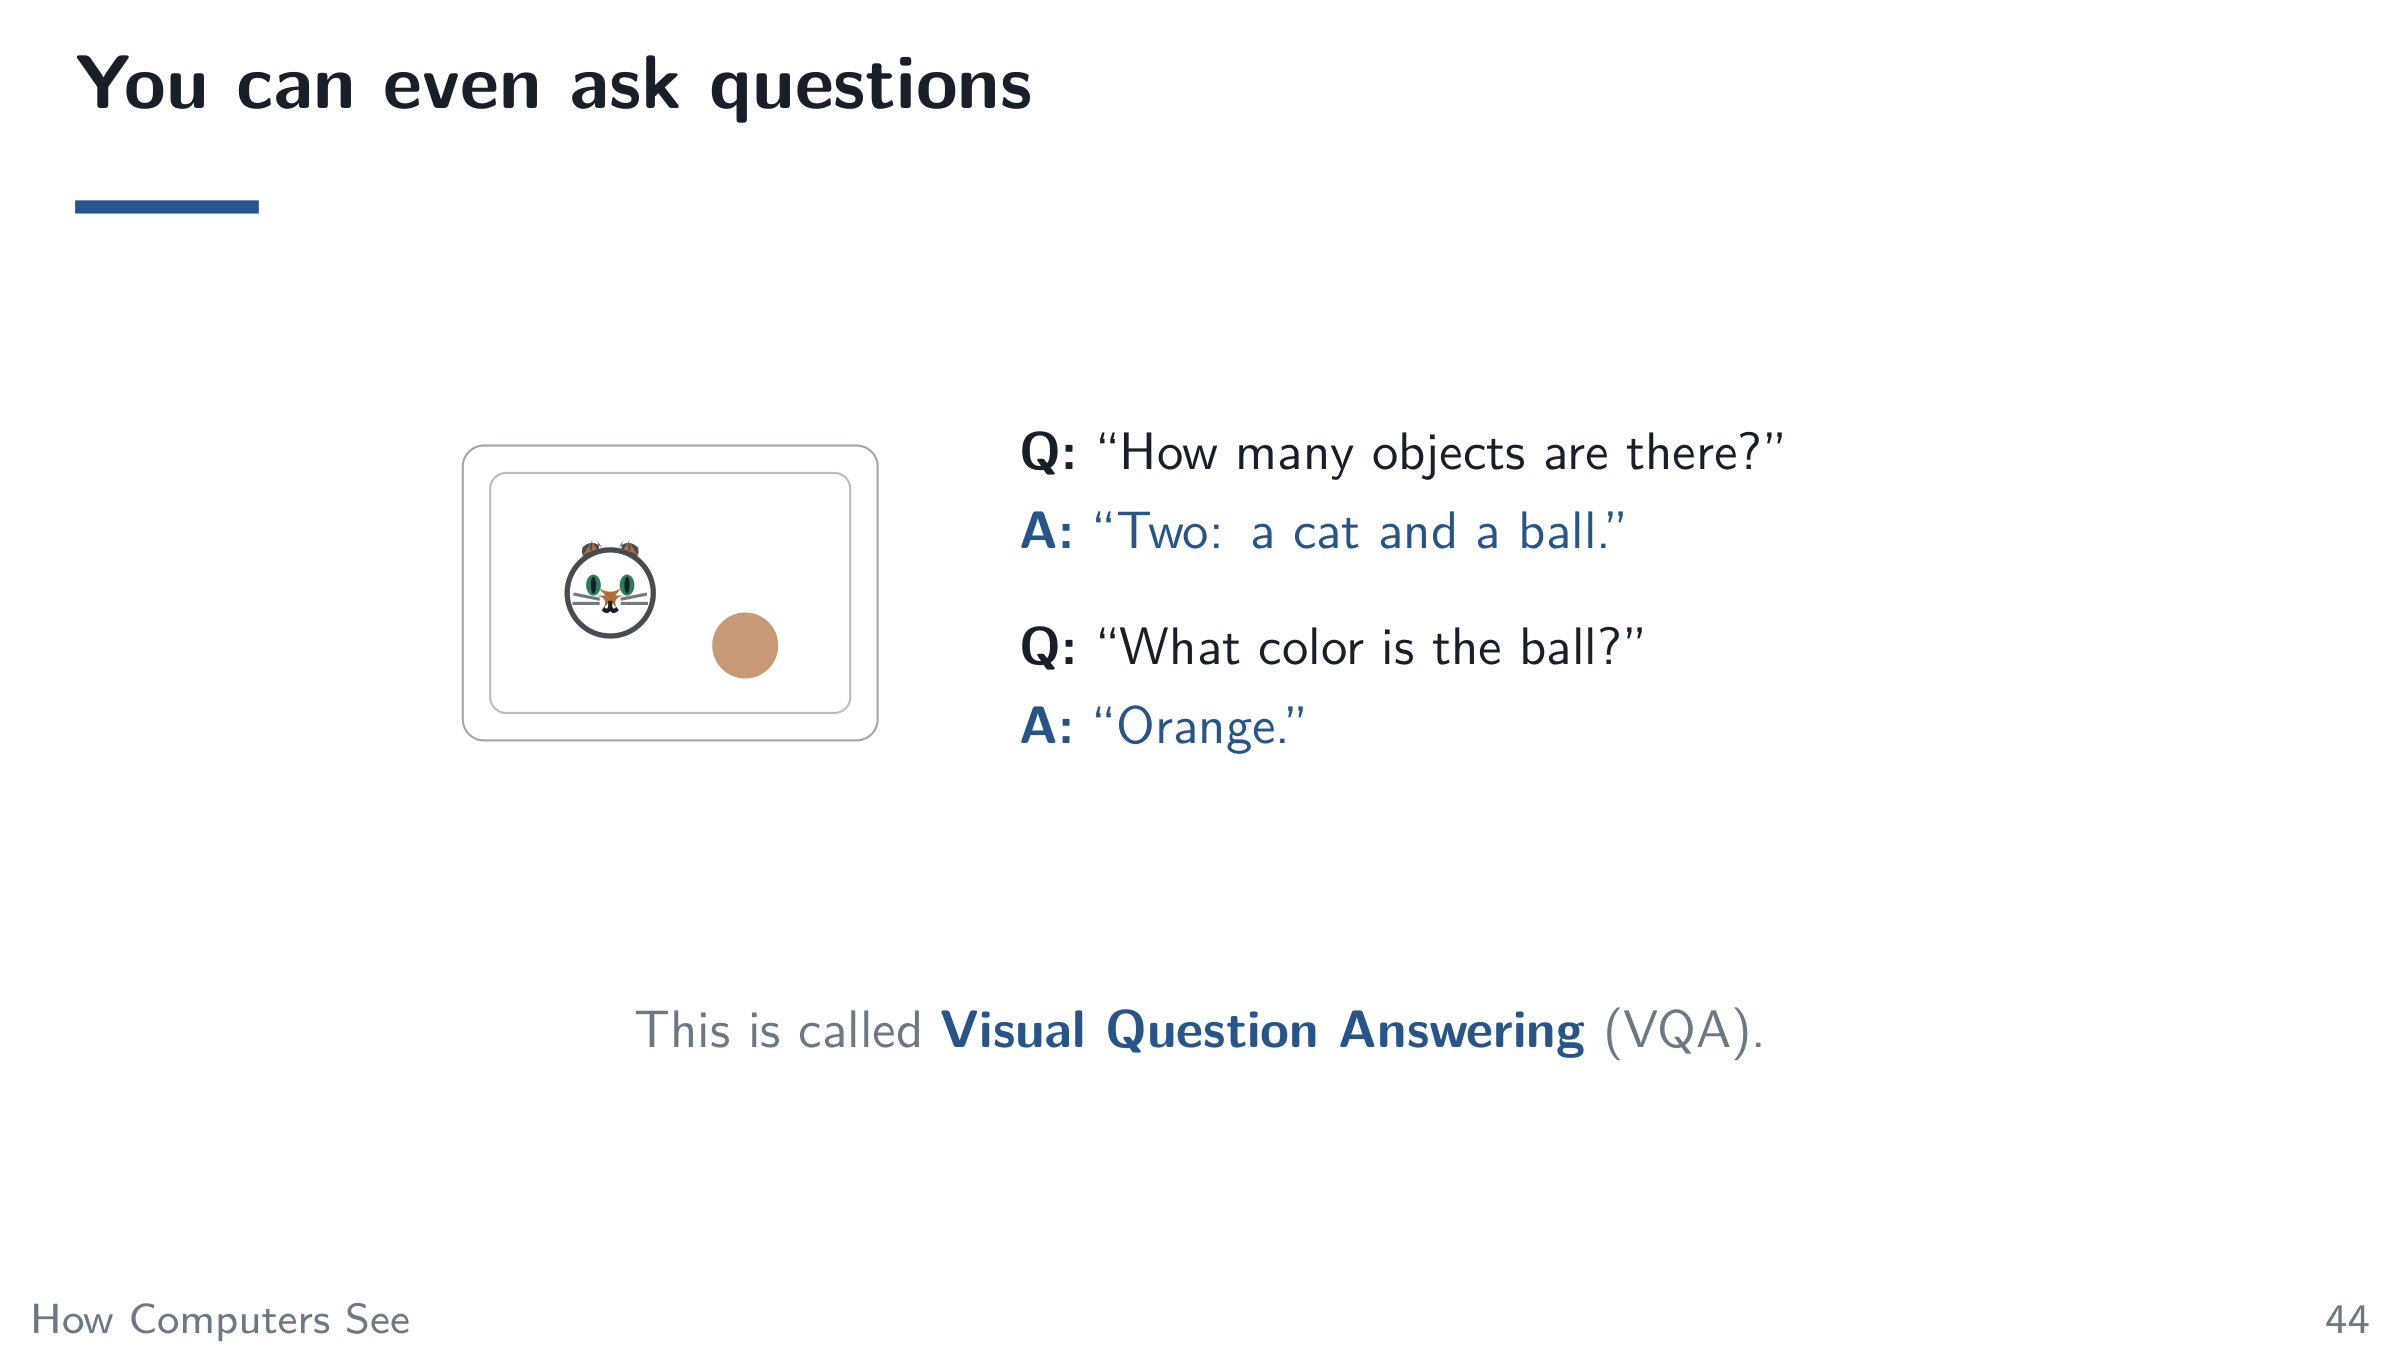
You can even ask questions
Understanding is still the frontier
Demo: Ask the image a question ▶︎ Open Lab 4E
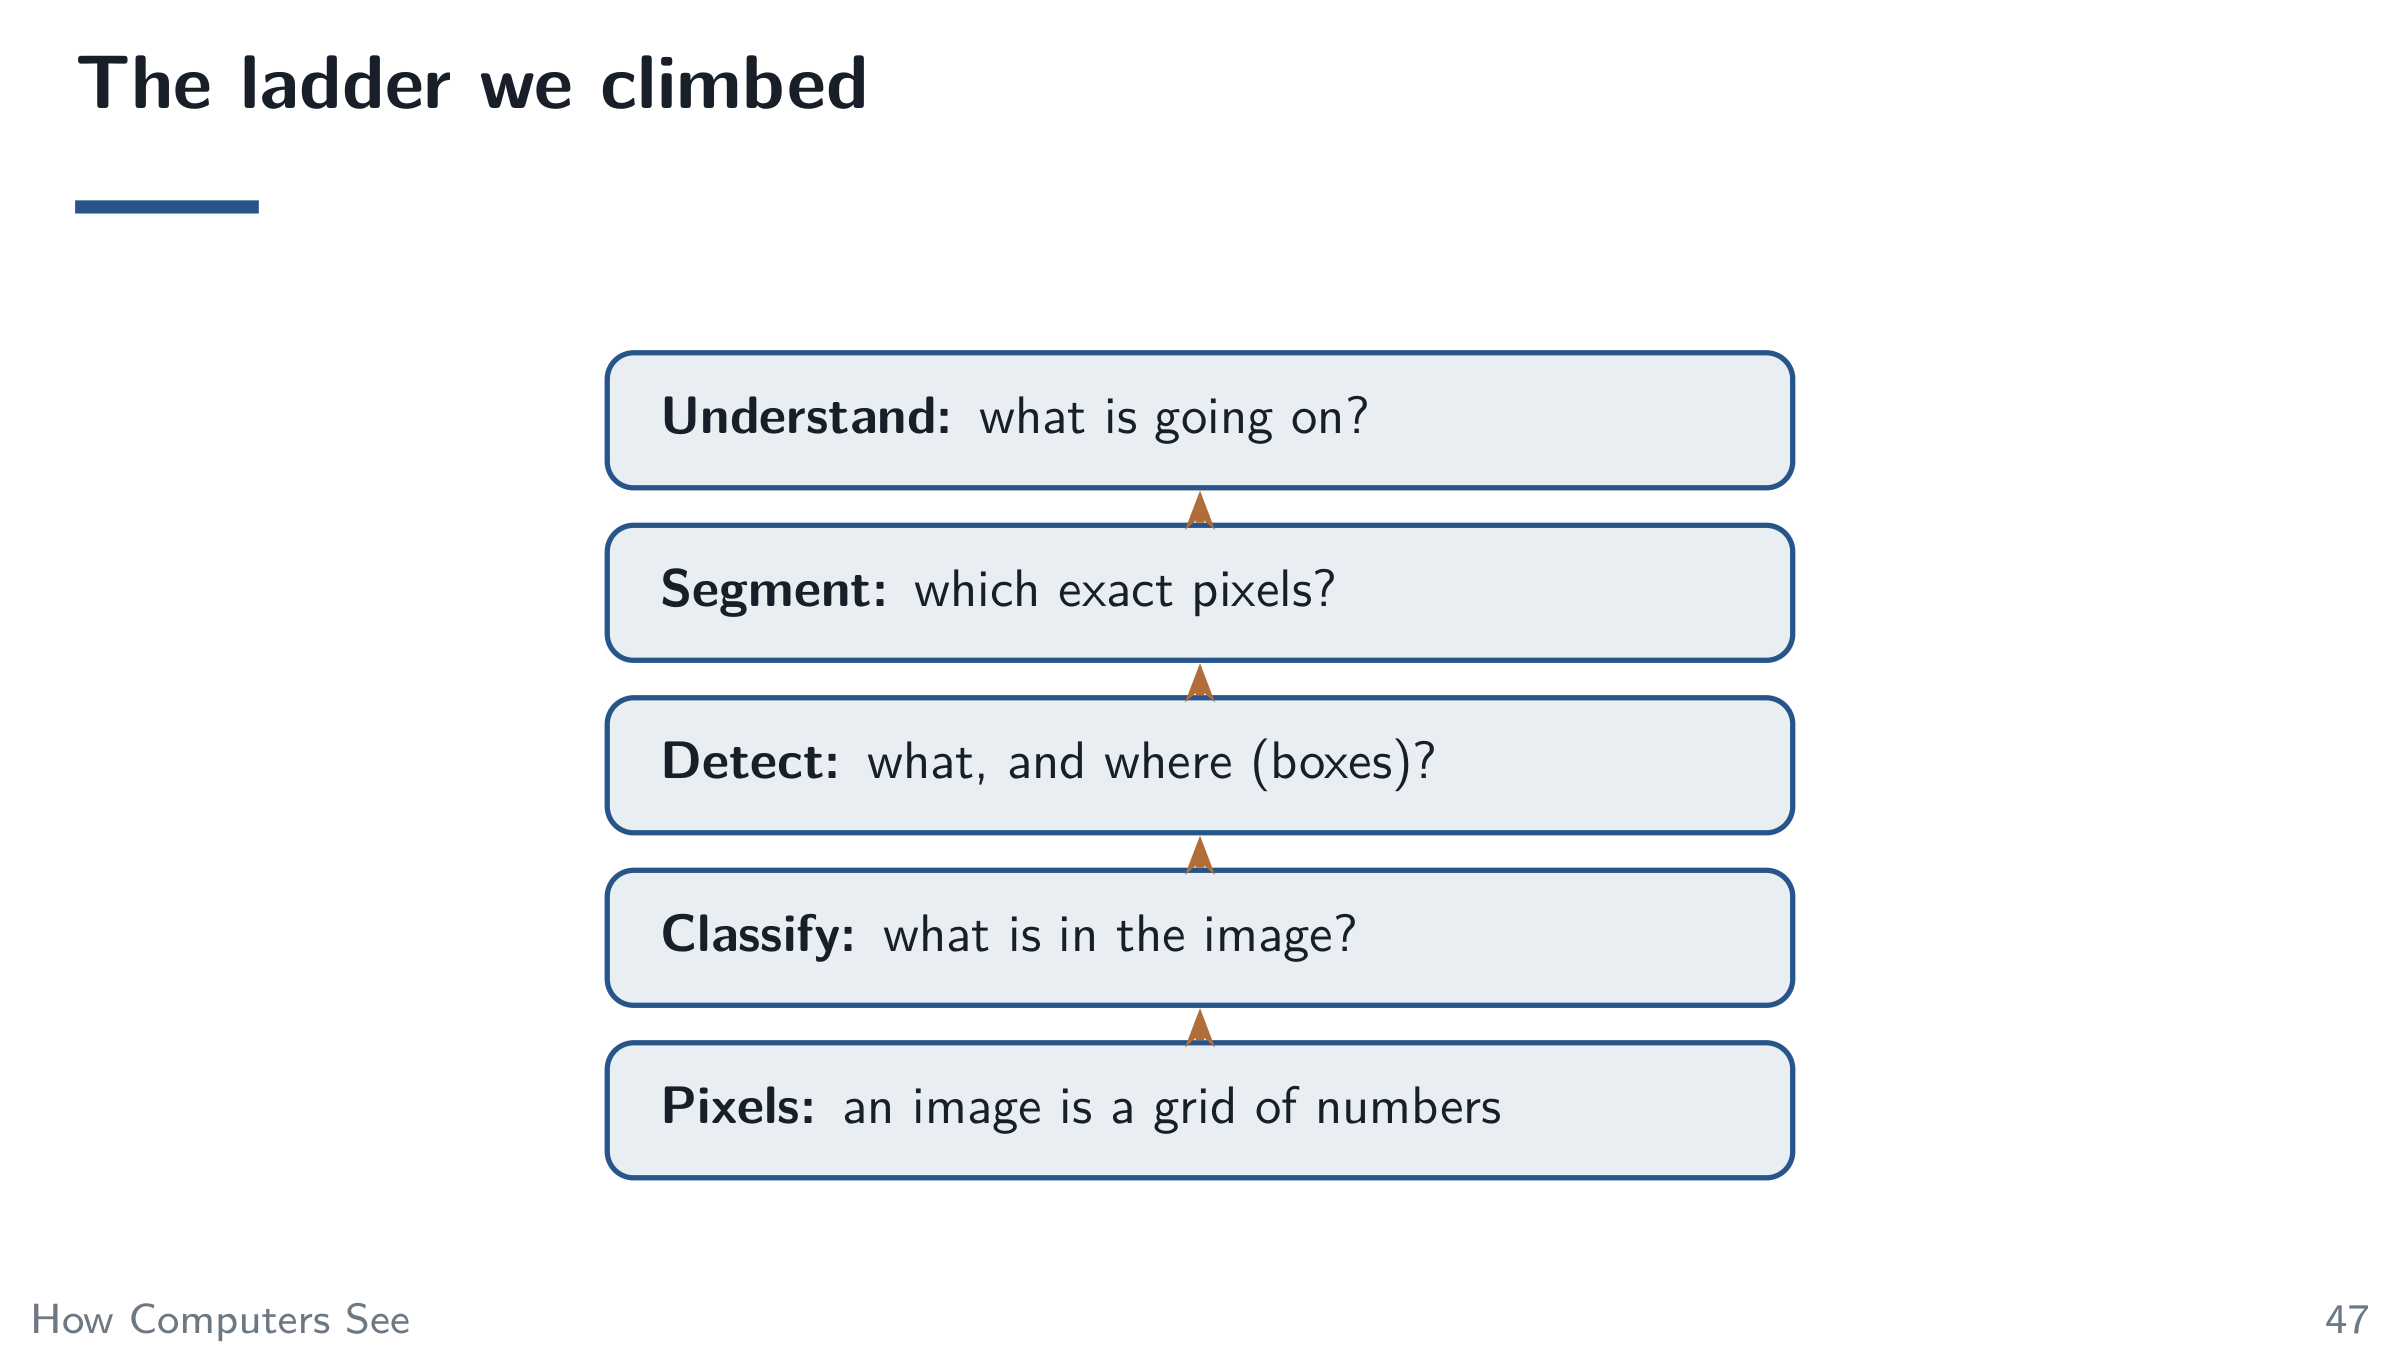
The ladder we climbed
Every step is just smarter math on a grid of numbers
Thank you — Questions?